Creating a Benchmark with Jetty
Here’s the uncomfortable truth about the benchmarks the ML community treats as ground truth: they’re often wrong. For example, a recent analysis from a popular LLM benchmark, found that 6.5% of questions contain errors. For instance over half of the questions in one category had problems: wrong answers, ambiguous phrasing, missing context.
Instead of relying on public benchmarks, Jetty gives you the tools to build a benchmark based on your AI workload.
A worked example
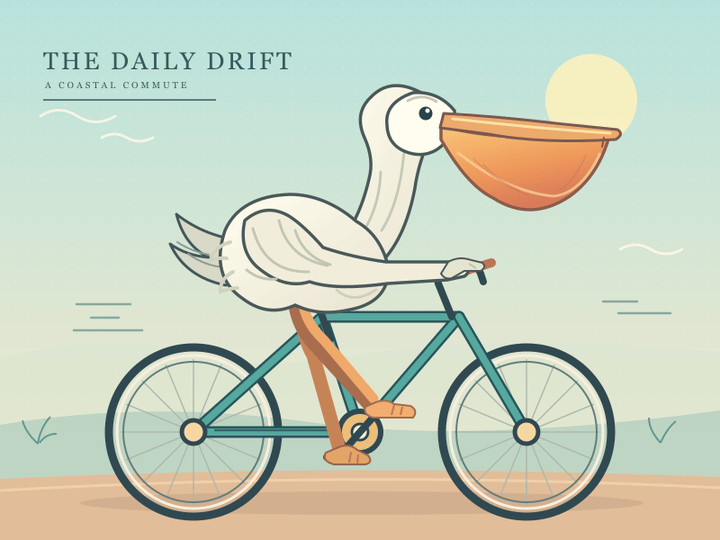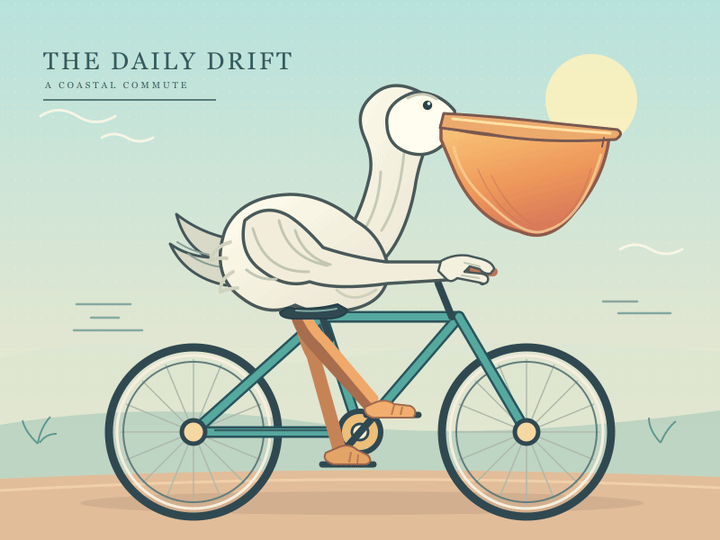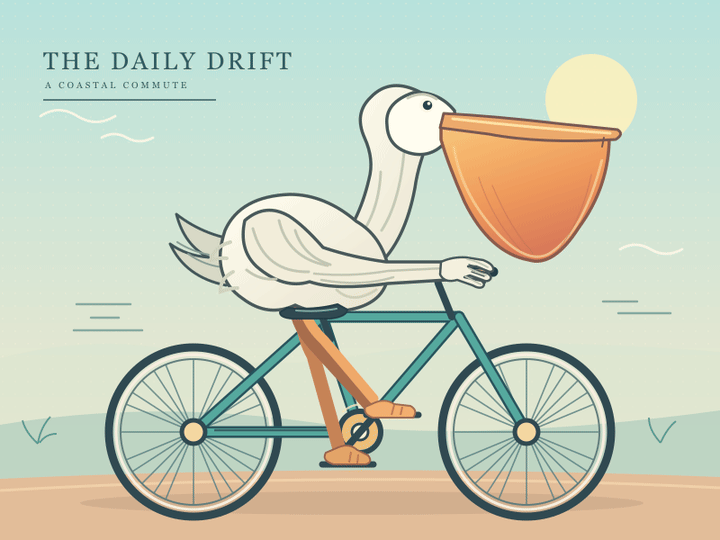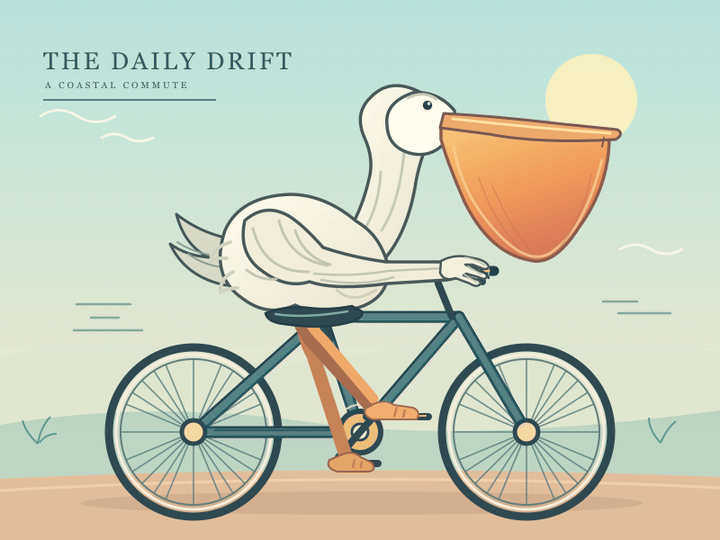
For the last year or so, Simon Willison has been asking every new model to generate an SVG of a pelican riding a bicycle and posting the results. It’s become the unofficial visual reasoning test for frontier models. So when people see the Jetty mascot, the assumption is that we picked the pelican as a wink at the benchmark.
Simon’s test exercises the layout, anatomy of two distinct objects and challenges the model's ability to keep coherent state across hundreds of XML elements. It’s visual enough that you can tell at a glance whether the model got it.
Three steps to getting started with custom benchmarks
Step 1: Decide what you're actually comparing
A benchmark needs one clear axis of comparison. Here are some ones that keep coming up with our users:
- Model comparison: same agent, same task, different model or provider, to find the best fit for cost and quality.
- Agent comparison: same task and model, different agent runtime (claude-code, codex, gemini-cli, and the rest), to see which handles your workflow best.
- Runbook or skill comparison: same model and agent, different instructions, to measure whether a prompt or skill change actually helped.
It’s a good idea to pick one dimension before you build anything since a benchmark that changes two variables at once can't tell you which one moved the result.
Since every run in Jetty includes the runtime configuration, alongside its inputs, outputs, and evaluation results, it becomes easy to do a deeper investigation with the same runs later. Start by looking at the pass rate, then where failures cluster, then cost and runtime alongside quality, since the tradeoff between a cheaper model and a higher pass rate is usually the actual decision.
Step 2: Write the runbook that defines the job
Collect the inputs your benchmark will run against, including the hard cases, not just the ones that always pass. If you're working on a deep research task, you may have ambiguous questions and ones with missing information. It’s best to use these as the files and parameters your runbook will reference or require as inputs to a run.
A runbook is the spec for the benchmark task itself: one markdown file with YAML frontmatter for defaults, a setup section, the steps the agent follows, and an evaluations section for scoring. The frontmatter sets the starting point for agent, model, and sandbox, but none of it is locked in, which matters for the next step.
The four parts, the frontmatter fields and the evaluation styles are covered in full on the Runbooks page.
Step 3: Run & Investigate the results
The evaluations section is what turns a batch of runs into an actual benchmark instead of a pile of transcripts. Jetty gives you three tools, and a real benchmark usually needs more than one of them:
- Code checks for anything with a deterministic answer: did the output file exist, is it valid JSON, does a number reconcile. These never flake, and a failed code check overrides a judge's verdict, so use them for anything that has a clear right answer.
- Checklists for plain-language conditions the agent works through before finishing, like “the response names the specific policy it's citing.”
- Judges for the subjective quality question a code check can't answer. An LLM judge is fast and cheap for a plain scoring question; an agent judge, a separate grader run with tool access, costs more but catches things a single model call misses.
A benchmark that only uses one of these is usually missing something: code checks alone miss quality, judges alone miss the objective failures a script would catch instantly.
Run the full task set against each candidate, in parallel, so the comparison happens under the same conditions at the same time rather than across however many days it takes to click through it manually.
Schedule future runs on a cadence, or trigger them with a webhook whenever a prompt, model, or skill changes, so that drift shows up automatically instead of getting discovered by an angry user. The same runbook that defined the one-off comparison is the one that keeps running, unchanged, every time you need to check whether something got better or worse.
Where this fits with everything else
Building a benchmark this way uses the same discipline behind evaluating runs at scale and comparing models: a fixed task set, evaluation built into the workload instead of bolted on after, and every configuration stored automatically so the comparison is reproducible instead of a one-time impression. The benchmark isn't a separate system sitting next to your agent work, it's the same runbooks and runs you're already using, pointed at a fixed task set on purpose.
Build one
Start with one runbook, one task set, and one axis of comparison. Sign up for Jetty and turn your next “which model is actually better” argument into a run you can point to.