Your agent ships code. Who checks it?
Your agent says it's done. Jetty checks its work.
Every run gets scored automatically against checks, checklists, and judges. Pass, fail, or unknown. No partial credit, no manual review, no digging through transcripts to find out if it actually worked.
What customers say
Read the Dial0 story“Jetty lets me hand off complex, multistep workload and trust they’ll run reliably and consistently, so I can focus on creating.”
Read the Nous Research story“Jetty helped me run hundreds of long agent trajectories in parallel — cleanly and organized for analysis.”
1k
Verified outputs · Dial0
37
Runbook improvements · Dial0
+15k
Runs · Nous Research
8
Avg. evals / run · Nous
What the evaluation report looks like
Every run ends here, scored against your checks.
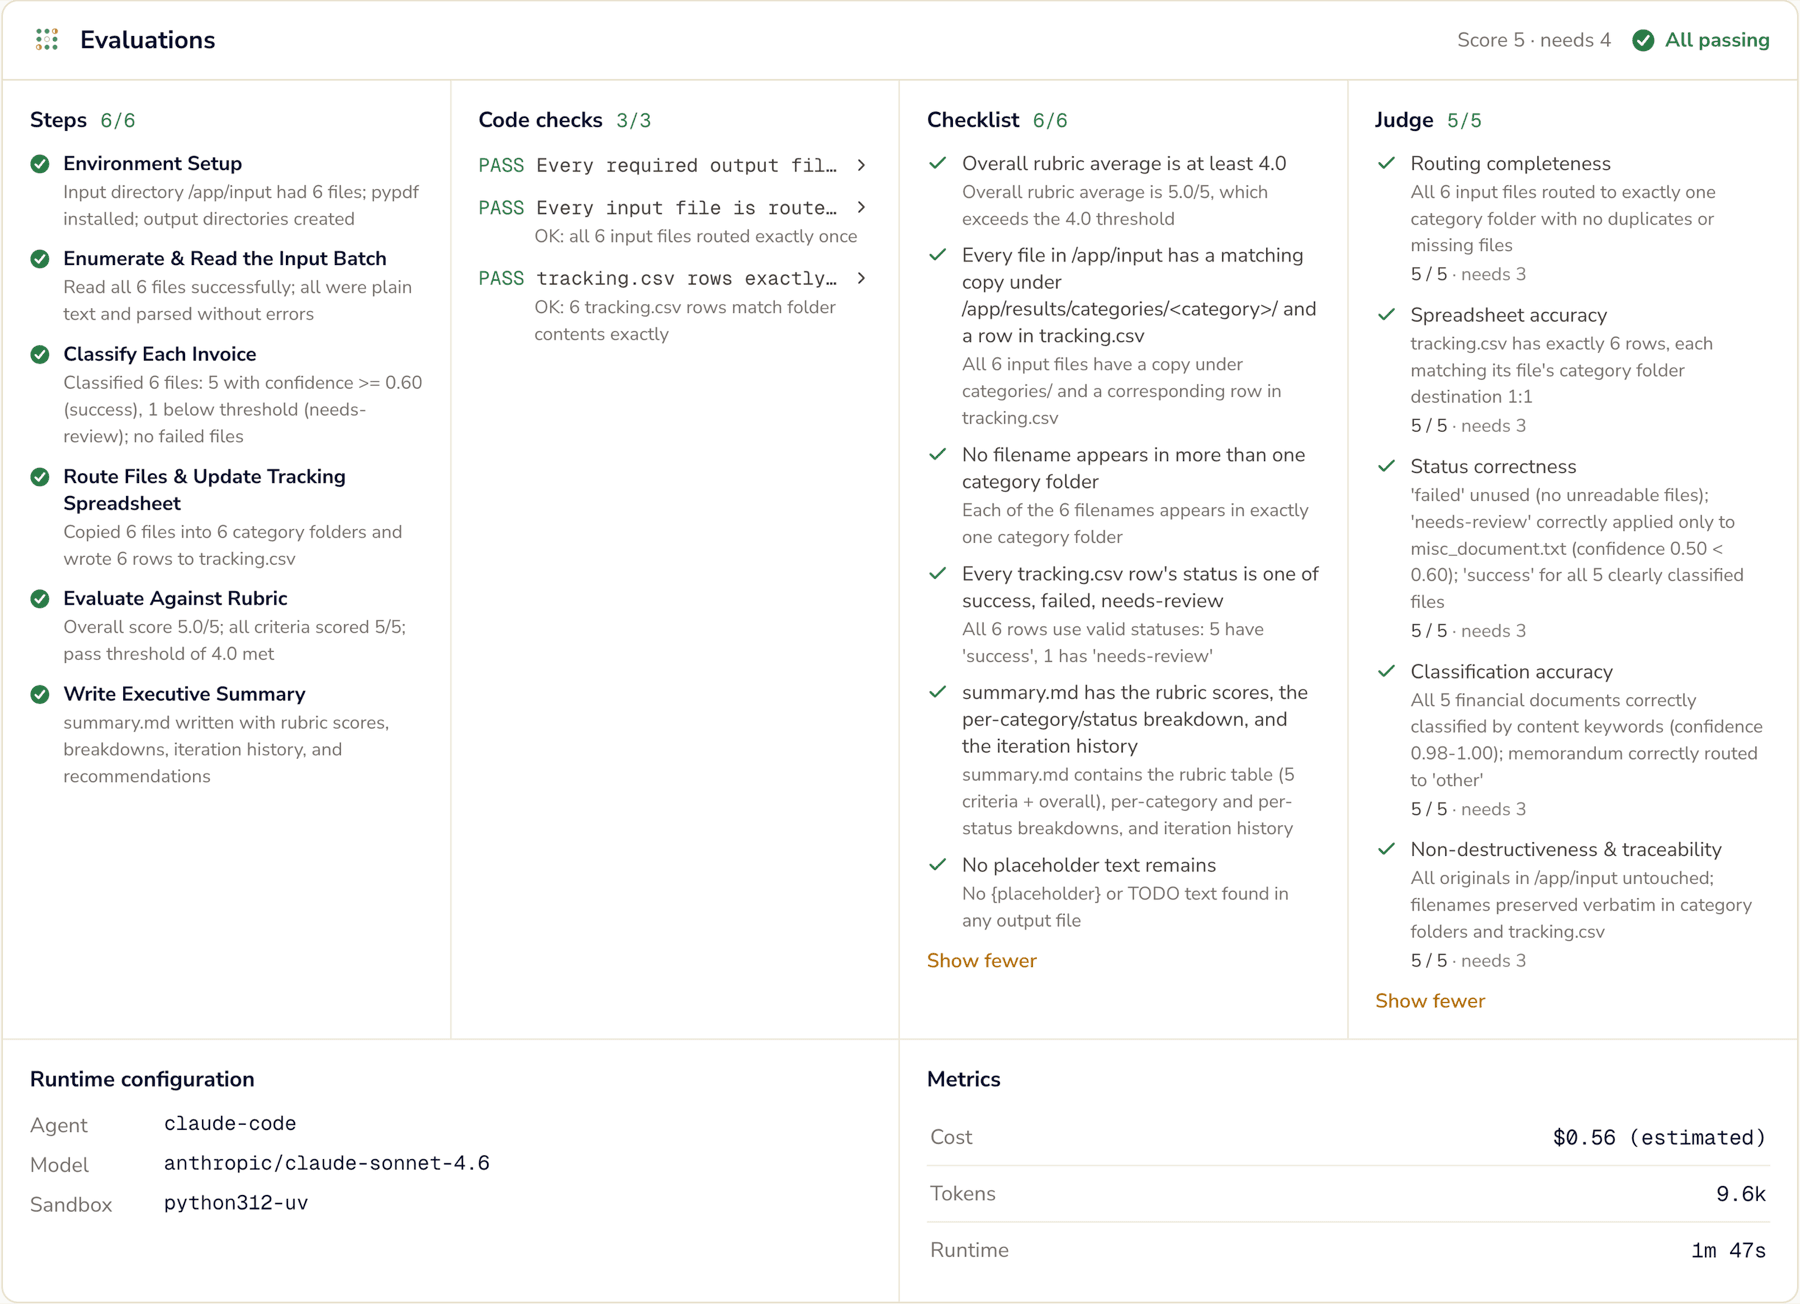
- Code checks
- — deterministic, Jetty-run checks against the actual output files, each with the command and evidence that made it pass.
- Checklist
- — plain-language conditions the agent confirms by inspection, each with the specific evidence behind the verdict.
- Runtime configuration
- — exactly which agent, model and sandbox the run used, so a result can be reproduced or compared.
- Metrics
- — what the run cost in dollars, tokens and wall-clock time.
Connected to your stack
A workload rarely runs alone
It gets triggered by someone or something, reads from the tools your team already uses, and reports back out — starting with the agent that does the work.
Integration
GitHub
Give a runbook a fine-grained token for one repository, then push a branch and open a pull request from every run.
Read the GitHub guideIntegration
Slack
Give a runbook its own bot token with just chat:write, then post results and confirm each one by its permalink.
Read the Slack guideAdd your agent
Bring the agent you already use
Paste one line into Claude Code, Codex, Cursor or any agent that can fetch a URL — it reads Jetty's setup instructions and installs itself.
Read the agent guide> Guide me through installing jetty.io/agent-instructions.md…
Frequently asked questions
Models, evals, and where Jetty fits.
How does Jetty work?
Jetty runs AI workloads from plain-language instructions called runbooks. Each workload runs in a sandbox, paired with a coding agent, a model and the integrations it needs. You provide an objective and define the evaluation criteria; Jetty puts together the steps to produce the outcome, records every run, and lets you evaluate and share the results from the web interface. The product overview walks through the full loop: author, run, investigate, improve.
What is the best LLM model for my AI workloads?
Chasing a “best” model on a leaderboard is a waste of time. The model that matters is the one that performs on your task, your budget, and your skill. Public leaderboards and benchmarks are usually far too generic to indicate actual performance in your environment. They are also costly to run, and important details are usually left out of the rankings. Jetty is model-agnostic by design, so you can launch your own investigations with your own agent and model pair and let your own eval suite decide.
How do I evaluate AI agent outputs at scale?
Researchers keep diaries and maintain results over weeks and months to build good intuition. Good news: with Jetty your runs are already organized for evaluation. Every config is stored automatically, so nothing gets lost. Read the failure modes each run kicks back and use them for the next iteration. You can launch hundreds of jobs, close your laptop, and come back to real answers instead of a mountain of logs sitting on your machine.
What’s the difference between an eval and a test?
A test answers one narrow question: does this match the expected output? Pass or fail, done. That’s fine for deterministic code, but it’s not enough for agents. An eval answers the question that actually matters: is this good? Does the agent use the skill right, reason well, get the job done? It is judged across dozens or hundreds of runs, not just one. Tests catch what’s broken, evals show you what’s working and how much better it’s getting each round, and these days you need both.
Why are there so many different ways to evaluate agents?
AI agents need different kinds of checks, and one kind of evaluation can only answer one kind of question. As AI workloads get longer, they often need several guard rails to keep them on task. Jetty handles this by letting you set standards as code checks, checklists and judges.
Why do I need code checks, checklists and judges?
Code checks are often necessary, but not sufficient, for good-quality agent outputs. Did the output render? Did the report include citations? Did the video run at 24 fps? A code check doesn’t rely on a model to test the output.
Some things the agent should confirm before it is done, like checking the names on every flagged receipt or making sure every cell in a table is filled in correctly. That is a checklist. It stops the agent quitting early, but it only guards against errors you already know about.
A judge evaluates what a code check can’t touch: did the agent solve the right problem, write something maintainable, make a sane tradeoff when the spec was ambiguous? Judges work best across many runs as part of a broader investigation.
Together, these evaluation tools set the standard for your agents.
Updated
Start running evaluated AI workloads today
Free to start — 12 runs a month, no credit card required.
Get Started free