How to start with Jetty: bring your first workload
Jetty is a platform for running and evaluating AI workloads. You describe a job in a runbook, a configuration file that defines the task, and the agent and model will run the task, with jetty checking whether the result is good. Jetty runs that job in a managed sandbox, scores the output against your checks, and keeps a full record of every run so you can compare one attempt against the next.
This walkthrough covers the two fastest ways to bring a first workload into Jetty: the web app's built-in authoring tool, and your terminal, through the coding agent you already use or a plain shell client. Both produce the same kind of tracked, evaluated run.
What you need before you start
- A Jetty account. The free Scoop plan covers free runs.
- Optional: API keys for whichever AI Gateway you want runs to use. Your first runs can use Jetty's own gateway.
- For the terminal path: a coding agent that can fetch a URL and run shell commands, or git, curl and jq for the shell client.
Path 1: the web app's authoring agent
When you sign up, Jetty walks new accounts through a short three-step tour of the dashboard. The tour itself is worth knowing about before you start, because it tells you both things this guide covers: your dashboard is where every run lives once it's underway. You can start your first runbook either from the Author Runbooks screen in the web app.
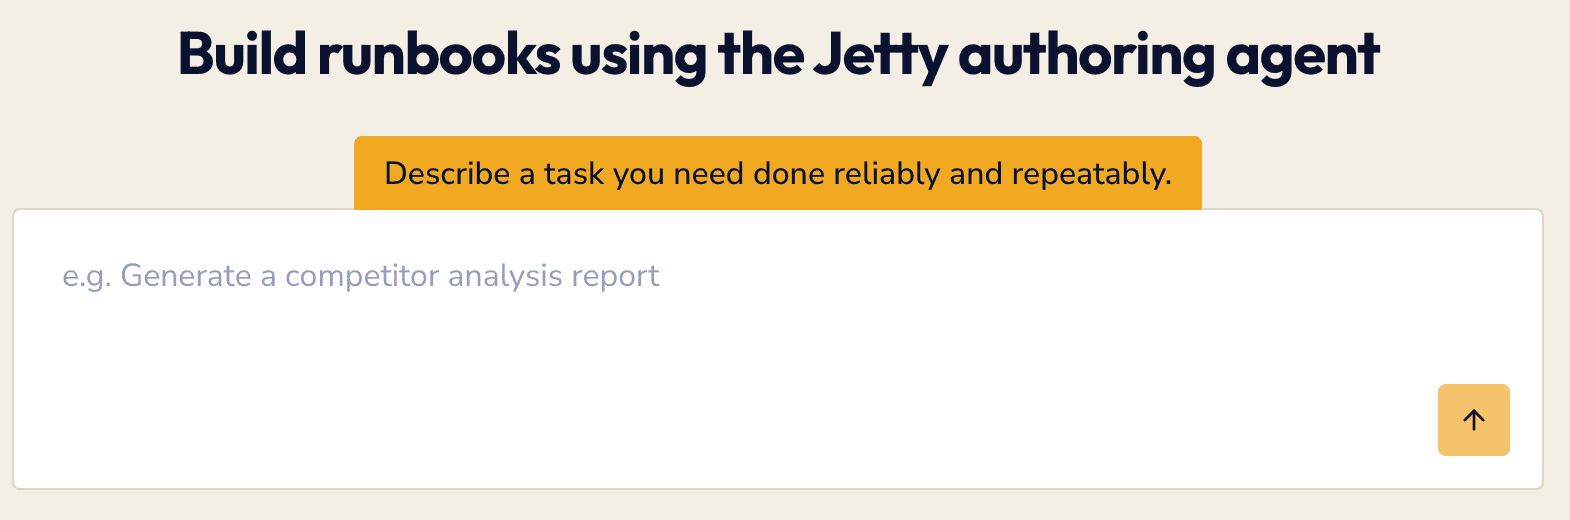
Author Runbooks is a single prompt box. The heading "Build runbooks using the Jetty authoring agent," asks you to describe a task you need done reliably and repeatably, with an example placeholder along the lines of "Generate a competitor analysis report." The agent behind the box has a name: Pelly, after Jetty's pelican mascot. The onboarding tour explains the mechanism plainly: tell Pelly what you need done, and it turns that description into a repeatable runbook you can run anytime.
To try it:
- From the dashboard sidebar, open Author Runbooks.
- Describe the job the way you'd brief a person doing it for the first time rather than a prompt template. Write what the output should contain, not just the topic. Pelly has more to work with from "a one-page comparison of three competitors' pricing pages, as a markdown table" than from "competitor research."
- Submit it.
- Pelly opens a dedicated authoring screen built around four stages: Define runbook → Run → Evaluate → Optimize. The first stage is a back-and-forth, conversation: Pelly confirms the task back to you in a chat panel on one side, while a draft runbook fills in live on the right pane, a rendered preview of the runbook is filled in. Reply in the chat to correct or add detail, the draft updates as you go.
- Once the instructions look right, move through Run and Evaluate, and from that point every run is tracked the same way regardless of how the runbook got written: inputs and configuration, the full agent transcript, and the evaluation results.
Path 2: from your terminal
If you'd rather work from your terminal, there are two ways in, and both end at the same tracked, evaluated run as Path 1. The quickest is to let the coding agent you already use install Jetty for itself. The other is a shell client you source into your own session, for scripting without an agent in the loop.
Let your agent install itself. Jetty publishes its setup procedure as machine-readable instructions at https://jetty.io/agent-instructions.md: numbered steps written for the agent rather than for you, with the points that need a human marked as such, and a report-back block at the end. Paste one line into Claude Code, Codex, Cursor, or any agent that can fetch a URL and run shell commands:
Guide me through installing https://www.jetty.io/agent-instructions.md and setting up my first runbook.The agent reads the instructions, looks for an existing token at ~/.config/jetty/token, stops only where it needs you (pasting an API key or signing up, and adding your own provider keys if you skip the free trial), stores the key, and hands off to the runbook wizard. The deeper reference it consults along the way is https://jetty.io/MACHINE_CONTEXT.md. The same prompt sits on the jetty.io home page and on the Bring Your Agent docs page, with a copy button.
Or install the plugin yourself. In Claude Code, two commands add Jetty's plugin marketplace and install the plugin, which bundles the MCP server with four skills: jetty, jetty-setup, create-runbook and optimize-runbook. Then run the setup wizard once:
claude plugin marketplace add jettyio/jettyio-skills
claude plugin install jetty@jetty
/jetty-setup
The wizard creates or links your account, writes your token to ~/.config/jetty/token, and checks that your provider keys are in place. Codex and OpenCode have plugin manifests in the same repository. Editors that speak MCP but not skills, Cursor, VS Code, Windsurf, Zed, add the server on its own, npx -y jetty-mcp-server with JETTY_API_TOKEN in its environment, and point the agent at agent-instructions.md for onboarding.
The shell client, for scripting without an agent. Jetty has no standalone binary yet. The shell client is a bash script in the same repository as the skills; it needs git, curl and jq:
git clone https://github.com/jettyio/jettyio-skills.git
source jettyio-skills/skills/jetty/jetty-cli.sh
Authenticate with an API key from Settings → API Keys in the web app (it starts with mlc_):
export JETTY_API_TOKEN="mlc_your_token_here"A handful of commands cover a first workload end to end. Your workspace holds your runbooks, and a task is a runbook deployed inside it. The CLI and API name a workspace collection:
jetty_health, confirms the client can reach your accountjetty_collections, lists your workspacesjetty_tasks my-workspace, lists the runbooks deployed in a workspacejetty_run my-workspace my-task '{"vars": {"input_file": "sample.pdf"}}', starts a run and returns its workflow id; the runbook's parameters travel undervarsjetty_trajectories my-workspace my-task, lists recent runs with their statusjetty_trajectory my-workspace my-task <run id>, pulls one run's full record, steps and outputs includedjetty_help, the full command reference
Start runs with jetty_run rather than jetty_run_sync: a synchronous call that outlasts about 100 seconds returns a gateway timeout while the run carries on in Jetty, so start the run, then poll it. Don't retry the start, a retry launches a second run.
This path fits better once you're scripting a workload into something else, a CI pipeline, a scheduled job, your own internal tooling, rather than exploring interactively.
Writing a runbook directly
Both paths eventually hand you a runbook: one markdown file with frontmatter for the agent, model, and sandbox, an objective, steps, evaluations, and a declared list of required output files. The bare minimum, stripped down to just what's needed to run, looks like this:
---
agent: claude-code
model: claude-sonnet-5
---
# Summarize a document

## Steps
1. Read {{input_file}} and produce a plain-language summary under 200 words.

## Checklist
- Confirm the summary doesn't introduce any fact not in the source document.

## Required output files
- results/summary.md
That covers the essentials, but it's deliberately pared down. What Pelly actually generates through Author Runbooks carries more frontmatter than this, a declared evaluation approach, an explicit sandbox image, a provider-routed model, and a secrets block for anything the job needs credentials for, plus a fuller Objective section up top and a table instead of a bullet list for required outputs. Authoring your first runbook, a companion guide, takes a draft like that to a passing run, with a full worked example, and the Runbooks page covers the parts of the file.
Pick what counts as "done"
Whichever path produced the runbook, the evaluation is what makes a run worth tracking rather than just producing output. Evaluations are written into the runbook next to the instructions, Jetty carries them out as part of every run, and their results add up to one verdict per run: pass, fail, or unknown when nothing was decided. The runbook's frontmatter names one of two patterns, evaluation: rubric for output whose quality has several dimensions (reports, summaries, images) and evaluation: programmatic for output with a right answer (structured data, extraction, code), and either pattern can carry three kinds of check:
- Code checks, commands that give a deterministic pass or fail, in two kinds told apart by who runs them. An agent check is run by the agent itself, with its own tools, before it writes its report, so a failure gets fixed inside its fix-and-recheck loop; the result is the agent's word, and a check it leaves out is recorded as skipped. A Jetty check is a command or built-in check that Jetty runs in the sandbox after the agent has finished (the files exist, the JSON parses, the totals reconcile), out of the agent's reach, so it can neither skip it nor misreport it, and a failure goes straight to the verdict.
- Checklists, plain-language conditions the agent confirms by inspecting its own output before reporting done, with a bounded number of fix-and-recheck rounds, three in the templates. Like agent checks, an item left out is recorded as skipped.
- Judges, a model or agent handed the output and a criterion, returning a score with evidence: tone, completeness, whether an answer addresses the question. A rubric is the agent scoring itself, 1 to 5 per criterion, with a bar of no criterion below 3 and an average of at least 4.0; a separate grader run is the form the agent can't influence.
Two facts to hold on to before the first run. One failed checklist item fails the verdict as surely as a failed Jetty check, there is no partial credit, and what differs between types is how far you can trust a pass. And a failed evaluation is not a failed run: the run completes and keeps its outputs while the verdict says the work fell short, and a run fails only when the job could not be carried out at all. Once a runbook's agent checks are settled, set strict_evaluation: true in the frontmatter so a skipped check counts as failed and an agent can't pass by leaving out the check it would fail.
See the evaluations reference for an overview: the two patterns, how the report comes together, the verdict, strict evaluation, and a failed run set against a failed evaluation. Code Checks covers agent checks and Jetty checks, writing a check, the code and secrets a check can use, and what it records. The Checklists page covers writing one and how each item reaches the verdict. Finally, Judges and Rubrics covers LLM judges, agent judges and rubric scoring. Defining Agent Checklists and Building AI Evaluations are the guides for writing them.
Read the result, then make incremental changes
After a run finishes, you can review what happened. Every run keeps the exact runbook the agent read, a step-by-step log, the full agent transcript, and the validation report your checks produced. This report has details about which checks worked and how many fix-and-recheck rounds it took.
From here, the loop is the same one Jetty is built around: author, run, investigate, improve. Change one variable, a model, a prompt line, a check, and compare the new run against the last one. Improving Agent Runbooks covers this once a first workload is running reliably.
Frequently asked questions
What is Jetty used for? Jetty runs and evaluates AI workloads, jobs handed to a coding agent that need checking for quality and tracking over time, rather than one-off chat requests.
Do I need to write code to try Jetty? No. Through the web app, describing a task to Pelly in plain language is enough to get a runbook. The terminal path is still a one-line prompt to your agent or a few shell commands, no application code required.
What's the difference between the web app path and the terminal path? The web app's Author Runbooks screen generates a runbook from a plain-language description through Pelly, Jetty's authoring agent, and is the fastest way to try something interactively. The terminal path brings Jetty to the coding agent you already use, either by letting the agent install itself from jetty.io/agent-instructions.md or by installing the plugin or MCP server, with a shell client for scripting a workload into a pipeline, a schedule, or other tooling you already run.
What's the difference between code checks, checklists, and judges? Code checks are deterministic pass or fail commands, run by the agent inside its fix-and-recheck loop or by Jetty after the agent finishes, where the agent can neither skip nor misreport them. Checklists are observable conditions the agent confirms about its own work. Judges are model-based scoring for qualities that are hard to express in code. Most real runbooks use a mix of all three, and no type outranks another: any failed check fails the run's verdict, while the run itself completes and keeps its outputs.
How much does it cost to start? The Scoop plan is free, no credit card required. Your first 12 runs through Author Runbooks are on us. See full pricing.
Where do I go after my first run? Read the validation report, not just the pass or fail result, then change one thing and compare the next run against it. Improving Agent Runbooks and Creating a Benchmark cover that loop once a first workload is past its first run.