Two for One: Privileged Bilateral Learning for Monocular Retinal Disease Classification
Lisa Y.W. Tang · SMASH 2026 spotlightRead the paper ↗
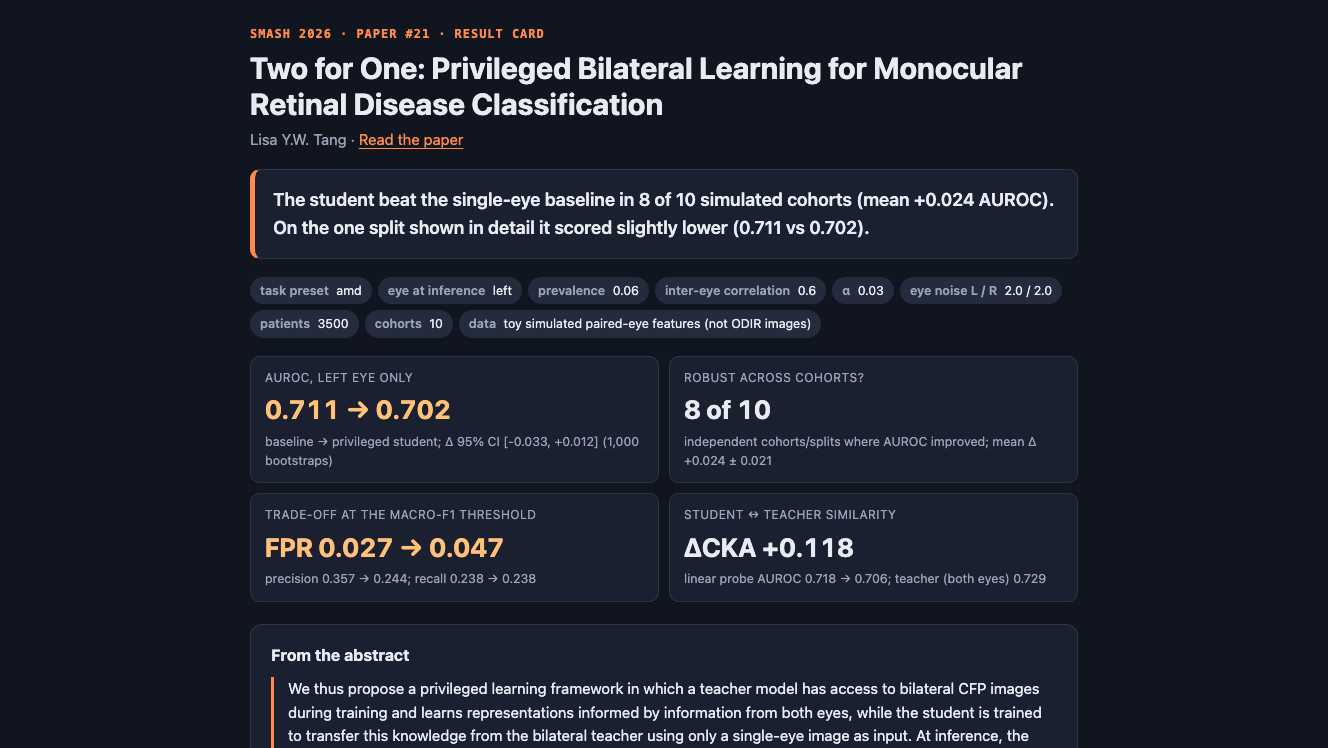
From the abstractWe thus propose a privileged learning framework in which a teacher model has access to bilateral CFP images during training and learns representations informed by information from both eyes, while the student is trained to transfer this knowledge from the bilateral teacher using only a single-eye image as input. At inference, the student operates exclusively on this single-eye input and does not require the contralateral image.
Example runs
Default inputs
The student beat the single-eye baseline in 8 of 10 simulated cohorts (mean +0.024 AUROC). On the one split shown in detail it scored slightly lower (0.711 vs 0.702). Simulated eye features replace fundus photographs. A small MLP replaces RETFound-Green.
Inputs
Acceptance checklist
15/15 checks passed.- Set up the sandbox and parameters
- Extract the tested code
- Run the experiment
- Write the narrative
- Render the result card and summary
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
- Result card, numbers, narrative and summary were written
- Experiment numbers are valid JSON and the experiment stayed within its time budget
- The narrative is complete and within the length limits
- Every try-next suggestion uses only this runbook's parameters
- Every number in the headline appears in the run's results
- The card embeds its figures, shows the headline, and contains no NaN
Runbook
| version | 1.0.0 |
| evaluation | programmatic |
| evals_version | 2 |
| agent | claude-code |
| model | anthropic/claude-haiku-5.5 |
| model_provider | openrouter |
| snapshot | python312-uv |
| primary_outputs | result_card.html |
Two Eyes to Train, One to Deploy: A Toy Privileged-Distillation Lab (SMASH 2026 · Paper #21)
Objective
This runbook is an interactive companion to the SMASH 2026 paper "Two for One: Privileged Bilateral Learning for Monocular Retinal Disease Classification" (Lisa Y.W. Tang). Read the paper: https://drive.google.com/file/d/1RKzJvGv1_Avf2kqHYQFnlwnWD78wedUW/
The paper's idea: fundus photographs of both eyes are often available when a model is developed, but at deployment only one eye may be imaged. A teacher sees both eyes (features of each eye from a shared backbone, mean-pooled into a bilateral representation Z_T, then a linear classifier). A student with exactly the baseline's architecture sees one eye and is trained jointly with a feature-distillation loss that pulls its representation Z_S toward Z_T. At inference the student needs only one eye. On ODIR-5K with RETFound-Green, AUROC rose for both diseases and both eyes, most for the left eye (AMD 0.931 → 0.966, DR 0.789 → 0.836), with a task-dependent precision/false-positive trade-off.
Real ODIR images and a ViT are far beyond a 90-second CPU budget, so this runbook is an honest toy: simulated paired left/right eye feature vectors with a shared latent disease signal and per-eye noise, and small numpy MLPs trained with the paper's exact loss and evaluation protocol. The participant controls how correlated the eyes are, how noisy each eye is, the distillation weight α, disease prevalence and which eye is used at inference. The run answers the question the paper raises but cannot vary: when does the privileged eye actually help? It also repeats the experiment over independent cohorts, because the paper reports a single split. Output: a shareable result card.
Target wall-clock: under 4 minutes. The experiment itself takes about 10 seconds.
The method as in the paper, and what the toy changes
- Loss (paper Eq. 1):
L = BCE(ŷ_teacher, y) + BCE(ŷ_student, y) + α · (1/B) Σ_i ‖Z_S^i − Z_T^i‖², teacher and student trained jointly; the teacher is optimised by its classification loss only (Z_T is the distillation target). Baseline: same monocular architecture, BCE only. Z = the layer before the linear classifier. - Patient-level split: 20% test, then 80/20 train/validation (paper §2.2). Early stopping keeps the checkpoint with the lowest validation loss. Threshold t* = argmax over t ∈ [0.01, 0.99] of macro-F1 on validation, applied to test.
- Metrics: AUROC, AUPRC, balanced accuracy, precision, recall, FPR; 95% CIs from 1,000 bootstrap resamples of the
test set. Linear CKA on validation features (
ΔCKA = CKA(Z_S, Z_T) − CKA(Z_baseline, Z_T)); linear probing of the frozen backbones with a fresh logistic-regression head. - Toy substitutions: inputs are simulated 128-d eye feature vectors, not fundus images; the backbone is a
one-hidden-layer numpy MLP (32-d Z instead of 384-d) instead of RETFound-Green. Teacher and student start from
identical weights, standing in for the shared pretrained backbone. The patient-level label is a threshold on a
latent severity; each eye shows
√ρ·severity + √(1−ρ)·eye-specific part, plus nuisance shared by both eyes and eye-specific noise. α acts on this toy's feature scale, so its numeric value is not comparable to the paper's.
Paper headline numbers (quote exactly; ODIR-5K, single held-out test split)
- AMD AUROC: left 0.931 (0.846–0.984) → 0.966 (0.936–0.987); right 0.801 → 0.810.
- DR AUROC: left 0.789 (0.734–0.843) → 0.836 (0.799–0.872); right 0.825 → 0.837.
- Balanced accuracy, left eye: AMD 0.834 → 0.879; DR 0.576 → 0.749.
- Trade-offs, left eye: AMD FPR 0.011 → 0.027, precision 0.760 → 0.595, recall 0.679 → 0.786; DR FPR 0.766 → 0.089, precision 0.078 → 0.760, recall 0.917 → 0.587.
- CKA (DR): student–teacher similarity +0.015 vs baseline; AMD inconclusive. Linear probing: AMD 0.815 vs 0.836 (+2.0 points), DR +2.9 points.
REQUIRED OUTPUT FILES (MANDATORY)
All in {{results_dir}}:
| File | Description |
|---|---|
result_card.html | Primary output. Self-contained, shareable one-page result card |
results.json | All computed numbers (written by experiment.py) |
card_data.json | Numbers/figures for the card (written by experiment.py) |
narrative.json | Your interpretation of this run (Step 4) |
fig_*.png | Figures (written by experiment.py) |
summary.md | 5–10 line plain-text summary |
validation_report.json | Evals v2 report: steps, code checks, checklist (see Write Validation Report) |
Parameters
| Parameter | Template Variable | Default | Description |
|---|---|---|---|
| Task preset | {{task}} | amd | amd (rare: 6% prevalence) or dr (common: 30%); sets prevalence when Prevalence is 0 |
| Eye at inference | {{eye}} | left | Which single eye the baseline and student see: left or right |
| Prevalence | {{prevalence}} | 0 | Patient-level disease prevalence; 0 = task preset |
| Inter-eye correlation | {{inter_eye_corr}} | 0.6 | How similar the disease signal is in the two eyes (0 = independent, 0.99 = identical) |
| Distillation weight α | {{alpha}} | 0.03 | Weight of the feature-distillation term; 0 = no distillation |
| Left-eye noise | {{noise_left}} | 2.0 | Eye-specific image noise in the left eye (0.2–4) |
| Right-eye noise | {{noise_right}} | 2.0 | Eye-specific image noise in the right eye (0.2–4); make them differ to mimic an asymmetric camera or eye |
| Patients | {{n_patients}} | 3500 | Simulated patients (ODIR-5K: 3,500) |
| Cohorts | {{n_seeds}} | 10 | Independent simulated cohorts and splits (the paper used one split) |
| Seed | {{seed}} | 0 | Seed of the cohort shown in detail on the card |
Dependencies
numpy, scipy, scikit-learn, matplotlib (preinstalled in python312-uv). No downloads, no torch.
Step 1: Set up
mkdir -p {{results_dir}} /app/work && cd /app/work
python -c "import numpy, scipy, sklearn, matplotlib" 2>/dev/null || uv pip install --system -q numpy scipy scikit-learn matplotlib
Write /app/work/params.json (numbers as JSON numbers; if a value still looks like an unsubstituted {{…}}
placeholder, use the default from the table):
{"task": "{{task}}", "eye": "{{eye}}", "prevalence": {{prevalence}}, "inter_eye_corr": {{inter_eye_corr}},
 "alpha": {{alpha}}, "noise_left": {{noise_left}}, "noise_right": {{noise_right}}, "n_patients": {{n_patients}},
 "n_seeds": {{n_seeds}}, "seed": {{seed}}, "runbook_url": ""}
Validate before running: task ∈ {amd, dr}, eye ∈ {left, right}. Clamp prevalence to 0 or [0.02, 0.5],
inter_eye_corr to [0, 0.99], alpha to [0, 1], noise_left and noise_right to [0.2, 4], n_patients to
[1000, 10000], n_seeds to [3, 20]. Record every correction as a caveat.
Step 2: Get the code (extract it, don't retype it)
The tested implementation of the method is embedded in the Appendix at the end of this runbook. Do not rewrite, "improve", or re-derive it. Always run the command below first, exactly as written. It copies the files out of this runbook's text (which the sandbox exposes to running processes) in about a second, and it is far faster and more reliable than retyping several hundred lines. Do not skip it on the assumption that it won't work: run it and read its output:
cd /app/work && cat > extract.py <<'PYEOF'
"""Extract the runbook's embedded files without retyping them.

The runbook text reaches the agent as one command-line argument, so it is readable from /proc.
Every embedded file sits under a heading "### `/app/work/<name>`" followed by one fenced block.
Exits non-zero if any requested file can't be found, so the caller falls back to writing it by hand.

usage: python3 extract.py <name> [<name> ...]   (writes /app/work/<name>)
"""
import ast, glob, re, sys
from pathlib import Path

want = sys.argv[1:]
cands = []
for p in glob.glob("/proc/[0-9]*/cmdline"):
    try:
        s = Path(p).read_bytes().decode("utf-8", "ignore")
    except OSError:
        continue
    if all(f"### `/app/work/{w}`" in s for w in want):
        cands.append(s)
if not cands:
    sys.exit("runbook text not found in /proc; write the files by hand")
# The agent's own argv holds the raw text; wrapper shells hold a shell-quoted copy, so prefer the shortest
# and undo shell single-quote escaping as a fallback.
best = min(cands, key=len).replace("'\"'\"'", "'")
ok = True
for w in want:
    m = re.search(r"### `/app/work/" + re.escape(w) + r"`\s*\n+```[a-z]*\n(.*?)\n```\n", best, re.S)
    if not m or len(m.group(1)) < 50:
        print(f"MISSING {w}"); ok = False; continue
    code = m.group(1) + "\n"
    if w.endswith(".py"):
        try:
            ast.parse(code)
        except SyntaxError as e:
            print(f"MISSING {w} (extracted text does not parse: {e})"); ok = False; continue
    Path("/app/work", w).write_text(code)
    print(f"extracted {w}: {code.count(chr(10))} lines")
sys.exit(0 if ok else 1)
PYEOF
python3 extract.py experiment.py render_card.py validate.py
If it exits non-zero or prints MISSING, write each missing file from the Appendix exactly as given, one
heredoc per file (quoted delimiter, e.g. cat > experiment.py <<'PYEOF'). If a later step fails, fix only
environment problems (missing package, network retry), never the methodology.
Step 3: Run the experiment
cd /app/work && export OMP_NUM_THREADS=4 OPENBLAS_NUM_THREADS=4 MKL_NUM_THREADS=4 SMASH_CPUS=4 && timeout 300 python experiment.py params.json {{results_dir}}Expected: 5–40 s depending on patients and cohorts. Ends with a done: line.
The sandbox has 4 CPUs even though nproc may report more; the exports keep numpy/BLAS and process pools from oversubscribing them.
Step 4: Interpret: write narrative.json
Read {{results_dir}}/results.json and card_data.json, and look at every fig_*.png. Then write
{{results_dir}}/narrative.json with keys headline, idea (exactly 3), findings (2–4), try_next (2–3),
caveats (2–4):
- headline (≤ 30 words): the most robust finding of this run with 1–2 numbers from
results.json. Prefer the multi-cohort result (seeds.mean_d_auroc,seeds.n_positiveofseeds.n) over the single split, and say so when the detailed split disagrees with the average (that is the paper's single-split limitation made visible). - idea: plain language: a model trained with both eyes can teach a one-eye model; the student copies the teacher's internal representation, not just its answers; at deployment only one image is needed.
- findings: (1) AUROC baseline → student on the detailed split with the bootstrap CI of the difference
(
ci_d_auroc), next to the paper's numbers, and the teacher's own two-eye AUROC (teacher_auroc) as the ceiling; (2) the cohort spread (seeds); (3) the sweep (sweep): at which inter-eye correlation the privileged eye helps most, and why (if the eyes are nearly identical, the second eye adds little; if they are unrelated, the student cannot predict it); (4) the threshold trade-off (d_fpr,d_precision, andseeds.d_fpr/seeds.d_precision): the paper saw FPR rise for AMD but fall sharply for DR; here the sign varies between splits, because it depends on the validation-chosen threshold more than on the representation. Mention ΔCKA and the linear probe briefly. - try_next: 2–3 contrasting runs with exact values, using only the keys
task, eye, prevalence, inter_eye_corr, alpha, noise_left, noise_right, n_patients, n_seeds, seed. Good contrasts:inter_eye_corr0.95 (eyes nearly identical);noise_left3.0 withnoise_right1.0 (a noisy deployment eye with a clean privileged eye);n_patients10000 (does the benefit shrink with more data?);taskdr. - caveats: toy simulation, not ODIR images or RETFound-Green (magnitudes are not comparable to the paper); the student's gain depends on the simulated eye correlation and noise; one split can mislead (show the cohort spread); α is on this toy's feature scale.
Step 5: Render the card and summary
cd /app/work && python render_card.py {{results_dir}}/card_data.json {{results_dir}}/narrative.json {{results_dir}}/result_card.htmlWrite {{results_dir}}/summary.md (5–10 lines: settings, AUROC baseline → student with CI, cohort mean and count,
best inter-eye correlation in the sweep, FPR/precision change, headline).
Writing style for narrative.json
These rules apply to every field and override any longer limits stated earlier in this runbook. Let the paper and the numbers speak; the card is not the place for commentary.
- Length:
headlineone sentence;idea1–3 bullets of at most 30 words;findings1–2 paragraphs of at most 60 words each;caveats1–2 bullets of at most 20 words. Cut anything the tiles, figures or tables already show. - Plain statements of what was measured. Write "Sensitivity gap −0.284 [−0.354, −0.218]; the paper reports +0.088", not an interpretation of what it means for the field.
- Avoid: em-dash asides; "not X, but Y" framings; colon-then-reveal sentences; rhetorical questions; words such as crucially, notably, strikingly, remarkably, collapses, illustrating, underscores, highlights, delve, powerful, key insight, worth noting; exclamation marks; restating the method before the result.
- Use the paper's own terms for its concepts. Quote the paper's numbers exactly.
Code Checks
Jetty runs these checks itself in the sandbox after the agent finishes, so they cannot be skipped or
misreported. validate.py (see Write Validation Report) runs the same checks first so you can fix problems before you stop.
outputs-exist — Result card, numbers, narrative and summary were written
cd {{results_dir}} && for f in result_card.html results.json card_data.json narrative.json summary.md; do test -s "$f" || { echo "missing or empty: $f"; exit 1; }; done; echo "all 5 outputs present"results-valid — Experiment numbers are valid JSON and the experiment stayed within its time budget
python3 - "{{results_dir}}" 300 <<'PY'
import json, sys
from pathlib import Path
R, budget = Path(sys.argv[1]), float(sys.argv[2])
res = json.loads((R / "results.json").read_text())
json.loads((R / "card_data.json").read_text())
rt = float(res.get("runtime_sec", 0))
if rt > budget:
    sys.exit(f"experiment took {rt}s, budget {budget}s")
print(f"results.json and card_data.json parse; experiment {rt}s within {budget:.0f}s")
PY
narrative-complete — The narrative is complete and within the length limits
python3 - "{{results_dir}}" <<'PY'
import json, sys
from pathlib import Path
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
problems = []
if not str(n.get("headline", "")).strip(): problems.append("no headline")
if len(str(n.get("headline", "")).split()) > 45: problems.append("headline over 45 words")
if not 1 <= len(n.get("idea", [])) <= 3: problems.append(f"idea has {len(n.get('idea', []))} bullets, need 1-3")
if not 1 <= len(n.get("findings", [])) <= 2: problems.append(f"{len(n.get('findings', []))} findings, need 1-2")
if any(len(f.split()) > 70 for f in n.get("findings", [])): problems.append("a findings paragraph is over 60 words")
if not 2 <= len(n.get("try_next", [])) <= 3: problems.append(f"{len(n.get('try_next', []))} try_next, need 2-3")
if not 1 <= len(n.get("caveats", [])) <= 2: problems.append(f"{len(n.get('caveats', []))} caveats, need 1-2")
if problems: sys.exit("; ".join(problems))
print("headline, %d idea bullets, %d findings, %d try_next, %d caveats" % (len(n["idea"]), len(n["findings"]), len(n["try_next"]), len(n["caveats"])))
PY
try-next-valid — Every try-next suggestion uses only this runbook's parameters
python3 - "{{results_dir}}" "task,eye,prevalence,inter_eye_corr,alpha,noise_left,noise_right,n_patients,n_seeds,seed" <<'PY'
import json, sys
from pathlib import Path
allowed = set(sys.argv[2].split(","))
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
bad = sorted({k for t in n.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
empty = [t.get("label", "?") for t in n.get("try_next", []) if not t.get("params")]
if bad or empty: sys.exit(f"unknown parameters: {bad}; suggestions without params: {empty}")
print("all try_next parameters are declared runbook parameters")
PY
headline-grounded — Every number in the headline appears in the run's results
python3 - "{{results_dir}}" <<'PY'
import json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
blob = (R / "results.json").read_text() + (R / "card_data.json").read_text()
vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
head = json.loads((R / "narrative.json").read_text())["headline"]
nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", head)
missing = []
for n in nums:
    s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
    tol = 0.5 * 10 ** (-dec) + 1e-9
    if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
        missing.append(n)
if missing: sys.exit(f"headline numbers not found in results: {missing}")
print(f"{len(nums)} headline number(s) all grounded in results")
PY
card-integrity — The card embeds its figures, shows the headline, and contains no NaN
python3 - "{{results_dir}}" <<'PY'
import html, json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
card = (R / "result_card.html").read_text()
text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
head = json.loads((R / "narrative.json").read_text())["headline"]
problems = []
if card.count("data:image/png;base64") < 1: problems.append("no embedded figures")
if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): problems.append("NaN/Infinity in card text")
if len(card) > 5_000_000: problems.append(f"card is {len(card) // 1024} KB")
plain = html.unescape(re.sub(r"<[^>]+>", "", text))
if re.sub(r"[*`]", "", head)[:40] not in plain: problems.append("headline not on card")
if problems: sys.exit("; ".join(problems))
print(f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures, headline present")
PY
Checklist
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
Write Validation Report
Judge the four Checklist items honestly against your outputs and write them to /app/work/checklist.json as a
list, using the checklist ids Jetty gives you (one entry per item):
[{"id": "<checklist id>", "status": "pass", "message": "one line on why"}]Then write the report and self-check in one command:
cd /app/work && python3 validate.py {{results_dir}} task,eye,prevalence,inter_eye_corr,alpha,noise_left,noise_right,n_patients,n_seeds,seed 300 checklist.jsonvalidate.py writes {{results_dir}}/validation_report.json in the v2 shape Jetty reads (version: 2, one
step entry per runbook step, one code_check entry per check above, one checklist entry per item). Jetty
replaces the code_check entries with its own independent run of the same checks. Do not write the report by hand.
Iteration (up to 2 rounds)
If validate.py prints any FAIL, fix the named problem (usually a headline number that does not match
results.json, or an unknown try_next key), re-render the card (Step 5) and rerun the command above. Never
rerun the experiment just to change the narrative.
Appendix: code
These files are extracted verbatim in Step 2.
/app/work/experiment.py
"""Two for One: privileged bilateral learning, toy re-enactment — SMASH 2026 paper #21 (Lisa Y.W. Tang).

A teacher sees both eyes (features of each eye from a shared backbone, mean-pooled, linear head); a student sees
one eye and is trained jointly with the paper's loss  L = BCE(teacher) + BCE(student) + alpha * mean_i ||Z_S - Z_T||^2.
Baseline: the same monocular architecture trained with BCE only. Everything is a small numpy MLP on simulated
paired eye feature vectors (a toy stand-in for RETFound-Green features of ODIR-5K fundus photographs).
Patient-level split (20% test; 80/20 train/val), early stopping on validation loss, macro-F1 threshold chosen on
validation, 1,000-resample bootstrap CIs, linear CKA, linear probing. Extension: when does the privileged eye help?

usage: python experiment.py params.json outdir
"""
import json, sys, time
from pathlib import Path

import numpy as np
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt
from scipy.stats import norm
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import roc_auc_score, average_precision_score

T0 = time.time()
P = json.loads(Path(sys.argv[1]).read_text())
OUT = Path(sys.argv[2]); OUT.mkdir(parents=True, exist_ok=True)
TASK = P["task"]; EYE = P["eye"]
PREV = float(P["prevalence"]) if float(P["prevalence"]) > 0 else {"amd": 0.06, "dr": 0.30}.get(TASK, 0.1); RHO = float(P["inter_eye_corr"]); ALPHA = float(P["alpha"])
NOISE_L, NOISE_R = float(P["noise_left"]), float(P["noise_right"])
N_PAT = int(P["n_patients"]); N_SEEDS = int(P["n_seeds"]); SEED = int(P["seed"])
D, H, K_SIG, M_NUIS = 128, 32, 3, 12    # feature dim, hidden width (the paper's Z is 384-d), signal dims, nuisance dims
N_BOOT = 1000
AMP = float(P.get("signal", 1.5))     # disease-signal amplitude in the eye features
INK, ACC, BLUE, MUTED, GOOD = "#1f2a44", "#d9480f", "#1971c2", "#868e96", "#2b8a3e"


def log(m):
    print(f"[{time.time() - T0:6.1f}s] {m}", flush=True)


# ------------------------------------------------------------------ toy bilateral world
def make_world(seed, n=N_PAT, rho=RHO, prev=PREV, nl=NOISE_L, nr=NOISE_R):
    """Patient disease severity s ~ N(0,1); label y = 1[s > threshold] (patient-level, prevalence `prev`).
    Each eye shows its own copy l_e = sqrt(rho) s + sqrt(1-rho) e_e (rho = inter-eye correlation of the disease
    signal). Eye features = nonlinear signal in a few directions + patient-level nuisance shared by both eyes
    (camera, pigmentation) + eye-specific noise of scale noise_left / noise_right."""
    r = np.random.default_rng(seed)
    Q, _ = np.linalg.qr(np.random.default_rng(777).standard_normal((D, D)))   # fixed geometry across seeds
    U, Vn = Q[:, :K_SIG], Q[:, K_SIG:K_SIG + M_NUIS]
    s = r.standard_normal(n)
    y = (s > norm.ppf(1 - prev)).astype(float)
    nuis = r.standard_normal((n, M_NUIS)) * 1.5
    def eye(noise):
        l = np.sqrt(rho) * s + np.sqrt(1 - rho) * r.standard_normal(n)
        sig = np.c_[l, np.maximum(l - 1.0, 0) * 1.5, np.tanh(2 * (l - 1.2))]
        return AMP * sig @ U.T + nuis @ Vn.T + noise * r.standard_normal((n, D))
    return eye(nl), eye(nr), y


def splits(n, seed):
    """Patient-level: 20% test (the paper's 6-fold outer split), then 80/20 train/validation of the rest."""
    idx = np.random.default_rng(seed + 1).permutation(n)
    te = idx[: n // 5]; rest = idx[n // 5:]
    va = rest[: len(rest) // 5]; tr = rest[len(rest) // 5:]
    return tr, va, te


# ------------------------------------------------------------------ numpy MLP (backbone -> Z -> linear head)
def init(rng, d_in):
    return {"W1": rng.standard_normal((d_in, H)) * np.sqrt(2 / d_in), "b1": np.zeros(H),
            "w2": rng.standard_normal(H) * 0.05, "b2": np.zeros(1)}


def feats(p, X):
    a = X @ p["W1"] + p["b1"]
    return np.maximum(a, 0), a


def sigm(u):
    return 1 / (1 + np.exp(-np.clip(u, -30, 30)))


def bce(y, q):
    q = np.clip(q, 1e-7, 1 - 1e-7)
    return float(-np.mean(y * np.log(q) + (1 - y) * np.log(1 - q)))


class Adam:
    def __init__(self, params, lr=3e-3, wd=1e-4):
        self.lr, self.wd, self.t = lr, wd, 0
        self.m = {k: {n: np.zeros_like(v) for n, v in p.items()} for k, p in params.items()}
        self.v = {k: {n: np.zeros_like(v) for n, v in p.items()} for k, p in params.items()}

    def step(self, params, grads):
        self.t += 1
        for k in grads:
            for n, g in grads[k].items():
                g = g + self.wd * params[k][n] if n.startswith("W") else g
                self.m[k][n] = 0.9 * self.m[k][n] + 0.1 * g
                self.v[k][n] = 0.999 * self.v[k][n] + 0.001 * g * g
                mh = self.m[k][n] / (1 - 0.9 ** self.t); vh = self.v[k][n] / (1 - 0.999 ** self.t)
                params[k][n] -= self.lr * mh / (np.sqrt(vh) + 1e-8)


def back_head(p, Z, A, X, dlogit, dZ_extra=None):
    """Gradients of a backbone+head given dL/dlogit (n,) and an optional extra dL/dZ."""
    g = {"w2": Z.T @ dlogit, "b2": np.array([dlogit.sum()])}
    dZ = np.outer(dlogit, p["w2"])
    if dZ_extra is not None:
        dZ = dZ + dZ_extra
    dA = dZ * (A > 0)
    g["W1"] = X.T @ dA; g["b1"] = dA.sum(0)
    return g


def train(Xs_tr, Xl_tr, Xr_tr, y_tr, Xs_va, Xl_va, Xr_va, y_va, mode, alpha, seed, epochs=300, patience=30):
    """mode 'baseline': monocular BCE. mode 'privileged': teacher (both eyes, mean-pooled Z) and student (one eye)
    trained jointly on BCE_T + BCE_S + alpha * mean ||Z_S - Z_T||^2. As in the paper, the teacher is optimised by its
    classification loss only (Z_T is a fixed target inside the distillation term).
    Early stopping on the validation loss of the deployed (monocular) model; best checkpoint kept."""
    rng = np.random.default_rng(seed)
    params = {"S": init(rng, D)}
    if mode == "privileged":   # teacher and student start from the same weights, standing in for a shared pretrained backbone
        params["T"] = {k: v.copy() for k, v in params["S"].items()}
    opt = Adam(params)
    n = len(y_tr); best, best_p, bad = np.inf, None, 0
    for ep in range(epochs):
        ZS, AS = feats(params["S"], Xs_tr); qS = sigm(ZS @ params["S"]["w2"] + params["S"]["b2"])
        grads = {}
        if mode == "privileged":
            ZL, AL = feats(params["T"], Xl_tr); ZR, AR = feats(params["T"], Xr_tr)
            ZT = (ZL + ZR) / 2; qT = sigm(ZT @ params["T"]["w2"] + params["T"]["b2"])
            diff = ZS - ZT                                           # (n, H)
            dZS = 2 * alpha * diff / n                               # d/dZ_S of alpha * mean_i ||Z_S - Z_T||^2
            grads["S"] = back_head(params["S"], ZS, AS, Xs_tr, (qS - y_tr) / n, dZS)
            dlT = (qT - y_tr) / n
            dZT = np.outer(dlT, params["T"]["w2"])                   # teacher: classification loss only (paper §2.1);
                                                                     # the distillation term moves the student only
            gT = {"w2": ZT.T @ dlT, "b2": np.array([dlT.sum()])}
            dAL = (dZT / 2) * (AL > 0); dAR = (dZT / 2) * (AR > 0)
            gT["W1"] = Xl_tr.T @ dAL + Xr_tr.T @ dAR; gT["b1"] = dAL.sum(0) + dAR.sum(0)
            grads["T"] = gT
        else:
            grads["S"] = back_head(params["S"], ZS, AS, Xs_tr, (qS - y_tr) / n)
        opt.step(params, grads)
        Zv, _ = feats(params["S"], Xs_va)
        vl = bce(y_va, sigm(Zv @ params["S"]["w2"] + params["S"]["b2"]))
        if vl < best - 1e-5:
            best, bad = vl, 0
            best_p = {k: {m: v.copy() for m, v in p.items()} for k, p in params.items()}
        else:
            bad += 1
            if bad >= patience:
                break
    return best_p, ep + 1


def predict(p, X):
    Z, _ = feats(p, X)
    return sigm(Z @ p["w2"] + p["b2"]), Z


def linear_cka(A, B):
    """Linear CKA (paper App. A.2): HSIC with linear kernels on column-centred features."""
    A = A - A.mean(0); B = B - B.mean(0)
    hsic = lambda X, Y: np.linalg.norm(X.T @ Y, "fro") ** 2
    den = np.sqrt(hsic(A, A) * hsic(B, B))
    return float(hsic(A, B) / den) if den > 0 else 0.0


def thr_macro_f1(y, q):
    """t* = argmax over t in [0.01, 0.99] of macro-F1 on validation (paper Eq. 10)."""
    best_t, best_f = 0.5, -1
    for t in np.arange(0.01, 0.995, 0.01):
        pr = q > t; f = 0
        for cls in (1, 0):
            tp = np.sum((pr == cls) & (y == cls)); fp = np.sum((pr == cls) & (y != cls)); fn = np.sum((pr != cls) & (y == cls))
            f += 2 * tp / max(2 * tp + fp + fn, 1)
        if f / 2 > best_f:
            best_f, best_t = f / 2, float(t)
    return best_t


def metrics(y, q, t):
    pr = q > t
    tp = np.sum(pr & (y == 1)); fp = np.sum(pr & (y == 0)); tn = np.sum(~pr & (y == 0)); fn = np.sum(~pr & (y == 1))
    rec = tp / max(tp + fn, 1); spec = tn / max(tn + fp, 1)
    return {"auroc": float(roc_auc_score(y, q)), "auprc": float(average_precision_score(y, q)),
            "bal_acc": float((rec + spec) / 2), "precision": float(tp / max(tp + fp, 1)), "recall": float(rec),
            "fpr": float(fp / max(fp + tn, 1)), "threshold": t}


def boot(y, qa, qb, ta, tb, rng):
    """1,000 bootstrap resamples of the test set: CIs for each model and for the paired difference."""
    keys = ["auroc", "bal_acc", "precision", "recall", "fpr", "auprc"]
    A = {k: [] for k in keys}; B = {k: [] for k in keys}; d_auc = []
    n = len(y)
    for _ in range(N_BOOT):
        i = rng.integers(0, n, n)
        if y[i].min() == y[i].max():
            continue
        ma, mb = metrics(y[i], qa[i], ta), metrics(y[i], qb[i], tb)
        for k in keys:
            A[k].append(ma[k]); B[k].append(mb[k])
        d_auc.append(mb["auroc"] - ma["auroc"])
    ci = lambda v: [float(np.percentile(v, 2.5)), float(np.percentile(v, 97.5))]
    return {k: ci(A[k]) for k in keys}, {k: ci(B[k]) for k in keys}, ci(d_auc), float(np.mean(np.array(d_auc) > 0))


def run_once(seed, rho=RHO, alpha=ALPHA, nl=NOISE_L, nr=NOISE_R, full=False):
    XL, XR, y = make_world(seed, rho=rho, nl=nl, nr=nr)
    tr, va, te = splits(len(y), seed)
    Xs = XL if EYE == "left" else XR
    pb, ep_b = train(Xs[tr], None, None, y[tr], Xs[va], None, None, y[va], "baseline", 0, seed)
    pb = pb["S"]
    pp, ep_p = train(Xs[tr], XL[tr], XR[tr], y[tr], Xs[va], XL[va], XR[va], y[va], "privileged", alpha, seed)
    qb_va, _ = predict(pb, Xs[va]); qs_va, _ = predict(pp["S"], Xs[va])
    qb, Zb = predict(pb, Xs[te]); qs, Zs = predict(pp["S"], Xs[te])
    tb, ts = thr_macro_f1(y[va], qb_va), thr_macro_f1(y[va], qs_va)
    out = {"baseline": metrics(y[te], qb, tb), "privileged": metrics(y[te], qs, ts), "epochs": [ep_b, ep_p]}
    if full:
        # teacher on the test set (needs both eyes: an upper reference, not deployable monocularly)
        ZLt, _ = feats(pp["T"], XL[te]); ZRt, _ = feats(pp["T"], XR[te]); ZT = (ZLt + ZRt) / 2
        out["teacher_auroc"] = float(roc_auc_score(y[te], sigm(ZT @ pp["T"]["w2"] + pp["T"]["b2"])))
        # Exp. 1: CKA on the validation set
        ZLv, _ = feats(pp["T"], XL[va]); ZRv, _ = feats(pp["T"], XR[va]); ZTv = (ZLv + ZRv) / 2
        _, Zbv = predict(pb, Xs[va]); _, Zsv = predict(pp["S"], Xs[va])
        out["cka_student_teacher"] = linear_cka(Zsv, ZTv); out["cka_baseline_teacher"] = linear_cka(Zbv, ZTv)
        # Exp. 2: linear probing on frozen backbones (fresh linear head trained on the training set)
        probe = {}
        for name, p in (("baseline", pb), ("privileged", pp["S"])):
            Ztr, _ = feats(p, Xs[tr]); Zte, _ = feats(p, Xs[te])
            lr = LogisticRegression(max_iter=200).fit(Ztr, y[tr])
            probe[name] = float(roc_auc_score(y[te], lr.predict_proba(Zte)[:, 1]))
        out["probe"] = probe
        out["boot"] = boot(y[te], qb, qs, tb, ts, np.random.default_rng(seed + 99))
        out["n_test"] = int(len(te)); out["n_test_pos"] = int(y[te].sum())
        out["roc"] = {k: roc_points(y[te], q) for k, q in (("baseline", qb), ("privileged", qs))}
    return out


def roc_points(y, q):
    o = np.argsort(-q); ys = y[o]
    tpr = np.r_[0, np.cumsum(ys) / ys.sum()]; fpr = np.r_[0, np.cumsum(1 - ys) / (1 - ys).sum()]
    k = np.linspace(0, len(tpr) - 1, 200).astype(int)
    return {"fpr": fpr[k].tolist(), "tpr": tpr[k].tolist()}


def main():
    main_run = run_once(SEED, full=True)
    b, s = main_run["baseline"], main_run["privileged"]
    log(f"seed {SEED}: AUROC baseline {b['auroc']:.3f} -> privileged {s['auroc']:.3f} (teacher, both eyes, "
        f"{main_run['teacher_auroc']:.3f}); epochs {main_run['epochs']}")
    seeds = [run_once(SEED + 1000 * (i + 1)) for i in range(N_SEEDS - 1)]
    allr = [main_run] + seeds
    d = np.array([r["privileged"]["auroc"] - r["baseline"]["auroc"] for r in allr])
    log(f"{N_SEEDS} independent cohorts/splits: dAUROC mean {d.mean():+.3f}, positive in {np.sum(d > 0)}/{N_SEEDS}")
    # extension: when does the privileged eye help? sweep inter-eye correlation x alpha (2 cohorts per cell)
    rhos = [0.2, 0.4, 0.6, 0.8, 0.95]; alphas = [0.0, 0.003, 0.01, 0.03, 0.1, 0.3]
    grid = np.zeros((len(rhos), len(alphas)))
    for i, rh in enumerate(rhos):
        for j, al in enumerate(alphas):
            vals = []
            for k in range(2):
                r = run_once(SEED + 50_000 + 17 * k, rho=rh, alpha=al)
                vals.append(r["privileged"]["auroc"] - r["baseline"]["auroc"])
            grid[i, j] = np.mean(vals)
    log("sweep inter-eye correlation x alpha done")
    res = {"params": P, "task": TASK, "eye": EYE, "main": {k: v for k, v in main_run.items() if k != "roc"},
           "baseline": b, "privileged": s, "d_auroc": s["auroc"] - b["auroc"],
           "d_bal_acc": s["bal_acc"] - b["bal_acc"], "d_precision": s["precision"] - b["precision"],
           "d_recall": s["recall"] - b["recall"], "d_fpr": s["fpr"] - b["fpr"],
           "teacher_auroc": main_run["teacher_auroc"], "cka_student_teacher": main_run["cka_student_teacher"],
           "cka_baseline_teacher": main_run["cka_baseline_teacher"],
           "d_cka": main_run["cka_student_teacher"] - main_run["cka_baseline_teacher"],
           "probe": main_run["probe"], "d_probe": main_run["probe"]["privileged"] - main_run["probe"]["baseline"],
           "ci_baseline": main_run["boot"][0], "ci_privileged": main_run["boot"][1], "ci_d_auroc": main_run["boot"][2],
           "boot_share_d_auroc_positive": main_run["boot"][3],
           "seeds": {"d_auroc": d.tolist(), "mean_d_auroc": float(d.mean()), "sd_d_auroc": float(d.std()),
                     "n_positive": int(np.sum(d > 0)), "n": N_SEEDS,
                     "d_fpr": [r["privileged"]["fpr"] - r["baseline"]["fpr"] for r in allr],
                     "d_precision": [r["privileged"]["precision"] - r["baseline"]["precision"] for r in allr],
                     "thresholds": [[r["baseline"]["threshold"], r["privileged"]["threshold"]] for r in allr]},
           "sweep": {"rho": rhos, "alpha": alphas, "d_auroc": grid.tolist()},
           "n_test": main_run["n_test"], "n_test_pos": main_run["n_test_pos"]}
    figures(res, main_run["roc"])
    card(res)
    res["runtime_sec"] = round(time.time() - T0, 1)
    (OUT / "results.json").write_text(json.dumps(res, indent=2))
    log(f"done: {EYE} eye AUROC {b['auroc']:.3f} -> {s['auroc']:.3f} (CI of diff {res['ci_d_auroc'][0]:+.3f}..{res['ci_d_auroc'][1]:+.3f}); "
        f"FPR {b['fpr']:.3f} -> {s['fpr']:.3f}; precision {b['precision']:.3f} -> {s['precision']:.3f}; dCKA {res['d_cka']:+.3f}")


def figures(res, roc):
    plt.rcParams.update({"font.size": 9.5, "axes.spines.top": False, "axes.spines.right": False})
    b, s = res["baseline"], res["privileged"]
    # Fig 1: ROC + operating points
    fig, axs = plt.subplots(1, 2, figsize=(6.4, 3.0), gridspec_kw={"width_ratios": [1, 1.15]})
    ax = axs[0]
    ax.plot(roc["baseline"]["fpr"], roc["baseline"]["tpr"], color=MUTED, lw=2, label=f"baseline {b['auroc']:.3f}")
    ax.plot(roc["privileged"]["fpr"], roc["privileged"]["tpr"], color=ACC, lw=2, label=f"privileged {s['auroc']:.3f}")
    ax.plot(b["fpr"], b["recall"], "o", color=MUTED, ms=7, mec=INK); ax.plot(s["fpr"], s["recall"], "o", color=ACC, ms=7, mec=INK)
    ax.plot([0, 1], [0, 1], ls=":", color=MUTED, lw=1)
    ax.set_xlabel("false-positive rate"); ax.set_ylabel("recall (sensitivity)"); ax.legend(frameon=False, fontsize=7.5, loc="lower right")
    ax.set_title(f"{res['eye']} eye, AUROC (dots: macro-F1 threshold)", fontsize=8.5, loc="left")
    ax = axs[1]
    keys = [("auroc", "AUROC"), ("bal_acc", "Bal. acc."), ("precision", "Precision"), ("recall", "Recall"), ("fpr", "FPR")]
    xs = np.arange(len(keys))
    cb, cs = res["ci_baseline"], res["ci_privileged"]
    for off, m, ci, col, lab in [(-0.18, b, cb, MUTED, "baseline"), (0.18, s, cs, ACC, "privileged student")]:
        vals = [m[k] for k, _ in keys]
        err = np.array([[m[k] - ci[k][0] for k, _ in keys], [ci[k][1] - m[k] for k, _ in keys]])
        ax.bar(xs + off, vals, width=0.34, color=col, label=lab, yerr=np.clip(err, 0, None), ecolor=INK, capsize=2,
               error_kw={"lw": 0.8})
    ax.set_xticks(xs); ax.set_xticklabels([k[1] for k in keys], fontsize=8); ax.set_ylim(0, 1.08)
    ax.legend(frameon=False, fontsize=7.5, loc="upper center", ncol=2, bbox_to_anchor=(0.5, 1.12))
    fig.tight_layout(); fig.savefig(OUT / "fig_performance.png", dpi=160); plt.close(fig)

    # Fig 2: when does the privileged eye help? (sweep)
    sw = res["sweep"]; g = np.array(sw["d_auroc"])
    fig, ax = plt.subplots(figsize=(6.4, 3.2))
    lim = max(np.abs(g).max(), 0.01)
    im = ax.imshow(g, cmap="RdBu", vmin=-lim, vmax=lim, aspect="auto", origin="lower")
    for i in range(g.shape[0]):
        for j in range(g.shape[1]):
            ax.text(j, i, f"{g[i, j]:+.3f}", ha="center", va="center", fontsize=8,
                    color="white" if abs(g[i, j]) > 0.6 * lim else INK)
    ax.set_xticks(range(len(sw["alpha"]))); ax.set_xticklabels([str(a) for a in sw["alpha"]])
    ax.set_yticks(range(len(sw["rho"]))); ax.set_yticklabels([str(r) for r in sw["rho"]])
    ax.set_xlabel("distillation weight α (0 = joint training, no distillation)"); ax.set_ylabel("inter-eye correlation of disease signal")
    fig.colorbar(im, ax=ax, fraction=0.04, pad=0.02, label="Δ AUROC (privileged − baseline)")
    fig.tight_layout(); fig.savefig(OUT / "fig_when_it_helps.png", dpi=160); plt.close(fig)

    # Fig 3: seed-to-seed spread (the paper used one split) and the FPR/precision trade-off
    sd = res["seeds"]
    fig, axs = plt.subplots(1, 2, figsize=(6.4, 2.7))
    axs[0].axhline(0, color=MUTED, lw=1, ls="--")
    jx = np.random.default_rng(0).uniform(-0.1, 0.1, len(sd["d_auroc"]))
    axs[0].scatter(jx[1:], sd["d_auroc"][1:], color=ACC, s=26)
    axs[0].scatter(jx[:1], sd["d_auroc"][:1], color="white", edgecolor=ACC, s=60, lw=1.8, zorder=5)
    axs[0].annotate("this card's split", (jx[0], sd["d_auroc"][0]), xytext=(10, 0), textcoords="offset points",
                    fontsize=7.5, va="center", color=INK)
    axs[0].plot([-0.2, 0.2], [sd["mean_d_auroc"]] * 2, color=INK, lw=2)
    axs[0].set_xlim(-0.5, 0.5); axs[0].set_xticks([]); axs[0].set_ylabel("Δ AUROC per cohort / split")
    axs[0].set_title(f"{sd['n_positive']}/{sd['n']} cohorts improved", fontsize=8.5, loc="left")
    axs[1].axhline(0, color=MUTED, lw=1, ls="--"); axs[1].axvline(0, color=MUTED, lw=1, ls="--")
    axs[1].scatter(sd["d_fpr"], sd["d_precision"], color=BLUE, s=26)
    axs[1].set_xlabel("Δ FPR (privileged − baseline)"); axs[1].set_ylabel("Δ precision")
    axs[1].set_title("threshold-dependent trade-off", fontsize=8.5, loc="left")
    fig.tight_layout(); fig.savefig(OUT / "fig_seeds_tradeoff.png", dpi=160); plt.close(fig)


def card(res):
    b, s = res["baseline"], res["privileged"]; ci = res["ci_d_auroc"]; sd = res["seeds"]
    tiles = [
        {"label": f"AUROC, {res['eye']} eye only", "value": f"{b['auroc']:.3f} → {s['auroc']:.3f}",
         "sub": f"baseline → privileged student; Δ 95% CI [{ci[0]:+.3f}, {ci[1]:+.3f}] (1,000 bootstraps)",
         "tone": "good" if res["d_auroc"] > 0 else "warn"},
        {"label": "Robust across cohorts?", "value": f"{sd['n_positive']} of {sd['n']}",
         "sub": f"independent cohorts/splits where AUROC improved; mean Δ {sd['mean_d_auroc']:+.3f} ± {sd['sd_d_auroc']:.3f}",
         "tone": "neutral"},
        {"label": "Trade-off at the macro-F1 threshold", "value": f"FPR {b['fpr']:.3f} → {s['fpr']:.3f}",
         "sub": f"precision {b['precision']:.3f} → {s['precision']:.3f}; recall {b['recall']:.3f} → {s['recall']:.3f}",
         "tone": "warn" if s["fpr"] > b["fpr"] else "neutral"},
        {"label": "Student ↔ teacher similarity", "value": f"ΔCKA {res['d_cka']:+.3f}",
         "sub": f"linear probe AUROC {res['probe']['baseline']:.3f} → {res['probe']['privileged']:.3f}; teacher (both eyes) {res['teacher_auroc']:.3f}",
         "tone": "neutral"},
    ]
    inputs = {"task preset": TASK, "eye at inference": EYE, "prevalence": PREV, "inter-eye correlation": RHO, "α": ALPHA,
              "eye noise L / R": f"{NOISE_L} / {NOISE_R}", "patients": N_PAT, "cohorts": N_SEEDS,
              "data": "toy simulated paired-eye features (not ODIR images)"}
    compare = [
        {"metric": "AUROC, baseline → privileged", "paper": "AMD left 0.931 → 0.966; AMD right 0.801 → 0.810; DR left 0.789 → 0.836; DR right 0.825 → 0.837",
         "yours": f"{b['auroc']:.3f} → {s['auroc']:.3f} ({res['eye']}, {TASK} preset)", "note": "toy: magnitudes are not comparable"},
        {"metric": "Balanced accuracy", "paper": "AMD left 0.834 → 0.879; DR left 0.576 → 0.749",
         "yours": f"{b['bal_acc']:.3f} → {s['bal_acc']:.3f}", "note": ""},
        {"metric": "FPR / precision trade-off", "paper": "AMD left FPR 0.011 → 0.027, precision 0.760 → 0.595; DR left FPR 0.766 → 0.089, precision 0.078 → 0.760",
         "yours": f"FPR {b['fpr']:.3f} → {s['fpr']:.3f}, precision {b['precision']:.3f} → {s['precision']:.3f}",
         "note": "both directions happen; depends on the validation threshold"},
        {"metric": "ΔCKA (student vs baseline, to teacher)", "paper": "+0.015 (DR); AMD inconclusive",
         "yours": f"{res['d_cka']:+.3f}", "note": "linear CKA, validation set"},
        {"metric": "Linear probe AUROC", "paper": "AMD 0.815 vs 0.836 (+2.0 points); DR +2.9 points",
         "yours": f"{res['probe']['baseline']:.3f} vs {res['probe']['privileged']:.3f} ({100 * res['d_probe']:+.1f} points)", "note": ""},
    ]
    figs = [{"path": "fig_performance.png", "title": "Does the one-eye student beat the one-eye baseline?",
             "caption": "Left: test ROC curves; dots = operating point at the threshold that maximised macro-F1 on validation. "
                        "Right: metrics with 95% bootstrap CIs (1,000 resamples of the test set)."},
            {"path": "fig_when_it_helps.png", "title": "When does the privileged eye help?",
             "caption": "Δ AUROC (student − baseline) as the two eyes' disease signals become more correlated, for different "
                        "distillation weights α (mean of 2 simulated cohorts per cell). Extension, not in the paper."},
            {"path": "fig_seeds_tradeoff.png", "title": "One split or many?",
             "caption": "The paper reports a single split. Left: Δ AUROC over independent simulated cohorts and splits. Right: "
                        "the precision/FPR change at the validation-chosen threshold flips direction between splits."}]
    Path(OUT / "card_data.json").write_text(json.dumps({
        "paper": {"num": 21, "title": "Two for One: Privileged Bilateral Learning for Monocular Retinal Disease Classification",
                  "authors": "Lisa Y.W. Tang", "url": "https://drive.google.com/file/d/1RKzJvGv1_Avf2kqHYQFnlwnWD78wedUW/", "affiliation": ""},
        "inputs": inputs, "tiles": tiles, "figures": figs, "compare": compare,
        "runbook": {"name": "smash-21-privileged-bilateral", "url": P.get("runbook_url", "")}}, indent=2))


if __name__ == "__main__":
    main()
/app/work/render_card.py
"""Render a SMASH 2026 paper-playground result card (one self-contained HTML file).

usage: python render_card.py card_data.json narrative.json out.html

card_data.json  (written by the experiment script — numbers only)
  paper:   {num, title, authors, affiliation, url?}
  inputs:  {label: value}                         the participant's run settings
  tiles:   [{label, value, sub, tone}]            tone: accent|good|warn|neutral
  figures: [{path, title, caption}]               PNGs, embedded as base64
  compare: [{metric, paper, yours, note}]         paper-vs-your-run table (optional)
  runbook: {name, url}                            fork link (optional)
narrative.json  (written by the agent — words only)
  headline:  one sentence, the finding of THIS run
  idea:      [1-3 bullets] the paper's contribution in plain language
  abstract:  (optional) a verbatim abstract excerpt, shown instead of idea
  findings:  [2-4 short paragraphs] what this run shows, tied to the numbers
  try_next:  [{label, why, params}]               2-3 follow-up runs with exact parameter values
  caveats:   [bullets]
"""
import base64, html, json, sys
from pathlib import Path

data = json.loads(Path(sys.argv[1]).read_text())
narr = json.loads(Path(sys.argv[2]).read_text())
base = Path(sys.argv[1]).parent
e = lambda s: html.escape(str(s))


def md_inline(s):
    """Escape, then allow **bold**, *italic* and `code` only."""
    import re
    s = e(s)
    s = re.sub(r"\*\*(.+?)\*\*", r"<strong>\1</strong>", s)
    s = re.sub(r"(?<![\w*])\*(?!\s)(.+?)(?<!\s)\*(?![\w*])", r"<em>\1</em>", s)
    return re.sub(r"`(.+?)`", r"<code>\1</code>", s)


p = data["paper"]
tiles = "".join(
    f'<div class="tile {e(t.get("tone", "neutral"))}"><div class="tl">{e(t["label"])}</div>'
    f'<div class="tv">{e(t["value"])}</div><div class="ts">{md_inline(t.get("sub", ""))}</div></div>'
    for t in data.get("tiles", []))
# Columns that fill every row: 4 tiles as 2x2, never 3 + 1 orphan.
n_tiles = len(data.get("tiles", []))
tile_cols = 2 if n_tiles == 4 else min(max(n_tiles, 1), 3)
inputs = "".join(f'<span class="chip"><b>{e(k)}</b> {e(v)}</span>' for k, v in data.get("inputs", {}).items())
figs = ""
for f in data.get("figures", []):
    fp = Path(f["path"]); fp = fp if fp.is_absolute() else base / fp
    if fp.exists():
        b64 = base64.b64encode(fp.read_bytes()).decode()
        figs += (f'<figure><figcaption class="ft">{e(f.get("title", ""))}</figcaption>'
                 f'<img alt="{e(f.get("title", ""))}" src="data:image/png;base64,{b64}">'
                 f'<figcaption>{md_inline(f.get("caption", ""))}</figcaption></figure>')
compare = ""
if data.get("compare"):
    rows = "".join(f'<tr><td>{md_inline(r["metric"])}</td><td>{md_inline(r["paper"])}</td>'
                   f'<td class="y">{md_inline(r["yours"])}</td><td class="n">{md_inline(r.get("note", ""))}</td></tr>'
                   for r in data["compare"])
    compare = (f'<section><h2>Paper vs. your run</h2><div class="tw"><table><thead><tr><th>Metric</th>'
               f'<th>Paper</th><th>Your run</th><th></th></tr></thead><tbody>{rows}</tbody></table></div></section>')
idea = "".join(f"<li>{md_inline(b)}</li>" for b in narr.get("idea", []))
abstract = narr.get("abstract", "")
findings = "".join(f"<p>{md_inline(x)}</p>" for x in narr.get("findings", []))
tries = "".join(
    f'<li><strong>{md_inline(t["label"])}</strong> — {md_inline(t.get("why", ""))}'
    f'<pre>{e(json.dumps(t.get("params", {}), ensure_ascii=False))}</pre></li>' for t in narr.get("try_next", []))
cav = "".join(f"<li>{md_inline(c)}</li>" for c in narr.get("caveats", []))
rb = data.get("runbook", {})
fork = (f'<a class="fork" href="{e(rb["url"])}">Fork this runbook on Jetty →</a>' if rb.get("url") else "")

page = f"""<!doctype html><html lang="en"><head><meta charset="utf-8">
<meta name="viewport" content="width=device-width,initial-scale=1">
<title>SMASH 2026 · #{e(p['num'])} · Result card</title>
<style>
:root{{--bg:#f6f4ef;--card:#fff;--ink:#1f2a44;--muted:#5c677d;--line:#e3dfd5;--accent:#d9480f;--good:#2b8a3e;--warn:#e67700;--chip:#efece4}}
@media (prefers-color-scheme:dark){{:root{{--bg:#11151f;--card:#1a2030;--ink:#e8ebf2;--muted:#9aa4b8;--line:#2c3447;--accent:#ff8a4c;--good:#69db7c;--warn:#ffc078;--chip:#232b3d}}
figure img{{background:#fff;border-radius:6px}}}}
*{{box-sizing:border-box}}body{{margin:0;background:var(--bg);color:var(--ink);font:15px/1.55 ui-sans-serif,system-ui,-apple-system,"Segoe UI",Roboto,sans-serif}}
main{{max-width:860px;margin:0 auto;padding:28px 16px 48px}}
.kicker{{font:600 12px/1 ui-monospace,SFMono-Regular,Menlo,monospace;letter-spacing:.08em;text-transform:uppercase;color:var(--accent)}}
h1{{font-size:clamp(22px,4vw,30px);line-height:1.2;margin:10px 0 6px}}.authors{{color:var(--muted);margin:0 0 18px}}.authors a{{color:var(--accent);text-underline-offset:3px}}
.headline{{background:var(--card);border:1px solid var(--line);border-left:5px solid var(--accent);border-radius:10px;padding:16px 18px;font-size:18px;font-weight:600;margin:0 0 18px}}
.chips{{display:flex;flex-wrap:wrap;gap:6px;margin:0 0 18px}}.chip{{background:var(--chip);border-radius:999px;padding:4px 10px;font-size:12.5px}}.chip b{{font-weight:600;color:var(--muted);margin-right:4px}}
.tiles{{display:grid;grid-template-columns:repeat(var(--cols),minmax(0,1fr));gap:10px;margin:0 0 22px}}
@media (max-width:560px){{.tiles{{grid-template-columns:1fr}}}}
.tile{{background:var(--card);border:1px solid var(--line);border-radius:10px;padding:12px 14px}}.tl{{font-size:12px;color:var(--muted);text-transform:uppercase;letter-spacing:.04em}}
.tv{{font-size:26px;font-weight:700;margin:2px 0;font-variant-numeric:tabular-nums}}.ts{{font-size:12.5px;color:var(--muted)}}
.tile.accent .tv{{color:var(--accent)}}.tile.good .tv{{color:var(--good)}}.tile.warn .tv{{color:var(--warn)}}
section{{background:var(--card);border:1px solid var(--line);border-radius:12px;padding:18px 20px;margin:0 0 16px}}
h2{{font-size:16px;margin:0 0 10px}}ul{{padding-left:20px;margin:0}}li{{margin:4px 0}}p{{margin:0 0 10px}}
figure{{margin:0 0 18px}}figure img{{width:100%;height:auto;display:block}}figcaption{{font-size:13px;color:var(--muted);margin-top:6px}}.ft{{font-weight:600;color:var(--ink);font-size:14px;margin:0 0 6px}}
.tw{{overflow-x:auto}}table{{border-collapse:collapse;width:100%;font-size:13.5px;font-variant-numeric:tabular-nums}}th,td{{text-align:left;padding:7px 8px;border-bottom:1px solid var(--line);vertical-align:top}}th{{color:var(--muted);font-weight:600}}td.y{{font-weight:600}}td.n{{color:var(--muted);font-size:12.5px}}
pre{{background:var(--chip);border-radius:6px;padding:6px 8px;font-size:12px;white-space:pre-wrap;word-break:break-word;margin:4px 0 8px}}code{{background:var(--chip);border-radius:4px;padding:1px 4px;font-size:.92em}}
.fork{{display:inline-block;background:var(--ink);color:var(--bg);text-decoration:none;font-weight:600;border-radius:8px;padding:10px 14px;margin-top:6px}}
footer{{color:var(--muted);font-size:12.5px;margin-top:22px}}
.abs{{margin:0;padding-left:14px;border-left:3px solid var(--accent);color:var(--ink)}}
</style></head><body><main>
<div class="kicker">SMASH 2026 · Paper #{e(p['num'])} · Result card</div>
<h1>{e(p['title'])}</h1><p class="authors">{e(p['authors'])}{(' · ' + e(p['affiliation'])) if p.get('affiliation') else ''}{(f' · <a href="{e(p["url"])}">Read the paper</a>') if p.get('url') else ''}</p>
<div class="headline">{md_inline(narr['headline'])}</div>
<div class="chips">{inputs}</div>
<div class="tiles" style="--cols:{tile_cols}">{tiles}</div>
{f'<section><h2>From the abstract</h2><blockquote class="abs">{e(abstract)}</blockquote></section>' if abstract else f'<section><h2>The idea</h2><ul>{idea}</ul></section>'}
{f'<section><h2>What this run shows</h2>{findings}</section>' if findings else ''}
<section><h2>Evidence</h2>{figs}</section>
{compare}
<section><h2>Try next</h2><ul>{tries}</ul>{fork}</section>
<section><h2>Read this before sharing</h2><ul>{cav}</ul></section>
<footer>Generated by a Jetty runbook built from the authors' SMASH 2026 paper. Numbers on this card come from code run in a sandbox; the words were written by an AI agent reading those numbers. This is an interactive companion, not the authors' own results unless labelled “Paper”.</footer>
</main></body></html>"""
Path(sys.argv[3]).write_text(page)
print(f"wrote {sys.argv[3]} ({len(page) // 1024} KB)")
/app/work/validate.py
"""Self-check a SMASH paper-playground run and write validation_report.json (evals v2 shape).

Runs the same checks as the runbook's `## Code Checks` (which Jetty re-runs independently after the agent
exits and substitutes for these entries), adds one `step` entry per runbook step and the agent's checklist
judgements, and prints PASS/FAIL lines.

usage: python validate.py <results_dir> <param,param,...> <budget_sec> [checklist.json]
"""
import html, json, re, sys
from pathlib import Path

R = Path(sys.argv[1])
allowed = set(sys.argv[2].split(","))
budget = float(sys.argv[3])
checklist_path = Path(sys.argv[4]) if len(sys.argv) > 4 else None


def load(name):
    try:
        return json.loads((R / name).read_text())
    except Exception:
        return None


res, cdata, narr = load("results.json"), load("card_data.json"), load("narrative.json")
card = (R / "result_card.html").read_text() if (R / "result_card.html").exists() else ""


def c_outputs_exist():
    missing = [f for f in ["result_card.html", "results.json", "card_data.json", "narrative.json", "summary.md"]
               if not (R / f).exists() or (R / f).stat().st_size == 0]
    return not missing, f"missing or empty: {missing}" if missing else "all 5 outputs present"


def c_results_valid():
    if res is None or cdata is None:
        return False, "results.json or card_data.json does not parse"
    rt = float(res.get("runtime_sec", 0))
    return rt <= budget, f"experiment {rt}s (budget {budget:.0f}s)"


def c_narrative_complete():
    if narr is None:
        return False, "narrative.json does not parse"
    p = []
    if not str(narr.get("headline", "")).strip(): p.append("no headline")
    if len(str(narr.get("headline", "")).split()) > 45: p.append("headline over 45 words")
    if not 1 <= len(narr.get("idea", [])) <= 3: p.append(f"idea has {len(narr.get('idea', []))} bullets, need 1-3")
    if not 1 <= len(narr.get("findings", [])) <= 2: p.append(f"{len(narr.get('findings', []))} findings, need 1-2")
    if any(len(f.split()) > 70 for f in narr.get("findings", [])): p.append("a findings paragraph is over 60 words")
    if not 2 <= len(narr.get("try_next", [])) <= 3: p.append(f"{len(narr.get('try_next', []))} try_next, need 2-3")
    if not 1 <= len(narr.get("caveats", [])) <= 2: p.append(f"{len(narr.get('caveats', []))} caveats, need 1-2")
    return not p, "; ".join(p) or "complete and within the length limits"


def c_try_next_valid():
    if narr is None:
        return False, "narrative.json does not parse"
    bad = sorted({k for t in narr.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
    empty = [t.get("label", "?") for t in narr.get("try_next", []) if not t.get("params")]
    ok = not bad and not empty
    return ok, "all try_next parameters are declared" if ok else f"unknown parameters: {bad}; without params: {empty}"


def c_headline_grounded():
    if narr is None or res is None:
        return False, "missing narrative or results"
    blob = json.dumps(res) + json.dumps(cdata or {})
    vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
    nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", narr.get("headline", ""))
    missing = []
    for n in nums:
        s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
        tol = 0.5 * 10 ** (-dec) + 1e-9
        if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
            missing.append(n)
    return not missing, f"not found in results: {missing}" if missing else f"{len(nums)} headline number(s) grounded"


def c_card_integrity():
    if not card or narr is None:
        return False, "no card or narrative"
    text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
    plain = html.unescape(re.sub(r"<[^>]+>", "", text))
    p = []
    if card.count("data:image/png;base64") < 1: p.append("no embedded figures")
    if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): p.append("NaN/Infinity in card text")
    if len(card) > 5_000_000: p.append(f"card is {len(card) // 1024} KB")
    if re.sub(r"[*`]", "", narr.get("headline", ""))[:40] not in plain: p.append("headline not on card")
    return not p, "; ".join(p) or f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures"


CODE_CHECKS = [  # ids and names match the runbook's ## Code Checks headings
    ("outputs-exist", "Result card, numbers, narrative and summary were written", c_outputs_exist),
    ("results-valid", "Experiment numbers are valid JSON and the experiment stayed within its time budget", c_results_valid),
    ("narrative-complete", "The narrative is complete and within the length limits", c_narrative_complete),
    ("try-next-valid", "Every try-next suggestion uses only this runbook's parameters", c_try_next_valid),
    ("headline-grounded", "Every number in the headline appears in the run's results", c_headline_grounded),
    ("card-integrity", "The card embeds its figures, shows the headline, and contains no NaN", c_card_integrity),
]
STEPS = [  # (id, name, evidence that the step happened)
    ("setup", "Set up the sandbox and parameters", Path("/app/work/params.json").exists() or res is not None),
    ("get-code", "Extract the tested code", Path("/app/work/experiment.py").exists() or res is not None),
    ("experiment", "Run the experiment", res is not None),
    ("interpret", "Write the narrative", narr is not None),
    ("render", "Render the result card and summary", bool(card) and (R / "summary.md").exists()),
]

checks = [{"kind": "step", "id": i, "name": n, "status": "pass" if ok else "fail"} for i, n, ok in STEPS]
for cid, name, fn in CODE_CHECKS:
    try:
        ok, msg = fn()
    except Exception as e:  # a check that crashes is an error, never a silent pass
        ok, msg = None, f"{type(e).__name__}: {e}"
    status = "pass" if ok else ("error" if ok is None else "fail")
    checks.append({"kind": "code_check", "id": cid, "name": name, "status": status, "message": str(msg)[:1000]})
    print(f"{'PASS' if ok else 'FAIL'} {cid}: {msg}")

if checklist_path and checklist_path.exists():
    for item in json.loads(checklist_path.read_text()):
        st = item.get("status", "skipped")
        st = st if st in ("pass", "fail", "skipped", "error") else "skipped"
        checks.append({"kind": "checklist", "id": str(item["id"]), "name": str(item.get("name") or item["id"]),
                       "status": st, "message": str(item.get("message", ""))[:1000]})
        print(f"{'PASS' if st == 'pass' else 'FAIL'} checklist {item['id']}: {item.get('message', '')}")
else:
    print("NOTE no checklist.json given; checklist items will be recorded as not reported")

gating = [c for c in checks if c["kind"] != "step"]
verdict = "fail" if any(c["status"] in ("fail", "error") for c in gating) else ("pass" if gating else "unknown")
(R / "validation_report.json").write_text(json.dumps({"version": 2, "verdict": verdict, "checks": checks}, indent=2))
print(json.dumps({"verdict": verdict, "passed": sum(c["status"] == "pass" for c in gating), "gating_checks": len(gating)}))