Prevalence, Thresholds, and Subgroup Performance Gaps in Clinical Prediction Models Across Five Public Datasets
Zavash Ghorbanpourbaboli, Arina Afshar, Elham Jangravi, Mohammed Ayoub Alaoui Mhamdi, Russell Butler · SMASH 2026 posterRead the paper ↗
From the abstractClinical prediction models are commonly compared across demographic subgroups, but a raw performance gap is not a fixed property of a model. Observed gaps should prompt investigation of metric choice, prevalence, threshold, sample composition, measured case mix, and uncertainty rather than being treated alone as proof of discrimination, fairness, or equivalence.
Example runs
Default inputs
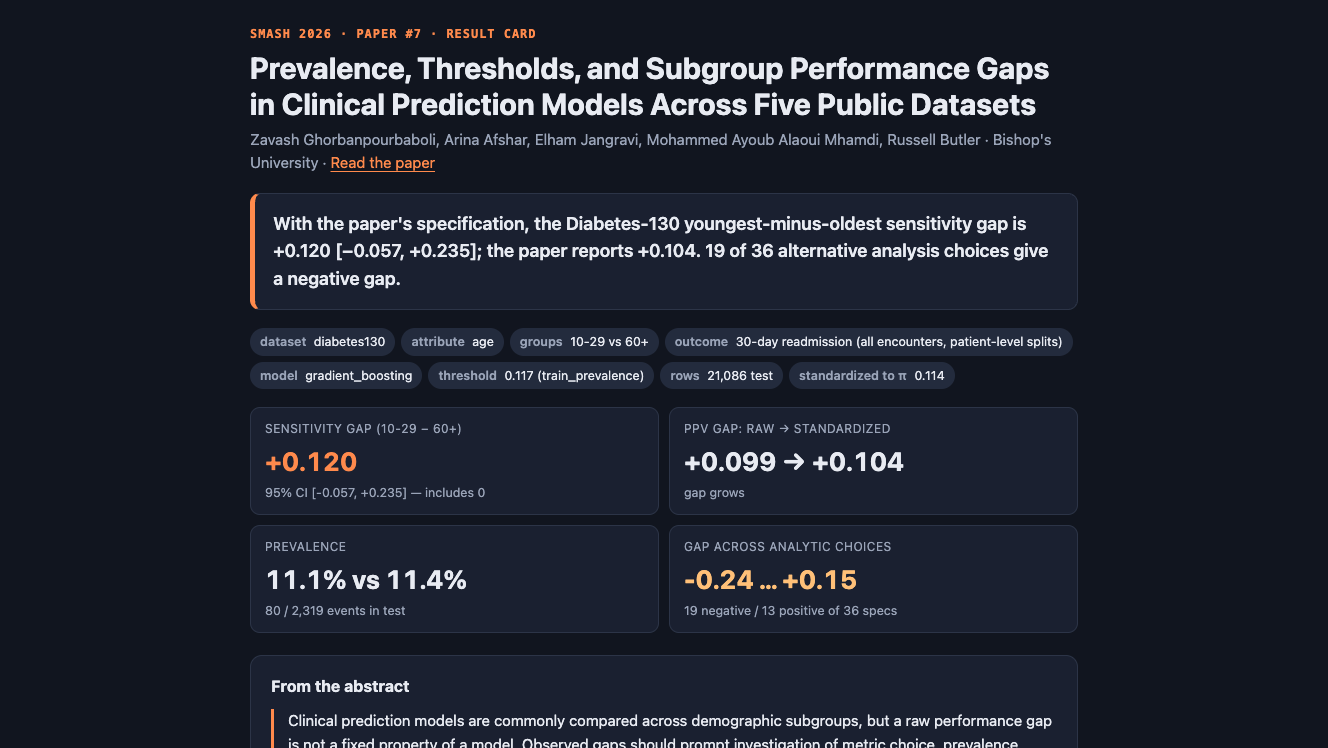
With the paper's specification, the Diabetes-130 youngest-minus-oldest sensitivity gap is +0.120 [−0.057, +0.235]; the paper reports +0.104. 19 of 36 alternative analysis choices give a negative gap. Model hyperparameters and variable encodings are this runbook's; the predictor set and age bands follow the paper. No fairness verdict is implied.
Inputs
Acceptance checklist
15/15 checks passed.- Set up the sandbox and parameters
- Extract the tested code
- Run the experiment
- Write the narrative
- Render the result card and summary
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
- Result card, numbers, narrative and summary were written
- Experiment numbers are valid JSON and the experiment stayed within its time budget
- The narrative is complete and within the length limits
- Every try-next suggestion uses only this runbook's parameters
- Every number in the headline appears in the run's results
- The card embeds its figures, shows the headline, and contains no NaN
Runbook
| version | 1.0.0 |
| evaluation | programmatic |
| evals_version | 2 |
| agent | claude-code |
| model | anthropic/claude-haiku-5.5 |
| model_provider | openrouter |
| snapshot | python312-uv |
| primary_outputs | result_card.html |
Gap Audit: Is That Subgroup Gap Real? (SMASH 2026 · Paper #7)
Objective
This runbook is an interactive companion to the SMASH 2026 paper "Prevalence, Thresholds, and Subgroup Performance Gaps in Clinical Prediction Models Across Five Public Datasets" (Zavash Ghorbanpourbaboli, Arina Afshar, Elham Jangravi, Mohammed Ayoub Alaoui Mhamdi, Russell Butler). Read the paper: https://drive.google.com/file/d/1MnK-mFUFDe2Josf706Rgn4RxZMB6df3M/view?usp=sharing
The paper's claim: a raw subgroup performance gap is not a fixed property of a model. Its size and even its sign depend on the metric, outcome prevalence, operating threshold, sample composition and uncertainty, so a gap is a signal to investigate, not a verdict of (un)fairness.
The participant picks a public dataset and a demographic comparison (or pastes their own model's confusion matrices). The run reproduces the paper's workflow end-to-end and produces a shareable result card showing how much of the gap survives:
- Uncertainty: sensitivity difference with a subgroup-stratified bootstrap CI (paper's primary endpoint)
- Prevalence: PPV gap before vs after standardizing to a common prevalence
- Threshold: every metric's gap swept across operating thresholds
- Analyst choices: a "multiverse" of defensible data-preparation choices (an extension that makes the paper's sample composition point visible)
Target wall-clock: under 5 minutes. Do not explore beyond these steps.
The method, as in the published paper (§2 and predictor table)
- Restrict to the two compared groups; exclude the demographic variable from predictors. Predictors follow the
paper's table (CDC: the sex comparison keeps
Age, the age comparison dropsAgeandSex; Diabetes-130: counts, admission codes, the 23 medication columns,max_glu_serum,A1Cresult,change,diabetesMed, plusage_numericand race indicators unless they define the comparison). - 70/30 train/test split, seed 42, separately per comparison. Diabetes-130 keeps every encounter and partitions, cross-validates, calibrates and resamples by patient; its 0–9 age band is excluded from the age comparison.
- One shared model per comparison, selected among logistic regression, L1 logistic regression, random forest, shallow tree, gradient boosting and a soft-voting ensemble by 5-fold training-only CV AUC; then 5-fold isotonic fold-ensemble calibration on training data.
- Threshold τ = unweighted training-sample outcome prevalence, applied to both groups.
- Endpoint: sensitivity difference (Male − Female, youngest − oldest, first-named race group − reference). Age bands: CDC 18–44 vs 65+; Diabetes-130 10–29 vs 60+.
- 95% percentile CI from 1,000 replicates: rows resampled within each subgroup; for Diabetes-130, patients resampled with replacement, each carrying all of their encounters.
- PPV standardization: hold each group's Se and Sp fixed, recompute PPV at the pooled test prevalence:
PPV = Se·π / (Se·π + (1 − Sp)(1 − π)).
Paper headline numbers (published version; quote exactly)
- 7 of 13 sensitivity CIs excluded zero (3 sex, 4 age); none of the 3 race/ethnicity CIs did.
- Male − Female: CDC Diabetes −0.033 [−0.048, −0.019]; Diabetes-130 −0.049 [−0.084, −0.011]; BRFSS 2022 −0.022 [−0.037, −0.008].
- Youngest − oldest: CDC −0.207 [−0.241, −0.170]; BRFSS −0.379; NHANES −0.311; CCHS −0.474; Diabetes-130 +0.104 [−0.070, +0.232] (the only positive).
- Race/ethnicity: Diabetes-130 AfricanAmerican − Caucasian −0.040 [−0.090, +0.006]; all three race intervals include zero.
- PPV standardization: BRFSS M−F +0.101 → +0.016 (both intervals exclude zero); CCHS M−F +0.053 → −0.005 (the standardized interval spans zero, so the reversal is of the point estimate only); BRFSS Black−White −0.051 → −0.009.
REQUIRED OUTPUT FILES (MANDATORY)
All in {{results_dir}}:
| File | Description |
|---|---|
result_card.html | Primary output. Self-contained, shareable one-page result card |
results.json | All computed numbers (written by experiment.py) |
card_data.json | Numbers/figures for the card (written by experiment.py) |
narrative.json | Your interpretation of this run (Step 4) |
fig_*.png | Figures (written by experiment.py) |
summary.md | 5–10 line plain-text summary of the run |
validation_report.json | Evals v2 report: steps, code checks, checklist (see Write Validation Report) |
Parameters
| Parameter | Template Variable | Default | Description |
|---|---|---|---|
| Dataset | {{dataset}} | diabetes130 | diabetes130 (UCI Diabetes 130-US Hospitals, 30-day readmission) or cdc_diabetes (UCI CDC Diabetes Health Indicators) |
| Attribute | {{attribute}} | age | sex, age, or race (race: diabetes130 only) |
| Age bands | {{age_bands}} | — | Age comparison bands. diabetes130: 10-29 vs 60+ (paper, default), <50 vs 70+, 10-29 vs 80+. cdc_diabetes: 18-44 vs 65+ (default), 18-24 vs 80+, 18-34 vs 70+ |
| Group A | {{group_a}} | — | Override first group for sex/race (e.g. Asian, Hispanic, Female). Blank = paper default |
| Group B | {{group_b}} | — | Override reference group (e.g. Caucasian, Male). Blank = paper default |
| Threshold | {{threshold}} | train_prevalence | train_prevalence (paper), top20 (flag top 20% risk), or a number like 0.3 |
| Target prevalence | {{target_prevalence}} | pooled | Common prevalence for PPV standardization: pooled (paper) or a number like 0.05 |
| Model | {{model}} | auto | auto (paper's 6-family CV selection) or one of logistic, l1_logistic, shallow_tree, random_forest, gradient_boosting, soft_voting |
| Multiverse | {{multiverse}} | true | Re-run the estimate across defensible analytic choices (true/false) |
| Your confusion matrices | {{byo_confusion}} | — | Skip the datasets and audit your own model: GroupA:TP,FP,TN,FN; GroupB:TP,FP,TN,FN (e.g. Women:80,40,800,30; Men:120,90,700,25) |
Dependencies
Everything needed (numpy, pandas, scikit-learn, matplotlib) is preinstalled in the python312-uv sandbox.
Verify with python -c "import numpy, pandas, sklearn, matplotlib"; only if that fails run
uv pip install --system numpy pandas scikit-learn matplotlib. Data is downloaded from the UCI Machine
Learning Repository at run time (~3–13 MB).
Step 1: Set up
mkdir -p {{results_dir}} /app/work && cd /app/work
python -c "import numpy, pandas, sklearn, matplotlib" 2>/dev/null || uv pip install --system -q numpy pandas scikit-learn matplotlib
Write /app/work/params.json from the parameters. Substitute values exactly; use "" for blanks; n_boot,
max_rows, cv_rows, multiverse_rows are fixed budget settings — do not change them:
{"dataset": "{{dataset}}", "attribute": "{{attribute}}", "age_bands": "{{age_bands}}",
 "group_a": "{{group_a}}", "group_b": "{{group_b}}", "threshold": "{{threshold}}",
 "target_prevalence": "{{target_prevalence}}", "model": "{{model}}", "multiverse": "{{multiverse}}",
 "byo_confusion": "{{byo_confusion}}",
 "n_boot": 1000, "max_rows": 300000, "cv_rows": 20000, "multiverse_rows": 60000, "runbook_url": ""}
If a value still looks like an unsubstituted placeholder (starts with {{), use the default from the table.
Convert multiverse to a JSON boolean.
Step 2: Get the code (extract it, don't retype it)
The tested implementation of the method is embedded in the Appendix at the end of this runbook. Do not rewrite, "improve", or re-derive it. Always run the command below first, exactly as written. It copies the files out of this runbook's text (which the sandbox exposes to running processes) in about a second, and it is far faster and more reliable than retyping several hundred lines. Do not skip it on the assumption that it won't work: run it and read its output.
cd /app/work && cat > extract.py <<'PYEOF'
"""Extract the runbook's embedded files without retyping them.

The runbook text reaches the agent as one command-line argument, so it is readable from /proc.
Every embedded file sits under a heading "### `/app/work/<name>`" followed by one fenced block.
Exits non-zero if any requested file can't be found, so the caller falls back to writing it by hand.

usage: python3 extract.py <name> [<name> ...]   (writes /app/work/<name>)
"""
import ast, glob, re, sys
from pathlib import Path

want = sys.argv[1:]
cands = []
for p in glob.glob("/proc/[0-9]*/cmdline"):
    try:
        s = Path(p).read_bytes().decode("utf-8", "ignore")
    except OSError:
        continue
    if all(f"### `/app/work/{w}`" in s for w in want):
        cands.append(s)
if not cands:
    sys.exit("runbook text not found in /proc; write the files by hand")
# The agent's own argv holds the raw text; wrapper shells hold a shell-quoted copy, so prefer the shortest
# and undo shell single-quote escaping as a fallback.
best = min(cands, key=len).replace("'\"'\"'", "'")
ok = True
for w in want:
    m = re.search(r"### `/app/work/" + re.escape(w) + r"`\s*\n+```[a-z]*\n(.*?)\n```\n", best, re.S)
    if not m or len(m.group(1)) < 50:
        print(f"MISSING {w}"); ok = False; continue
    code = m.group(1) + "\n"
    if w.endswith(".py"):
        try:
            ast.parse(code)
        except SyntaxError as e:
            print(f"MISSING {w} (extracted text does not parse: {e})"); ok = False; continue
    Path("/app/work", w).write_text(code)
    print(f"extracted {w}: {code.count(chr(10))} lines")
sys.exit(0 if ok else 1)
PYEOF
python3 extract.py experiment.py render_card.py validate.py
If it exits non-zero or prints MISSING, write each missing file from the Appendix exactly as given, one
heredoc per file (quoted delimiter, e.g. cat > experiment.py <<'PYEOF'). If a later step fails, fix only
environment problems (missing package, network retry), never the methodology.
Step 3: Run the experiment
cd /app/work && export OMP_NUM_THREADS=4 OPENBLAS_NUM_THREADS=4 MKL_NUM_THREADS=4 SMASH_CPUS=4 && timeout 330 python experiment.py params.json {{results_dir}}Expected: ~30–90 s. It prints progress and ends with a done: line. If the download fails, retry once.
If it exits with an input error (e.g. unknown group name, race on cdc_diabetes), fall back to the
paper default for that parameter, rerun once, and record the substitution in summary.md and in a caveat.
The sandbox has 4 CPUs even though nproc may report more; the exports keep numpy/BLAS and process pools from oversubscribing them.
Step 4: Interpret: write narrative.json
Read {{results_dir}}/results.json and card_data.json, and look at every fig_*.png. Then write
{{results_dir}}/narrative.json:
{"headline": "...", "idea": ["...", "...", "..."], "findings": ["...", "..."],
 "try_next": [{"label": "...", "why": "...", "params": {"attribute": "sex"}}],
 "caveats": ["...", "..."]}
Rules, written for a conference audience that has not read the paper:
- headline: one sentence (≤ 30 words) stating the most surprising finding of this run, with 1–2 numbers
copied from
results.json(rounded as on the card). Not a description of the method. Pick the most counter-intuitive of: the multiverse splitting into both signs (multiverse_summary), the PPV gap flipping sign after standardization, the gap vanishing at another threshold, or a gap that is robust to everything. - Keep it tight: each
findingsparagraph ≤ 70 words; bold the one number that matters in each. - idea: exactly 3 bullets explaining the paper's contribution in plain language (use the Objective above).
- findings: 2–4 short paragraphs. Walk through the four questions in order: is the sensitivity gap
distinguishable from zero; how much of the PPV gap is prevalence (did it shrink or flip?); does the gap
depend on the threshold (quote the range from
se_gap_range_over_thresholds); and, if present, how many multiverse specifications change the sign. Compare with the paper's number for the same dataset/attribute when one exists, and say plainly when your run disagrees. With default inputs the run follows the paper's published specification; differences come from model hyperparameters, the variable encodings, or inputs the participant changed (name which). - Never call a model or subgroup result "fair", "unfair", "biased" or "discriminatory"; the paper explicitly declines that verdict. A CI including zero does not establish equivalence.
- try_next: 2–3 follow-up runs that would produce a contrasting result, each with exact parameter values
using only these keys:
dataset, attribute, age_bands, group_a, group_b, threshold, target_prevalence, model, multiverse, byo_confusion. Example: if the gap was robust, suggest the comparison the multiverse found most fragile; if it flipped, suggest a threshold where it disappears. - caveats: 2–4 bullets (unweighted extracts; reconstructed outcome/feature coding; not a fairness verdict; any parameter substitutions you made).
- In BYO mode (
mode == "byo"), there is no paper comparison or threshold sweep; focus on CI and prevalence.
Step 5: Render the card and summary
cd /app/work && python render_card.py {{results_dir}}/card_data.json {{results_dir}}/narrative.json {{results_dir}}/result_card.htmlWrite {{results_dir}}/summary.md: dataset/comparison, the sensitivity gap with CI, raw → standardized PPV
gap, threshold range, multiverse sign counts, and the headline.
Writing style for narrative.json
These rules apply to every field and override any longer limits stated earlier in this runbook. Let the paper and the numbers speak; the card is not the place for commentary.
- Length:
headlineone sentence;idea1–3 bullets of at most 30 words;findings1–2 paragraphs of at most 60 words each;caveats1–2 bullets of at most 20 words. Cut anything the tiles, figures or tables already show. - Plain statements of what was measured. Write "Sensitivity gap −0.284 [−0.354, −0.218]; the paper reports +0.088", not an interpretation of what it means for the field.
- Avoid: em-dash asides; "not X, but Y" framings; colon-then-reveal sentences; rhetorical questions; words such as crucially, notably, strikingly, remarkably, collapses, illustrating, underscores, highlights, delve, powerful, key insight, worth noting; exclamation marks; restating the method before the result.
- Use the paper's own terms for its concepts. Quote the paper's numbers exactly.
Code Checks
Jetty runs these checks itself in the sandbox after the agent finishes, so they cannot be skipped or
misreported. validate.py (see Write Validation Report) runs the same checks first so you can fix problems before you stop.
outputs-exist — Result card, numbers, narrative and summary were written
cd {{results_dir}} && for f in result_card.html results.json card_data.json narrative.json summary.md; do test -s "$f" || { echo "missing or empty: $f"; exit 1; }; done; echo "all 5 outputs present"results-valid — Experiment numbers are valid JSON and the experiment stayed within its time budget
python3 - "{{results_dir}}" 330 <<'PY'
import json, sys
from pathlib import Path
R, budget = Path(sys.argv[1]), float(sys.argv[2])
res = json.loads((R / "results.json").read_text())
json.loads((R / "card_data.json").read_text())
rt = float(res.get("runtime_sec", 0))
if rt > budget:
    sys.exit(f"experiment took {rt}s, budget {budget}s")
print(f"results.json and card_data.json parse; experiment {rt}s within {budget:.0f}s")
PY
narrative-complete — The narrative is complete and within the length limits
python3 - "{{results_dir}}" <<'PY'
import json, sys
from pathlib import Path
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
problems = []
if not str(n.get("headline", "")).strip(): problems.append("no headline")
if len(str(n.get("headline", "")).split()) > 45: problems.append("headline over 45 words")
if not 1 <= len(n.get("idea", [])) <= 3: problems.append(f"idea has {len(n.get('idea', []))} bullets, need 1-3")
if not 1 <= len(n.get("findings", [])) <= 2: problems.append(f"{len(n.get('findings', []))} findings, need 1-2")
if any(len(f.split()) > 70 for f in n.get("findings", [])): problems.append("a findings paragraph is over 60 words")
if not 2 <= len(n.get("try_next", [])) <= 3: problems.append(f"{len(n.get('try_next', []))} try_next, need 2-3")
if not 1 <= len(n.get("caveats", [])) <= 2: problems.append(f"{len(n.get('caveats', []))} caveats, need 1-2")
if problems: sys.exit("; ".join(problems))
print("headline, %d idea bullets, %d findings, %d try_next, %d caveats" % (len(n["idea"]), len(n["findings"]), len(n["try_next"]), len(n["caveats"])))
PY
try-next-valid — Every try-next suggestion uses only this runbook's parameters
python3 - "{{results_dir}}" "dataset,attribute,age_bands,group_a,group_b,threshold,target_prevalence,model,multiverse,byo_confusion" <<'PY'
import json, sys
from pathlib import Path
allowed = set(sys.argv[2].split(","))
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
bad = sorted({k for t in n.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
empty = [t.get("label", "?") for t in n.get("try_next", []) if not t.get("params")]
if bad or empty: sys.exit(f"unknown parameters: {bad}; suggestions without params: {empty}")
print("all try_next parameters are declared runbook parameters")
PY
headline-grounded — Every number in the headline appears in the run's results
python3 - "{{results_dir}}" <<'PY'
import json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
blob = (R / "results.json").read_text() + (R / "card_data.json").read_text()
vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
head = json.loads((R / "narrative.json").read_text())["headline"]
nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", head)
missing = []
for n in nums:
    s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
    tol = 0.5 * 10 ** (-dec) + 1e-9
    if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
        missing.append(n)
if missing: sys.exit(f"headline numbers not found in results: {missing}")
print(f"{len(nums)} headline number(s) all grounded in results")
PY
card-integrity — The card embeds its figures, shows the headline, and contains no NaN
python3 - "{{results_dir}}" <<'PY'
import html, json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
card = (R / "result_card.html").read_text()
text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
head = json.loads((R / "narrative.json").read_text())["headline"]
problems = []
if card.count("data:image/png;base64") < 1: problems.append("no embedded figures")
if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): problems.append("NaN/Infinity in card text")
if len(card) > 5_000_000: problems.append(f"card is {len(card) // 1024} KB")
plain = html.unescape(re.sub(r"<[^>]+>", "", text))
if re.sub(r"[*`]", "", head)[:40] not in plain: problems.append("headline not on card")
if problems: sys.exit("; ".join(problems))
print(f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures, headline present")
PY
Checklist
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
Write Validation Report
Judge the four Checklist items honestly against your outputs and write them to /app/work/checklist.json as a
list, using the checklist ids Jetty gives you (one entry per item):
[{"id": "<checklist id>", "status": "pass", "message": "one line on why"}]Then write the report and self-check in one command:
cd /app/work && python3 validate.py {{results_dir}} dataset,attribute,age_bands,group_a,group_b,threshold,target_prevalence,model,multiverse,byo_confusion 330 checklist.jsonvalidate.py writes {{results_dir}}/validation_report.json in the v2 shape Jetty reads (version: 2, one
step entry per runbook step, one code_check entry per check above, one checklist entry per item). Jetty
replaces the code_check entries with its own independent run of the same checks. Do not write the report by hand.
Iteration (up to 2 rounds)
If validate.py prints any FAIL, fix the named problem (usually a headline number that does not match
results.json, or an unknown try_next key), re-render the card (Step 5) and rerun the command above. Never
rerun the experiment just to change the narrative.
Appendix: code
These files are extracted verbatim in Step 2.
/app/work/experiment.py
"""Gap Audit — SMASH 2026 paper #7 (Ghorbanpourbaboli, Afshar, Jangravi, Alaoui Mhamdi, Butler).

Reproduces the paper's workflow on a public UCI dataset (or on the participant's own
confusion matrices) and asks: how much of a subgroup gap survives a change of metric,
prevalence, threshold — and of the analyst's own data-preparation choices?

usage: python experiment.py params.json outdir
"""
import io, itertools, os, json, sys, time, warnings, zipfile, urllib.request
from pathlib import Path

import numpy as np
import pandas as pd
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt
from sklearn.model_selection import GroupShuffleSplit, StratifiedGroupKFold, cross_val_score, train_test_split
from sklearn.linear_model import LogisticRegression
from sklearn.tree import DecisionTreeClassifier
from sklearn.ensemble import RandomForestClassifier, HistGradientBoostingClassifier, VotingClassifier
from sklearn.calibration import CalibratedClassifierCV
from sklearn.preprocessing import StandardScaler
from sklearn.pipeline import make_pipeline
from sklearn.metrics import roc_auc_score

warnings.filterwarnings("ignore")
T0 = time.time()
P = json.loads(Path(sys.argv[1]).read_text())
OUT = Path(sys.argv[2]); OUT.mkdir(parents=True, exist_ok=True)
SEED = 42
CPUS = int(os.environ.get("SMASH_CPUS") or os.cpu_count() or 1)  # sandbox quota, not nproc
rng = np.random.default_rng(SEED)

# Paper's reported values (published version, Results §3 / Fig. 1), for the "paper vs your run" panel.
PAPER = {
    ("cdc_diabetes", "sex"): {"se_diff": -0.033, "ci": [-0.048, -0.019]},
    ("cdc_diabetes", "age"): {"se_diff": -0.207, "ci": [-0.241, -0.170]},
    ("diabetes130", "sex"): {"se_diff": -0.049, "ci": [-0.084, -0.011]},
    ("diabetes130", "age"): {"se_diff": 0.104, "ci": [-0.070, 0.232]},
    ("diabetes130", "race"): {"se_diff": -0.040, "ci": [-0.090, 0.006]},
}

# Age bands as (low, high) inclusive. CDC uses BRFSS age codes 1..13 (1=18-24, 5=40-44,
# 10=65-69, 13=80+); Diabetes-130 uses decade starts 0..90.
AGE_BANDS = {
    "cdc_diabetes": {"18-44 vs 65+": ((1, 5), (10, 13)), "18-24 vs 80+": ((1, 1), (13, 13)),
                     "18-34 vs 70+": ((1, 3), (11, 13))},
    # paper: 10-29 vs 60+ (the 0-9 band is excluded); the others are alternatives for the multiverse
    "diabetes130": {"10-29 vs 60+": ((10, 20), (60, 90)), "<50 vs 70+": ((10, 40), (70, 90)),
                    "10-29 vs 80+": ((10, 20), (80, 90))},
}
RACE_PAIRS = {"diabetes130": ("AfricanAmerican", "Caucasian")}
# Diabetes-130 predictors as listed in the paper's predictor table (attribute-defining columns removed per comparison).
D130_NUM = ["number_diagnoses", "time_in_hospital", "num_lab_procedures", "num_procedures", "num_medications",
            "number_outpatient", "number_emergency", "number_inpatient", "admission_type_id",
            "discharge_disposition_id", "admission_source_id"]
D130_CAT = ["metformin", "repaglinide", "nateglinide", "chlorpropamide", "glimepiride", "acetohexamide", "glipizide",
            "glyburide", "tolbutamide", "pioglitazone", "rosiglitazone", "acarbose", "miglitol", "troglitazone",
            "tolazamide", "examide", "citoglipton", "insulin", "glyburide-metformin", "glipizide-metformin",
            "glimepiride-pioglitazone", "metformin-rosiglitazone", "metformin-pioglitazone", "max_glu_serum",
            "A1Cresult", "change", "diabetesMed"]


def log(msg):
    print(f"[{time.time() - T0:6.1f}s] {msg}", flush=True)


# ---------------------------------------------------------------- data
def fetch(url):
    with urllib.request.urlopen(url, timeout=120) as r:
        return r.read()


RAW = {}


def raw(dataset):
    if dataset not in RAW:
        if dataset == "cdc_diabetes":
            RAW[dataset] = pd.read_csv(io.BytesIO(fetch("https://archive.ics.uci.edu/static/public/891/data.csv")))
        else:
            z = zipfile.ZipFile(io.BytesIO(fetch(
                "https://archive.ics.uci.edu/static/public/296/diabetes+130-us+hospitals+for+years+1999-2008.zip")))
            name = [n for n in z.namelist() if n.endswith("diabetic_data.csv")][0]
            df = pd.read_csv(z.open(name), na_values="?", low_memory=False)
            RAW[dataset] = df[df["gender"].isin(["Male", "Female"])].reset_index(drop=True)
    return RAW[dataset]


def prepare(dataset, attr, bands=None, dedup=False, outcome="<30", ga=None, gb=None):
    """Return X, y, group labels and patient ids restricted to the two compared groups (paper §2).
    Predictors follow the paper's predictor table; the subgroup-defining variable is excluded."""
    df = raw(dataset)
    if dataset == "cdc_diabetes":
        y = df["Diabetes_binary"].astype(int).values
        # paper: the sex comparison keeps Age as a predictor; the age comparison drops Age and Sex
        X = df.drop(columns=["ID", "Diabetes_binary", "Sex"] + (["Age"] if attr == "age" else []), errors="ignore")
        age = df["Age"].values
        sex = np.where(df["Sex"] == 1, "Male", "Female")
        race = None
        pid = np.arange(len(df))  # one row per respondent
        outcome_label = "diabetes / prediabetes (BRFSS 2015 extract)"
    else:
        if attr == "age":  # paper: the 0-9 band is excluded before partitioning
            df = df[df["age"] != "[0-10)"].reset_index(drop=True)
        if dedup:
            df = df.drop_duplicates("patient_nbr").reset_index(drop=True)
        y = ((df["readmitted"] == "<30") if outcome == "<30" else (df["readmitted"] != "NO")).astype(int).values
        age = df["age"].str.extract(r"\[(\d+)")[0].astype(int).values
        race = df["race"].fillna("Unknown").values
        parts = [df[D130_NUM].fillna(0)]
        if attr != "age":
            parts.insert(0, pd.DataFrame({"age_numeric": age}))
        if attr != "race":
            parts.append(pd.get_dummies(pd.Categorical(race, categories=["AfricanAmerican", "Asian", "Caucasian",
                         "Hispanic", "Other", "Unknown"]), prefix="race", drop_first=True).astype(int))
        parts.append(pd.get_dummies(df[D130_CAT].astype(str), drop_first=True).astype(int))
        X = pd.concat([x.reset_index(drop=True) for x in parts], axis=1)
        sex = df["gender"].values
        pid = df["patient_nbr"].values
        outcome_label = ("30-day readmission" if outcome == "<30" else "any readmission") + \
            (" (one encounter per patient)" if dedup else " (all encounters, patient-level splits)")
    if attr == "sex":
        g = sex; ga, gb = ga or "Male", gb or "Female"
    elif attr == "age":
        (a0, a1), (b0, b1) = AGE_BANDS[dataset][bands]
        g = np.where((age >= a0) & (age <= a1), "youngest", np.where((age >= b0) & (age <= b1), "oldest", "-"))
        ga, gb = "youngest", "oldest"
    elif attr == "race":
        if race is None:
            raise SystemExit("race is only available for diabetes130 in this runbook")
        g = race; ga, gb = ga or RACE_PAIRS[dataset][0], gb or RACE_PAIRS[dataset][1]
    keep = np.isin(g, [ga, gb])
    return X[keep].reset_index(drop=True), y[keep], g[keep], pid[keep], ga, gb, outcome_label


def cap(X, y, g, pid, ga, n):
    """Subsample to about n rows for the time budget, keeping whole patients together."""
    if len(y) <= n:
        return X, y, g, pid
    pats = np.unique(pid)
    keep_p = rng.choice(pats, int(len(pats) * n / len(y)), replace=False)
    sel = np.isin(pid, keep_p)
    return X[sel].reset_index(drop=True), y[sel], g[sel], pid[sel]


def split(X, y, g, pid, grouped):
    """70/30 split; by patient when a patient can have several rows (paper: Diabetes-130)."""
    if grouped:
        tr, te = next(GroupShuffleSplit(1, test_size=0.3, random_state=SEED).split(X, y, pid))
    else:
        tr, te = train_test_split(np.arange(len(y)), test_size=0.3, stratify=y, random_state=SEED)
    return X.iloc[tr], X.iloc[te], y[tr], y[te], g[tr], g[te], pid[tr], pid[te]


# ---------------------------------------------------------------- metrics
def confusion(y, s, tau):
    p = s >= tau
    return (int(np.sum(p & (y == 1))), int(np.sum(p & (y == 0))),
            int(np.sum(~p & (y == 0))), int(np.sum(~p & (y == 1))))  # tp, fp, tn, fn


def rates(tp, fp, tn, fn):
    return dict(se=tp / max(tp + fn, 1), sp=tn / max(tn + fp, 1), ppv=tp / max(tp + fp, 1),
                npv=tn / max(tn + fn, 1), prev=(tp + fn) / max(tp + fp + tn + fn, 1),
                n=tp + fp + tn + fn, events=tp + fn, tp=tp, fp=fp, tn=tn, fn=fn)


def ppv_at(se, sp, pi):
    """Paper's prevalence standardization: hold Se and Sp fixed, set prevalence to pi."""
    return se * pi / max(se * pi + (1 - sp) * (1 - pi), 1e-12)


def npv_at(se, sp, pi):
    return sp * (1 - pi) / max(sp * (1 - pi) + (1 - se) * pi, 1e-12)


def boot_se_diff_patients(y, s, g, pid, ga, gb, tau, B):
    """Diabetes-130 (paper §2): each replicate draws patients with replacement from the held-out comparison;
    a patient drawn k times contributes all of their encounters k times."""
    pats, inv = np.unique(pid, return_inverse=True)
    pos_pred = (s >= tau) & (y == 1)
    sums = {k: np.bincount(inv, weights=v.astype(float), minlength=len(pats)) for k, v in {
        "tp_a": pos_pred & (g == ga), "p_a": (y == 1) & (g == ga), "tp_b": pos_pred & (g == gb), "p_b": (y == 1) & (g == gb)}.items()}
    d = np.empty(B)
    for b in range(B):
        w = np.bincount(rng.integers(0, len(pats), len(pats)), minlength=len(pats))
        d[b] = (w @ sums["tp_a"]) / max(w @ sums["p_a"], 1) - (w @ sums["tp_b"]) / max(w @ sums["p_b"], 1)
    return [float(np.percentile(d, 2.5)), float(np.percentile(d, 97.5))]


def boot_se_diff(ya, sa, yb, sb, tau, B):
    """Percentile 95% CI with resamples drawn separately within each subgroup (paper §2)."""
    pa, pb = sa >= tau, sb >= tau
    def se(y, p, n):
        idx = rng.integers(0, n, size=(B, n))
        yy, pp = y[idx], p[idx]
        return (pp & (yy == 1)).sum(1) / np.maximum((yy == 1).sum(1), 1)
    d = se(ya, pa, len(ya)) - se(yb, pb, len(yb))
    return [float(np.percentile(d, 2.5)), float(np.percentile(d, 97.5))]


# ---------------------------------------------------------------- models
def candidates():
    c = {
        "logistic": make_pipeline(StandardScaler(), LogisticRegression(max_iter=2000)),
        "l1_logistic": make_pipeline(StandardScaler(), LogisticRegression(penalty="l1", solver="liblinear", C=0.5)),
        "shallow_tree": DecisionTreeClassifier(max_depth=4, random_state=SEED),
        "random_forest": RandomForestClassifier(n_estimators=150, max_depth=10, n_jobs=CPUS, random_state=SEED),
        "gradient_boosting": HistGradientBoostingClassifier(max_iter=200, random_state=SEED),
    }
    c["soft_voting"] = VotingClassifier(
        [("lr", c["logistic"]), ("rf", c["random_forest"]), ("gb", c["gradient_boosting"])], voting="soft", n_jobs=CPUS)
    return c


def select_and_fit(X, y, pid):
    """Family selection by 5-fold CV AUC, then 5-fold isotonic fold-ensemble calibration; folds grouped by patient."""
    cands = candidates()
    if P["model"] != "auto":
        cands = {P["model"]: cands[P["model"]]}
    n_cv = min(len(y), int(P["cv_rows"]))  # capped CV subsample keeps the run inside the time budget
    idx = rng.choice(len(y), n_cv, replace=False)
    cv = StratifiedGroupKFold(5, shuffle=True, random_state=SEED)
    scores = {}
    for name, m in cands.items():
        scores[name] = float(cross_val_score(m, X.iloc[idx], y[idx], groups=pid[idx], cv=cv, scoring="roc_auc",
                                             n_jobs=CPUS).mean())
        log(f"  CV AUC {name}: {scores[name]:.4f}")
    best = max(scores, key=scores.get)
    folds = list(StratifiedGroupKFold(5, shuffle=True, random_state=SEED).split(X, y, pid))
    cal = CalibratedClassifierCV(cands[best], method="isotonic", cv=folds, ensemble=True)  # fold-ensemble isotonic
    cal.fit(X, y)
    return best, scores, cal


def tau_rule(rule, ytr, s_tr=None):
    if rule == "train_prevalence":
        return float(ytr.mean())
    if rule == "top20":
        return float(np.quantile(s_tr, 0.8))
    return float(rule)


# ---------------------------------------------------------------- multiverse
def multiverse(dataset, attr, base_ga, base_gb):
    """Re-run the core estimate over defensible analytic choices with a fixed fast model
    (gradient boosting + isotonic). Point estimates only — this maps sensitivity to choices."""
    axes = {"tau": ["train_prevalence", "0.5", "top20"]}
    if attr == "age":
        axes["bands"] = list(AGE_BANDS[dataset])
    if dataset == "diabetes130":
        axes["dedup"] = [False, True]
        axes["outcome"] = ["<30", "any"]
    keys = list(axes)
    specs = []
    for combo in itertools.product(*[axes[k] for k in keys]):
        o = dict(zip(keys, combo))
        X, y, g, pid, ga, gb, _ = prepare(dataset, attr, bands=o.get("bands"), dedup=o.get("dedup", False),
                                          outcome=o.get("outcome", "<30"), ga=base_ga, gb=base_gb)
        X, y, g, pid = cap(X, y, g, pid, ga, int(P["multiverse_rows"]))
        Xtr, Xte, ytr, yte, gtr, gte, _, _ = split(X, y, g, pid, grouped=dataset == "diabetes130" and not o.get("dedup", False))
        m = CalibratedClassifierCV(HistGradientBoostingClassifier(max_iter=150, random_state=SEED),
                                   method="isotonic", cv=3, ensemble=True).fit(Xtr, ytr)
        s = m.predict_proba(Xte)[:, 1]
        tau = tau_rule(o["tau"], ytr, m.predict_proba(Xtr)[:, 1])
        ra = rates(*confusion(yte[gte == ga], s[gte == ga], tau))
        rb = rates(*confusion(yte[gte == gb], s[gte == gb], tau))
        short = {"train_prevalence": "τ=prev", "0.5": "τ=0.5", "top20": "τ=top20%", True: "per-patient",
                 False: "all-encounters", "<30": "30-day", "any": "any-readmit"}
        label = " · ".join(short.get(v, v) for v in o.values())
        specs.append({**{k: v for k, v in o.items()}, "label": label, "se_diff": ra["se"] - rb["se"],
                      "ppv_diff": ra["ppv"] - rb["ppv"], "n": int(len(y))})
    log(f"multiverse: {len(specs)} specifications")
    return specs


# ---------------------------------------------------------------- byo mode
def parse_byo(s):
    """'GroupA:TP,FP,TN,FN; GroupB:TP,FP,TN,FN'"""
    groups = []
    for part in [p for p in s.split(";") if p.strip()]:
        name, nums = part.split(":")
        groups.append((name.strip(), *[int(x) for x in nums.split(",")]))
    if len(groups) != 2:
        raise SystemExit("byo_confusion needs exactly two groups: 'A:TP,FP,TN,FN; B:TP,FP,TN,FN'")
    return groups


def expand(tp, fp, tn, fn):
    y = np.r_[np.ones(tp + fn), np.zeros(fp + tn)].astype(int)
    s = np.r_[np.ones(tp), np.zeros(fn), np.ones(fp), np.zeros(tn)]
    return y, s


# ---------------------------------------------------------------- main
def main():
    attr, byo = P["attribute"], P.get("byo_confusion", "").strip()
    res = {"params": P, "mode": "byo" if byo else "dataset"}
    sweep, specs, grouped = None, None, False

    if byo:
        (ga, *ca), (gb, *cb) = parse_byo(byo)
        ma, mb = rates(*ca), rates(*cb)
        (ya, sa), (yb, sb) = expand(*ca), expand(*cb)
        tau = 0.5
        res.update(outcome="(your model's outcome)", model="(your model)", tau=None)
    else:
        ds = P["dataset"]
        bands = P["age_bands"] or list(AGE_BANDS[ds])[0]
        log(f"loading {ds}")
        X, y, g, pid, ga, gb, outcome = prepare(ds, attr, bands=bands, dedup=False, outcome="<30",
                                                ga=P["group_a"] or None, gb=P["group_b"] or None)
        X, y, g, pid = cap(X, y, g, pid, ga, int(P["max_rows"]))
        grouped = ds == "diabetes130"
        log(f"{len(y)} rows ({len(np.unique(pid))} patients), {ga} vs {gb}, outcome prevalence {y.mean():.3f}")
        Xtr, Xte, ytr, yte, gtr, gte, ptr, pte = split(X, y, g, pid, grouped)
        best, scores, model = select_and_fit(Xtr, ytr, ptr)
        s = model.predict_proba(Xte)[:, 1]
        rule = str(P["threshold"]) or "train_prevalence"
        tau = tau_rule(rule, ytr, model.predict_proba(Xtr)[:, 1])
        log(f"selected {best}; tau = {tau:.4f}; test AUC {roc_auc_score(yte, s):.4f}")
        ya, sa, yb, sb = yte[gte == ga], s[gte == ga], yte[gte == gb], s[gte == gb]
        ma, mb = rates(*confusion(ya, sa, tau)), rates(*confusion(yb, sb, tau))
        if attr == "age":
            ga_lab, gb_lab = bands.split(" vs ")
            res["group_labels"] = {"youngest": ga_lab, "oldest": gb_lab}
        res.update(outcome=outcome, model=best, cv_auc=scores, test_auc=float(roc_auc_score(yte, s)),
                   tau=tau, tau_rule=rule, age_bands=bands if attr == "age" else None)
        sweep = []
        for t in np.round(np.linspace(0.02, 0.8, 40), 4):
            ra, rb = rates(*confusion(ya, sa, t)), rates(*confusion(yb, sb, t))
            if min(ra["tp"] + ra["fp"], rb["tp"] + rb["fp"]) < 30:  # too few flagged patients: PPV is noise
                break
            sweep.append({"tau": float(t), **{f"{k}_gap": ra[k] - rb[k] for k in ("se", "sp", "ppv", "npv")}})
        if P.get("multiverse", True) in (True, "true", "yes", "1"):
            specs = multiverse(ds, attr, P["group_a"] or None, P["group_b"] or None)

    if not byo and grouped:
        ci = boot_se_diff_patients(yte, s, gte, pte, ga, gb, tau, int(P["n_boot"]))
    else:
        ci = boot_se_diff(ya, sa, yb, sb, tau, int(P["n_boot"]))
    pooled = (ma["events"] + mb["events"]) / (ma["n"] + mb["n"])
    tp_ = str(P["target_prevalence"])
    pi = pooled if tp_ in ("", "pooled") else float(tp_)
    std = {"pi": pi, "ppv_a": ppv_at(ma["se"], ma["sp"], pi), "ppv_b": ppv_at(mb["se"], mb["sp"], pi),
           "npv_a": npv_at(ma["se"], ma["sp"], pi), "npv_b": npv_at(mb["se"], mb["sp"], pi)}
    raw_gap, std_gap = ma["ppv"] - mb["ppv"], std["ppv_a"] - std["ppv_b"]
    prev_curve = [{"pi": float(q), "ppv_gap": ppv_at(ma["se"], ma["sp"], q) - ppv_at(mb["se"], mb["sp"], q)}
                  for q in np.linspace(0.01, 0.6, 60)]
    res.update(group_a=ga, group_b=gb, metrics_a=ma, metrics_b=mb,
               se_diff=ma["se"] - mb["se"], se_diff_ci=ci, ci_excludes_zero=bool(ci[0] > 0 or ci[1] < 0),
               ppv_gap_raw=raw_gap, ppv_gap_std=std_gap, standardized=std,
               ppv_sign_flip=bool(raw_gap * std_gap < 0),
               ppv_gap_shrink_pct=float(100 * (1 - abs(std_gap) / abs(raw_gap))) if raw_gap else None,
               prevalence_curve=prev_curve, threshold_sweep=sweep, multiverse=specs,
               paper=None if byo else PAPER.get((P["dataset"], attr)))
    if sweep:
        g_ = [r["se_gap"] for r in sweep]
        res["se_gap_range_over_thresholds"] = [float(min(g_)), float(max(g_))]
    if specs:
        d = [x["se_diff"] for x in specs]
        res["multiverse_summary"] = {"n_specs": len(d), "min": float(min(d)), "max": float(max(d)),
                                     "n_negative": int(sum(v < 0 for v in d)), "n_positive": int(sum(v > 0 for v in d))}

    figures(res, ma, mb, ci, tau, sweep, specs, prev_curve, raw_gap, std_gap, pi)
    card_data(res)
    res["runtime_sec"] = round(time.time() - T0, 1)
    (OUT / "results.json").write_text(json.dumps(res, indent=2, default=float))
    log(f"done: Se diff {res['se_diff']:+.4f} CI [{ci[0]:+.4f}, {ci[1]:+.4f}]; "
        f"PPV gap raw {raw_gap:+.4f} -> std {std_gap:+.4f}")


def figures(res, ma, mb, ci, tau, sweep, specs, prev_curve, raw_gap, std_gap, pi):
    plt.rcParams.update({"font.size": 10, "axes.spines.top": False, "axes.spines.right": False,
                         "font.family": "DejaVu Sans"})
    INK, A, Bc, MUTED = "#1f2a44", "#d9480f", "#1971c2", "#868e96"
    lab = res.get("group_labels", {})
    ga, gb = lab.get(res["group_a"], res["group_a"]), lab.get(res["group_b"], res["group_b"])

    fig, ax = plt.subplots(figsize=(6.4, 2.4))
    rows = [("Your run", res["se_diff"], ci, A)]
    if res.get("paper") and res["paper"].get("se_diff") is not None:
        rows.append(("Paper", res["paper"]["se_diff"], res["paper"]["ci"], MUTED))
    for i, (name, v, c, col) in enumerate(rows):
        ax.plot(c, [i, i], color=col, lw=2.5); ax.plot(v, i, "o", color=col, ms=9)
        ax.annotate(f"{v:+.3f} [{c[0]:+.3f}, {c[1]:+.3f}]", (c[1], i), xytext=(6, 0),
                    textcoords="offset points", va="center", color=col, fontsize=9)
    ax.axvline(0, color=INK, lw=1, ls="--")
    ax.set_yticks(range(len(rows))); ax.set_yticklabels([r[0] for r in rows]); ax.set_ylim(-0.7, len(rows) - 0.3)
    lo = min(min(r[2][0] for r in rows), 0); hi = max(max(r[2][1] for r in rows), 0)
    ax.set_xlim(lo - 0.02, hi + (hi - lo) * 0.9 + 0.03)
    ax.set_xlabel(f"Sensitivity difference ({ga} − {gb}), 95% bootstrap CI")
    fig.tight_layout(); fig.savefig(OUT / "fig_forest.png", dpi=160); plt.close(fig)

    fig, ax = plt.subplots(figsize=(6.4, 3.0))
    ax.plot([r["pi"] for r in prev_curve], [r["ppv_gap"] for r in prev_curve], color=INK, lw=2)
    ax.axhline(0, color=MUTED, lw=1, ls="--")
    ax.plot((ma["prev"] + mb["prev"]) / 2, raw_gap, "o", color=A, ms=8,
            label=f"raw: {raw_gap:+.3f} (each group at its own prevalence)")
    ax.plot(pi, std_gap, "s", color=Bc, ms=8, label=f"standardized at π = {pi:.3f}: {std_gap:+.3f}")
    ax.set_xlabel("Common prevalence π  (sensitivity and specificity held fixed)")
    ax.set_ylabel(f"PPV gap ({ga} − {gb})"); ax.legend(frameon=False, fontsize=8, loc="best")
    fig.tight_layout(); fig.savefig(OUT / "fig_prevalence.png", dpi=160); plt.close(fig)

    if sweep:
        fig, ax = plt.subplots(figsize=(6.4, 3.0))
        for k, col, name in [("se", A, "Sensitivity"), ("sp", Bc, "Specificity"),
                             ("ppv", "#2b8a3e", "PPV"), ("npv", "#7048e8", "NPV")]:
            ax.plot([r["tau"] for r in sweep], [r[f"{k}_gap"] for r in sweep], color=col, lw=2, label=name)
        ax.axhline(0, color=MUTED, lw=1, ls="--"); ax.axvline(tau, color=INK, lw=1, ls=":")
        ax.annotate(f"τ = {tau:.3f}", (tau, 1), xycoords=("data", "axes fraction"), xytext=(4, -4),
                    textcoords="offset points", va="top", fontsize=8)
        ax.set_xlabel("Operating threshold τ (same for both groups)"); ax.set_ylabel(f"Gap ({ga} − {gb})")
        ax.legend(frameon=False, fontsize=8, ncol=4, loc="upper center", bbox_to_anchor=(0.5, 1.16))
        fig.tight_layout(); fig.savefig(OUT / "fig_threshold.png", dpi=160); plt.close(fig)

    if specs:
        sp = sorted(specs, key=lambda x: x["se_diff"])
        fig, ax = plt.subplots(figsize=(6.4, 0.9 + 0.22 * len(sp)))
        cols = [A if x["se_diff"] < 0 else Bc for x in sp]
        ax.barh(range(len(sp)), [x["se_diff"] for x in sp], color=cols, height=0.7)
        ax.set_yticks(range(len(sp))); ax.set_yticklabels([x["label"] for x in sp], fontsize=7)
        ax.axvline(0, color=INK, lw=1)
        if res.get("paper") and res["paper"].get("se_diff") is not None:
            ax.axvline(res["paper"]["se_diff"], color=MUTED, ls="--", lw=1.2)
            ax.annotate("paper", (res["paper"]["se_diff"], 1), xycoords=("data", "axes fraction"),
                        xytext=(3, -2), textcoords="offset points", fontsize=8, color=MUTED, va="top")
        ax.set_xlabel(f"Sensitivity difference ({ga} − {gb}) under each analytic choice")
        fig.tight_layout(); fig.savefig(OUT / "fig_multiverse.png", dpi=160); plt.close(fig)


def card_data(res):
    lab = res.get("group_labels", {})
    ga, gb = lab.get(res["group_a"], res["group_a"]), lab.get(res["group_b"], res["group_b"])
    ci, ma, mb = res["se_diff_ci"], res["metrics_a"], res["metrics_b"]
    inputs = ({"mode": "your confusion matrices", "groups": f"{ga} vs {gb}"} if res["mode"] == "byo" else
              {"dataset": P["dataset"], "attribute": P["attribute"], "groups": f"{ga} vs {gb}",
               "outcome": res["outcome"], "model": res["model"],
               "threshold": f"{res['tau']:.3f} ({res['tau_rule']})", "rows": f"{ma['n'] + mb['n']:,} test"})
    inputs["standardized to π"] = f"{res['standardized']['pi']:.3f}"
    tiles = [
        {"label": f"Sensitivity gap ({ga} − {gb})", "value": f"{res['se_diff']:+.3f}",
         "sub": f"95% CI [{ci[0]:+.3f}, {ci[1]:+.3f}] — " + ("excludes 0" if res["ci_excludes_zero"] else "includes 0"),
         "tone": "accent"},
        {"label": "PPV gap: raw → standardized", "value": f"{res['ppv_gap_raw']:+.3f} → {res['ppv_gap_std']:+.3f}",
         "sub": "sign flips" if res["ppv_sign_flip"] else
                f"{res['ppv_gap_shrink_pct']:.0f}% smaller" if (res["ppv_gap_shrink_pct"] or 0) > 0 else "gap grows",
         "tone": "warn" if res["ppv_sign_flip"] else "neutral"},
        {"label": "Prevalence", "value": f"{ma['prev']:.1%} vs {mb['prev']:.1%}",
         "sub": f"{ma['events']:,} / {mb['events']:,} events in test", "tone": "neutral"},
    ]
    if res.get("multiverse_summary"):
        m = res["multiverse_summary"]
        tiles.append({"label": "Gap across analytic choices", "value": f"{m['min']:+.2f} … {m['max']:+.2f}",
                      "sub": f"{m['n_negative']} negative / {m['n_positive']} positive of {m['n_specs']} specs",
                      "tone": "warn" if m["n_negative"] and m["n_positive"] else "good"})
    figs = [{"path": "fig_forest.png", "title": "Is the sensitivity gap distinguishable from zero?",
             "caption": "Point = difference at the shared threshold; whiskers = 95% percentile CI from 1,000 "
                        "bootstrap resamples drawn separately within each subgroup (paper §2)."},
            {"path": "fig_prevalence.png", "title": "Prevalence standardization",
             "caption": "Holding each group's sensitivity and specificity fixed, PPV is recomputed at a common prevalence. "
                        "The curve shows how much of the PPV gap is just base rates."}]
    if res.get("threshold_sweep"):
        figs.append({"path": "fig_threshold.png", "title": "Threshold dependence",
                     "caption": "Each metric's gap as the shared operating threshold moves. Shrinking one gap can grow another."})
    if res.get("multiverse"):
        figs.append({"path": "fig_multiverse.png", "title": "Same data, different defensible choices",
                     "caption": "Point estimates re-run under every combination of threshold rule and data-preparation "
                                "choices (fast gradient-boosting model). Orange = negative gap, blue = positive."})
    compare = []
    pp = res.get("paper")
    if pp and pp.get("se_diff") is not None:
        compare.append({"metric": "Sensitivity difference", "paper": f"{pp['se_diff']:+.3f} [{pp['ci'][0]:+.3f}, {pp['ci'][1]:+.3f}]",
                        "yours": f"{res['se_diff']:+.3f} [{ci[0]:+.3f}, {ci[1]:+.3f}]",
                        "note": "Paper's predictor set, age bands and patient-level resampling; model hyperparameters are ours."})
    compare += [
        {"metric": "Sensitivity CIs excluding zero (13 comparisons)", "paper": "7 of 13 (3 sex, 4 age, 0 race)",
         "yours": "excludes 0" if res["ci_excludes_zero"] else "includes 0", "note": "your single comparison"},
        {"metric": "PPV gap after standardization", "paper": "BRFSS M−F +0.101 → +0.016; CCHS M−F +0.053 → −0.005 (point estimate only; interval spans zero)",
         "yours": f"{res['ppv_gap_raw']:+.3f} → {res['ppv_gap_std']:+.3f}", "note": ""},
    ]
    Path(OUT / "card_data.json").write_text(json.dumps({
        "paper": {"num": 7, "title": "Prevalence, Thresholds, and Subgroup Performance Gaps in Clinical Prediction Models Across Five Public Datasets",
                  "authors": "Zavash Ghorbanpourbaboli, Arina Afshar, Elham Jangravi, Mohammed Ayoub Alaoui Mhamdi, Russell Butler", "url": "https://drive.google.com/file/d/1MnK-mFUFDe2Josf706Rgn4RxZMB6df3M/view?usp=sharing",
                  "affiliation": "Bishop's University"},
        "inputs": inputs, "tiles": tiles, "figures": figs, "compare": compare,
        "runbook": {"name": "smash-07-gap-audit", "url": P.get("runbook_url", "")}}, indent=2))


if __name__ == "__main__":
    main()
/app/work/render_card.py
"""Render a SMASH 2026 paper-playground result card (one self-contained HTML file).

usage: python render_card.py card_data.json narrative.json out.html

card_data.json  (written by the experiment script — numbers only)
  paper:   {num, title, authors, affiliation, url?}
  inputs:  {label: value}                         the participant's run settings
  tiles:   [{label, value, sub, tone}]            tone: accent|good|warn|neutral
  figures: [{path, title, caption}]               PNGs, embedded as base64
  compare: [{metric, paper, yours, note}]         paper-vs-your-run table (optional)
  runbook: {name, url}                            fork link (optional)
narrative.json  (written by the agent — words only)
  headline:  one sentence, the finding of THIS run
  idea:      [1-3 bullets] the paper's contribution in plain language
  abstract:  (optional) a verbatim abstract excerpt, shown instead of idea
  findings:  [2-4 short paragraphs] what this run shows, tied to the numbers
  try_next:  [{label, why, params}]               2-3 follow-up runs with exact parameter values
  caveats:   [bullets]
"""
import base64, html, json, sys
from pathlib import Path

data = json.loads(Path(sys.argv[1]).read_text())
narr = json.loads(Path(sys.argv[2]).read_text())
base = Path(sys.argv[1]).parent
e = lambda s: html.escape(str(s))


def md_inline(s):
    """Escape, then allow **bold**, *italic* and `code` only."""
    import re
    s = e(s)
    s = re.sub(r"\*\*(.+?)\*\*", r"<strong>\1</strong>", s)
    s = re.sub(r"(?<![\w*])\*(?!\s)(.+?)(?<!\s)\*(?![\w*])", r"<em>\1</em>", s)
    return re.sub(r"`(.+?)`", r"<code>\1</code>", s)


p = data["paper"]
tiles = "".join(
    f'<div class="tile {e(t.get("tone", "neutral"))}"><div class="tl">{e(t["label"])}</div>'
    f'<div class="tv">{e(t["value"])}</div><div class="ts">{md_inline(t.get("sub", ""))}</div></div>'
    for t in data.get("tiles", []))
# Columns that fill every row: 4 tiles as 2x2, never 3 + 1 orphan.
n_tiles = len(data.get("tiles", []))
tile_cols = 2 if n_tiles == 4 else min(max(n_tiles, 1), 3)
inputs = "".join(f'<span class="chip"><b>{e(k)}</b> {e(v)}</span>' for k, v in data.get("inputs", {}).items())
figs = ""
for f in data.get("figures", []):
    fp = Path(f["path"]); fp = fp if fp.is_absolute() else base / fp
    if fp.exists():
        b64 = base64.b64encode(fp.read_bytes()).decode()
        figs += (f'<figure><figcaption class="ft">{e(f.get("title", ""))}</figcaption>'
                 f'<img alt="{e(f.get("title", ""))}" src="data:image/png;base64,{b64}">'
                 f'<figcaption>{md_inline(f.get("caption", ""))}</figcaption></figure>')
compare = ""
if data.get("compare"):
    rows = "".join(f'<tr><td>{md_inline(r["metric"])}</td><td>{md_inline(r["paper"])}</td>'
                   f'<td class="y">{md_inline(r["yours"])}</td><td class="n">{md_inline(r.get("note", ""))}</td></tr>'
                   for r in data["compare"])
    compare = (f'<section><h2>Paper vs. your run</h2><div class="tw"><table><thead><tr><th>Metric</th>'
               f'<th>Paper</th><th>Your run</th><th></th></tr></thead><tbody>{rows}</tbody></table></div></section>')
idea = "".join(f"<li>{md_inline(b)}</li>" for b in narr.get("idea", []))
abstract = narr.get("abstract", "")
findings = "".join(f"<p>{md_inline(x)}</p>" for x in narr.get("findings", []))
tries = "".join(
    f'<li><strong>{md_inline(t["label"])}</strong> — {md_inline(t.get("why", ""))}'
    f'<pre>{e(json.dumps(t.get("params", {}), ensure_ascii=False))}</pre></li>' for t in narr.get("try_next", []))
cav = "".join(f"<li>{md_inline(c)}</li>" for c in narr.get("caveats", []))
rb = data.get("runbook", {})
fork = (f'<a class="fork" href="{e(rb["url"])}">Fork this runbook on Jetty →</a>' if rb.get("url") else "")

page = f"""<!doctype html><html lang="en"><head><meta charset="utf-8">
<meta name="viewport" content="width=device-width,initial-scale=1">
<title>SMASH 2026 · #{e(p['num'])} · Result card</title>
<style>
:root{{--bg:#f6f4ef;--card:#fff;--ink:#1f2a44;--muted:#5c677d;--line:#e3dfd5;--accent:#d9480f;--good:#2b8a3e;--warn:#e67700;--chip:#efece4}}
@media (prefers-color-scheme:dark){{:root{{--bg:#11151f;--card:#1a2030;--ink:#e8ebf2;--muted:#9aa4b8;--line:#2c3447;--accent:#ff8a4c;--good:#69db7c;--warn:#ffc078;--chip:#232b3d}}
figure img{{background:#fff;border-radius:6px}}}}
*{{box-sizing:border-box}}body{{margin:0;background:var(--bg);color:var(--ink);font:15px/1.55 ui-sans-serif,system-ui,-apple-system,"Segoe UI",Roboto,sans-serif}}
main{{max-width:860px;margin:0 auto;padding:28px 16px 48px}}
.kicker{{font:600 12px/1 ui-monospace,SFMono-Regular,Menlo,monospace;letter-spacing:.08em;text-transform:uppercase;color:var(--accent)}}
h1{{font-size:clamp(22px,4vw,30px);line-height:1.2;margin:10px 0 6px}}.authors{{color:var(--muted);margin:0 0 18px}}.authors a{{color:var(--accent);text-underline-offset:3px}}
.headline{{background:var(--card);border:1px solid var(--line);border-left:5px solid var(--accent);border-radius:10px;padding:16px 18px;font-size:18px;font-weight:600;margin:0 0 18px}}
.chips{{display:flex;flex-wrap:wrap;gap:6px;margin:0 0 18px}}.chip{{background:var(--chip);border-radius:999px;padding:4px 10px;font-size:12.5px}}.chip b{{font-weight:600;color:var(--muted);margin-right:4px}}
.tiles{{display:grid;grid-template-columns:repeat(var(--cols),minmax(0,1fr));gap:10px;margin:0 0 22px}}
@media (max-width:560px){{.tiles{{grid-template-columns:1fr}}}}
.tile{{background:var(--card);border:1px solid var(--line);border-radius:10px;padding:12px 14px}}.tl{{font-size:12px;color:var(--muted);text-transform:uppercase;letter-spacing:.04em}}
.tv{{font-size:26px;font-weight:700;margin:2px 0;font-variant-numeric:tabular-nums}}.ts{{font-size:12.5px;color:var(--muted)}}
.tile.accent .tv{{color:var(--accent)}}.tile.good .tv{{color:var(--good)}}.tile.warn .tv{{color:var(--warn)}}
section{{background:var(--card);border:1px solid var(--line);border-radius:12px;padding:18px 20px;margin:0 0 16px}}
h2{{font-size:16px;margin:0 0 10px}}ul{{padding-left:20px;margin:0}}li{{margin:4px 0}}p{{margin:0 0 10px}}
figure{{margin:0 0 18px}}figure img{{width:100%;height:auto;display:block}}figcaption{{font-size:13px;color:var(--muted);margin-top:6px}}.ft{{font-weight:600;color:var(--ink);font-size:14px;margin:0 0 6px}}
.tw{{overflow-x:auto}}table{{border-collapse:collapse;width:100%;font-size:13.5px;font-variant-numeric:tabular-nums}}th,td{{text-align:left;padding:7px 8px;border-bottom:1px solid var(--line);vertical-align:top}}th{{color:var(--muted);font-weight:600}}td.y{{font-weight:600}}td.n{{color:var(--muted);font-size:12.5px}}
pre{{background:var(--chip);border-radius:6px;padding:6px 8px;font-size:12px;white-space:pre-wrap;word-break:break-word;margin:4px 0 8px}}code{{background:var(--chip);border-radius:4px;padding:1px 4px;font-size:.92em}}
.fork{{display:inline-block;background:var(--ink);color:var(--bg);text-decoration:none;font-weight:600;border-radius:8px;padding:10px 14px;margin-top:6px}}
footer{{color:var(--muted);font-size:12.5px;margin-top:22px}}
.abs{{margin:0;padding-left:14px;border-left:3px solid var(--accent);color:var(--ink)}}
</style></head><body><main>
<div class="kicker">SMASH 2026 · Paper #{e(p['num'])} · Result card</div>
<h1>{e(p['title'])}</h1><p class="authors">{e(p['authors'])}{(' · ' + e(p['affiliation'])) if p.get('affiliation') else ''}{(f' · <a href="{e(p["url"])}">Read the paper</a>') if p.get('url') else ''}</p>
<div class="headline">{md_inline(narr['headline'])}</div>
<div class="chips">{inputs}</div>
<div class="tiles" style="--cols:{tile_cols}">{tiles}</div>
{f'<section><h2>From the abstract</h2><blockquote class="abs">{e(abstract)}</blockquote></section>' if abstract else f'<section><h2>The idea</h2><ul>{idea}</ul></section>'}
{f'<section><h2>What this run shows</h2>{findings}</section>' if findings else ''}
<section><h2>Evidence</h2>{figs}</section>
{compare}
<section><h2>Try next</h2><ul>{tries}</ul>{fork}</section>
<section><h2>Read this before sharing</h2><ul>{cav}</ul></section>
<footer>Generated by a Jetty runbook built from the authors' SMASH 2026 paper. Numbers on this card come from code run in a sandbox; the words were written by an AI agent reading those numbers. This is an interactive companion, not the authors' own results unless labelled “Paper”.</footer>
</main></body></html>"""
Path(sys.argv[3]).write_text(page)
print(f"wrote {sys.argv[3]} ({len(page) // 1024} KB)")
/app/work/validate.py
"""Self-check a SMASH paper-playground run and write validation_report.json (evals v2 shape).

Runs the same checks as the runbook's `## Code Checks` (which Jetty re-runs independently after the agent
exits and substitutes for these entries), adds one `step` entry per runbook step and the agent's checklist
judgements, and prints PASS/FAIL lines.

usage: python validate.py <results_dir> <param,param,...> <budget_sec> [checklist.json]
"""
import html, json, re, sys
from pathlib import Path

R = Path(sys.argv[1])
allowed = set(sys.argv[2].split(","))
budget = float(sys.argv[3])
checklist_path = Path(sys.argv[4]) if len(sys.argv) > 4 else None


def load(name):
    try:
        return json.loads((R / name).read_text())
    except Exception:
        return None


res, cdata, narr = load("results.json"), load("card_data.json"), load("narrative.json")
card = (R / "result_card.html").read_text() if (R / "result_card.html").exists() else ""


def c_outputs_exist():
    missing = [f for f in ["result_card.html", "results.json", "card_data.json", "narrative.json", "summary.md"]
               if not (R / f).exists() or (R / f).stat().st_size == 0]
    return not missing, f"missing or empty: {missing}" if missing else "all 5 outputs present"


def c_results_valid():
    if res is None or cdata is None:
        return False, "results.json or card_data.json does not parse"
    rt = float(res.get("runtime_sec", 0))
    return rt <= budget, f"experiment {rt}s (budget {budget:.0f}s)"


def c_narrative_complete():
    if narr is None:
        return False, "narrative.json does not parse"
    p = []
    if not str(narr.get("headline", "")).strip(): p.append("no headline")
    if len(str(narr.get("headline", "")).split()) > 45: p.append("headline over 45 words")
    if not 1 <= len(narr.get("idea", [])) <= 3: p.append(f"idea has {len(narr.get('idea', []))} bullets, need 1-3")
    if not 1 <= len(narr.get("findings", [])) <= 2: p.append(f"{len(narr.get('findings', []))} findings, need 1-2")
    if any(len(f.split()) > 70 for f in narr.get("findings", [])): p.append("a findings paragraph is over 60 words")
    if not 2 <= len(narr.get("try_next", [])) <= 3: p.append(f"{len(narr.get('try_next', []))} try_next, need 2-3")
    if not 1 <= len(narr.get("caveats", [])) <= 2: p.append(f"{len(narr.get('caveats', []))} caveats, need 1-2")
    return not p, "; ".join(p) or "complete and within the length limits"


def c_try_next_valid():
    if narr is None:
        return False, "narrative.json does not parse"
    bad = sorted({k for t in narr.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
    empty = [t.get("label", "?") for t in narr.get("try_next", []) if not t.get("params")]
    ok = not bad and not empty
    return ok, "all try_next parameters are declared" if ok else f"unknown parameters: {bad}; without params: {empty}"


def c_headline_grounded():
    if narr is None or res is None:
        return False, "missing narrative or results"
    blob = json.dumps(res) + json.dumps(cdata or {})
    vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
    nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", narr.get("headline", ""))
    missing = []
    for n in nums:
        s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
        tol = 0.5 * 10 ** (-dec) + 1e-9
        if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
            missing.append(n)
    return not missing, f"not found in results: {missing}" if missing else f"{len(nums)} headline number(s) grounded"


def c_card_integrity():
    if not card or narr is None:
        return False, "no card or narrative"
    text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
    plain = html.unescape(re.sub(r"<[^>]+>", "", text))
    p = []
    if card.count("data:image/png;base64") < 1: p.append("no embedded figures")
    if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): p.append("NaN/Infinity in card text")
    if len(card) > 5_000_000: p.append(f"card is {len(card) // 1024} KB")
    if re.sub(r"[*`]", "", narr.get("headline", ""))[:40] not in plain: p.append("headline not on card")
    return not p, "; ".join(p) or f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures"


CODE_CHECKS = [  # ids and names match the runbook's ## Code Checks headings
    ("outputs-exist", "Result card, numbers, narrative and summary were written", c_outputs_exist),
    ("results-valid", "Experiment numbers are valid JSON and the experiment stayed within its time budget", c_results_valid),
    ("narrative-complete", "The narrative is complete and within the length limits", c_narrative_complete),
    ("try-next-valid", "Every try-next suggestion uses only this runbook's parameters", c_try_next_valid),
    ("headline-grounded", "Every number in the headline appears in the run's results", c_headline_grounded),
    ("card-integrity", "The card embeds its figures, shows the headline, and contains no NaN", c_card_integrity),
]
STEPS = [  # (id, name, evidence that the step happened)
    ("setup", "Set up the sandbox and parameters", Path("/app/work/params.json").exists() or res is not None),
    ("get-code", "Extract the tested code", Path("/app/work/experiment.py").exists() or res is not None),
    ("experiment", "Run the experiment", res is not None),
    ("interpret", "Write the narrative", narr is not None),
    ("render", "Render the result card and summary", bool(card) and (R / "summary.md").exists()),
]

checks = [{"kind": "step", "id": i, "name": n, "status": "pass" if ok else "fail"} for i, n, ok in STEPS]
for cid, name, fn in CODE_CHECKS:
    try:
        ok, msg = fn()
    except Exception as e:  # a check that crashes is an error, never a silent pass
        ok, msg = None, f"{type(e).__name__}: {e}"
    status = "pass" if ok else ("error" if ok is None else "fail")
    checks.append({"kind": "code_check", "id": cid, "name": name, "status": status, "message": str(msg)[:1000]})
    print(f"{'PASS' if ok else 'FAIL'} {cid}: {msg}")

if checklist_path and checklist_path.exists():
    for item in json.loads(checklist_path.read_text()):
        st = item.get("status", "skipped")
        st = st if st in ("pass", "fail", "skipped", "error") else "skipped"
        checks.append({"kind": "checklist", "id": str(item["id"]), "name": str(item.get("name") or item["id"]),
                       "status": st, "message": str(item.get("message", ""))[:1000]})
        print(f"{'PASS' if st == 'pass' else 'FAIL'} checklist {item['id']}: {item.get('message', '')}")
else:
    print("NOTE no checklist.json given; checklist items will be recorded as not reported")

gating = [c for c in checks if c["kind"] != "step"]
verdict = "fail" if any(c["status"] in ("fail", "error") for c in gating) else ("pass" if gating else "unknown")
(R / "validation_report.json").write_text(json.dumps({"version": 2, "verdict": verdict, "checks": checks}, indent=2))
print(json.dumps({"verdict": verdict, "passed": sum(c["status"] == "pass" for c in gating), "gating_checks": len(gating)}))