Gated Knowledge-Guided Prototype Transfer for Zero-Support Medical Vision Language Model
Sumaiya Fazal, Rizwan Qureshi, Laleh Behjat, Samira Ebrahimi Kahou · SMASH 2026 posterRead the paper ↗
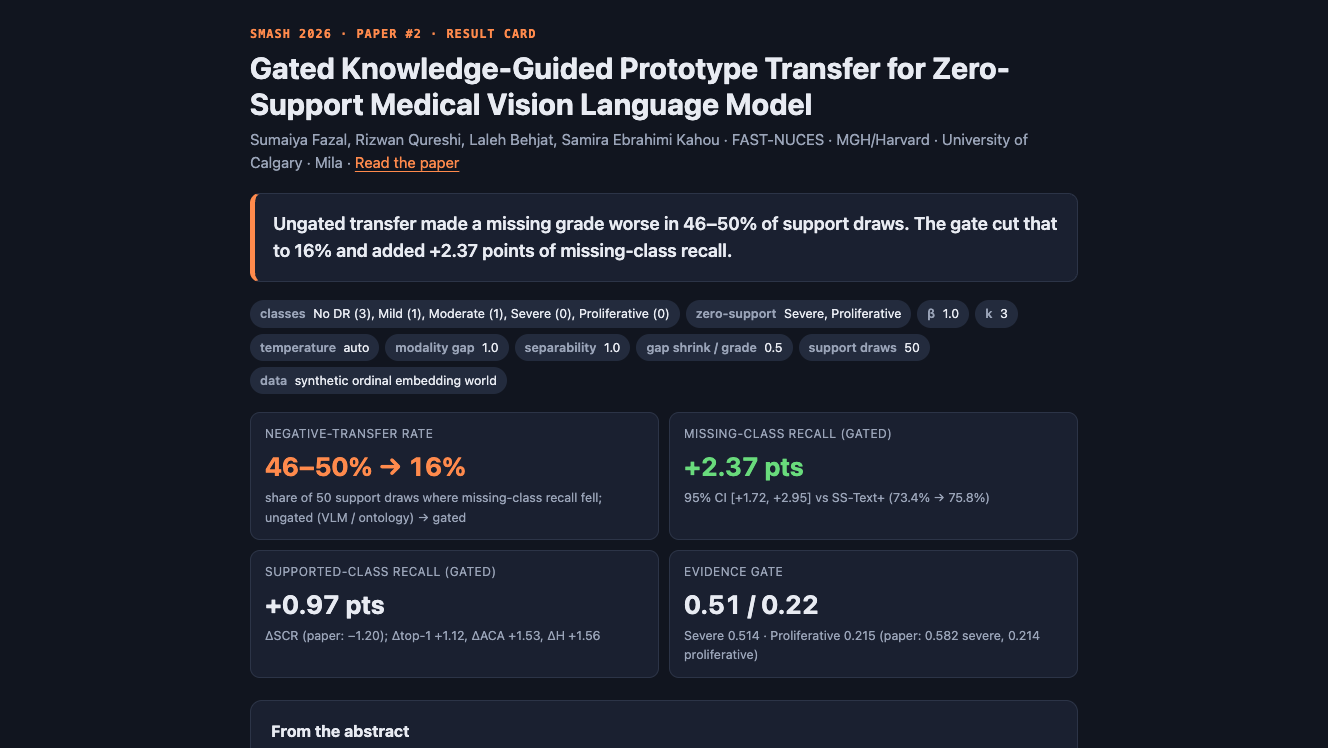
From the abstractWe introduce gated Knowledge-Guided Prototype Transfer (KGPT), a pre-repulsion module that transfers supported-class visual residuals to missing classes using VLM similarity and an ontology-based clinical distance. A validation-free evidence gate scales transfer based on semantic relevance and residual agreement, thereby limiting unsupported extrapolation.
Example runs
Default inputs
Ungated transfer made a missing grade worse in 46–50% of support draws. The gate cut that to 16% and added +2.37 points of missing-class recall. Synthetic embeddings stand in for MESSIDOR with FLAIR features. SS-Text+ is approximated with a shrinkage-plus-repulsion prototype.
Inputs
Acceptance checklist
15/15 checks passed.- Set up the sandbox and parameters
- Extract the tested code
- Run the experiment
- Write the narrative
- Render the result card and summary
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
- Result card, numbers, narrative and summary were written
- Experiment numbers are valid JSON and the experiment stayed within its time budget
- The narrative has a headline, three idea bullets, findings, try-next runs and caveats
- Every try-next suggestion uses only this runbook's parameters
- Every number in the headline appears in the run's results
- The card embeds its figures, shows the headline, and contains no NaN
Runbook
| version | 1.0.0 |
| evaluation | programmatic |
| evals_version | 2 |
| agent | claude-code |
| model | anthropic/claude-haiku-5.5 |
| model_provider | openrouter |
| snapshot | python312-uv |
| primary_outputs | result_card.html |
Borrowed Knowledge, Gated: When Does Transfer to an Unseen Class Backfire? (SMASH 2026 · Paper #2)
Objective
This runbook is an interactive companion to the SMASH 2026 paper "Gated Knowledge-Guided Prototype Transfer for Zero-Support Medical Vision Language Model" (Sumaiya Fazal, Rizwan Qureshi, Laleh Behjat, Samira Ebrahimi Kahou). Read the paper: https://drive.google.com/file/d/1TNzjU8LBvL9_Vo73FUBv9Oouxrt2rDfI/view?usp=sharing
The paper's setting: realistic few-shot adaptation of a medical vision-language model (VLM) samples support images by prevalence, so rare grades get zero labelled examples (on MESSIDOR every one-shot support set was [3, 1, 1, 0, 0]: no severe or proliferative diabetic retinopathy). The training-free SS-Text+ solver leaves such classes as pure text prototypes. Borrowing the visual correction of a related supported class sounds obvious, but the paper shows that ungated borrowing made missing-class recall worse in 46–48% of support draws. Its fix, gated Knowledge-Guided Prototype Transfer (KGPT), scales the borrowed correction by an evidence gate (agreement of the borrowed residuals × semantic relevance) and cut that negative-transfer rate (NTR) to 2%.
The participant chooses which classes have no support (bring your own ordinal label list), the transfer strength β, the number of neighbours k, and how the synthetic embedding world behaves. The run implements KGPT's equations exactly, compares SS-Text+, ungated KGPT-VLM, ungated KGPT-Ont and gated KGPT over many paired support draws, reports the paper's Top-1 / ACA / MCR / SCR / H / NTR, inspects every gate, and sweeps β to ask whether the gate is just a smaller step size. Output: a shareable result card.
Target wall-clock: under 4 minutes. The experiment itself takes about a second.
The method exactly as in the paper (§2.1)
- Supported S = {i : K_i > 0}, missing M = {c : K_c = 0}. Sources for a missing target come only from S (updated missing classes are never reused).
- Rank candidate sources by VLM text similarity
s_vlm = cos(t_c*, t_i), ontology proximitys_ont = −d(c*, i)(ordinal grade distance), or hybrid = mean of their z-scores. Keep the top k. - Weights
w_i = exp(s_i/T) / Σ exp(s_j/T); for a non-positive user temperature,T = max(std{s_i}, 1e−3). - Residuals
r_i = µ̂_i − t̂_i(unit-normalised pre-repulsion SS-Text+ prototype minus unit text prototype);r̄ = Σ w_i r_i; agreementa = ‖r̄‖ / (Σ w_i ‖r_i‖ + ε). - Relevance q: VLM = nearest-neighbour similarity margin above the candidate-row median (clipped to [0, 1]);
ontology =
1 / max(d_min, 1); hybrid = geometric mean. Gateg = clip[0,1](a·q),β_c* = β·g. - Update
p_c* = ‖t_c*‖ · (t̂_c* + β_c* r̄) / ‖t̂_c* + β_c* r̄‖, before SS-Text+'s all-class repulsion. - Ungated variants use g = 1 (KGPT-VLM: VLM ranking; KGPT-Ont: ontology ranking); gated uses hybrid ranking.
- Metrics: Top-1, ACA (mean recall over all classes), MCR (mean recall, missing classes), SCR (supported classes), H (harmonic mean of MCR and SCR), NTR (% of draws with ΔMCR < 0), severe NTR (ΔMCR < −5 points).
What is reconstructed (be explicit on the card)
- Synthetic world, not MESSIDOR/FLAIR. 256-d unit-norm "VLM" features: text prototypes whose similarities follow
an ordinal kernel (default geometry gives VLM relevance ≈ 0.40 / 0.14, near the paper's 0.381 / 0.102); image
clusters that share the ordinal structure, sit across a modality gap, and whose gap shrinks by
gap_shrinkper grade. That last property is what makes a full borrowed correction overshoot for higher grades; atgap_shrink = 0the borrowed correction is exactly right and ungated transfer is safe. - SS-Text+ is approximated: pre-repulsion prototype
µ_c = (Σ support features + λ t_c)/(K_c + λ)with λ = 1 (soµ_c = t_cwhen K_c = 0, the property KGPT relies on), all-class repulsion (each prototype pushed away from the mean of the others, strength 0.25), cosine inference. The real solver's closed form differs in detail.
Paper headline numbers (quote exactly; MESSIDOR, FLAIR features, 50 seeds, k = 3, β = 1)
- SS-Text+: Top-1 57.45, ACA 54.64, MCR 54.90, SCR 54.46, H 52.87.
- KGPT-VLM (ungated): ΔMCR −2.16 [−4.73, 0.32], NTR 46% (severe 38%). KGPT-Ont: ΔMCR −2.43 [−4.68, −0.21], NTR 48% (severe 34%).
- KGPT-Gated: MCR 60.12, ΔMCR +5.23 [3.84, 6.69], ΔACA +1.37 [0.78, 1.99], ΔH +1.83 [1.06, 2.64], ΔSCR −1.20 [−1.52, −0.88], ΔTop-1 −0.45 [−0.71, −0.19]; NTR 2% (36 improved, 13 unchanged, 1 worse).
- Mean gate 0.582±0.010 (severe; d_min 1, VLM relevance 0.381) vs 0.214±0.003 (proliferative; d_min 2, relevance 0.102). Moderate DR was the top source for both in all 50 seeds.
- Per-class recall severe / proliferative: gated 46.53 / 73.71; KGPT-VLM 37.47 / 68.00; KGPT-Ont 36.93 / 68.00.
REQUIRED OUTPUT FILES (MANDATORY)
All in {{results_dir}}:
| File | Description |
|---|---|
result_card.html | Primary output. Self-contained, shareable one-page result card |
results.json | All computed numbers (written by experiment.py) |
card_data.json | Numbers/figures for the card (written by experiment.py) |
narrative.json | Your interpretation of this run (Step 4) |
fig_*.png | Figures (written by experiment.py) |
summary.md | 5–10 line plain-text summary |
validation_report.json | Evals v2 report: steps, code checks, checklist (see Write Validation Report) |
Parameters
| Parameter | Template Variable | Default | Description |
|---|---|---|---|
| Ordinal class names | {{class_names}} | No DR,Mild,Moderate,Severe,Proliferative | Your ordinal label list, mildest first, comma-separated (3–8 classes). The ontology is this order |
| Support counts | {{support_counts}} | 3,1,1,0,0 | Labelled shots per class (same order). 0 = zero-support class. Paper: 3,1,1,0,0 |
| Transfer strength β | {{beta}} | 1.0 | Residual transfer strength (paper: 1). Gated KGPT uses β·g |
| Neighbours k | {{k}} | 3 | Top-k supported source classes per missing class (paper: 3) |
| Temperature | {{temperature}} | 0 | Softmax temperature; 0 = automatic T = max(std of scores, 1e−3) (paper) |
| Modality gap | {{modality_gap}} | 1.0 | Size of the image–text offset in the synthetic world (0 = none, 2 = large) |
| Separability | {{separability}} | 1.0 | How far apart image clusters of adjacent grades are (0.5 = hard, 2 = easy) |
| Gap shrink per grade | {{gap_shrink}} | 0.5 | How much less correction each higher grade needs. 0 = borrowed correction exactly right (ungated is safe) |
| Support draws | {{n_seeds}} | 50 | Paired random support sets (paper: 50) |
| World seed | {{world_seed}} | 0 | Seed of the synthetic embedding world (test set and prototypes) |
Dependencies
numpy and matplotlib (preinstalled in python312-uv). No downloads.
Step 1: Set up
mkdir -p {{results_dir}} /app/work && cd /app/work
python -c "import numpy, matplotlib" 2>/dev/null || uv pip install --system -q numpy matplotlib
Write /app/work/params.json (numbers as JSON numbers; if a value still looks like an unsubstituted {{…}}
placeholder, use the default from the table):
{"class_names": "{{class_names}}", "support_counts": "{{support_counts}}", "beta": {{beta}}, "k": {{k}},
 "temperature": {{temperature}}, "modality_gap": {{modality_gap}}, "separability": {{separability}},
 "gap_shrink": {{gap_shrink}}, "n_seeds": {{n_seeds}}, "world_seed": {{world_seed}}, "runbook_url": ""}
Validate before running: class_names must have 3–8 non-empty names and support_counts the same number of
non-negative integers, with at least one 0 and at least one positive count (otherwise fall back to both defaults).
Clamp beta to [0, 3], k to [1, 8], temperature to [0, 5], modality_gap to [0, 2], separability to
[0.3, 3], gap_shrink to [0, 0.9], n_seeds to [10, 200]. Record every correction as a caveat.
Step 2: Get the code (extract it, don't retype it)
The tested implementation of the method is embedded in the Appendix at the end of this runbook. Do not rewrite, "improve", or re-derive it. Always run the command below first, exactly as written. It copies the files out of this runbook's text (which the sandbox exposes to running processes) in about a second, and it is far faster and more reliable than retyping several hundred lines. Do not skip it on the assumption that it won't work: run it and read its output:
cd /app/work && cat > extract.py <<'PYEOF'
"""Extract the runbook's embedded files without retyping them.

The runbook text reaches the agent as one command-line argument, so it is readable from /proc.
Every embedded file sits under a heading "### `/app/work/<name>`" followed by one fenced block.
Exits non-zero if any requested file can't be found, so the caller falls back to writing it by hand.

usage: python3 extract.py <name> [<name> ...]   (writes /app/work/<name>)
"""
import ast, glob, re, sys
from pathlib import Path

want = sys.argv[1:]
cands = []
for p in glob.glob("/proc/[0-9]*/cmdline"):
    try:
        s = Path(p).read_bytes().decode("utf-8", "ignore")
    except OSError:
        continue
    if all(f"### `/app/work/{w}`" in s for w in want):
        cands.append(s)
if not cands:
    sys.exit("runbook text not found in /proc; write the files by hand")
# The agent's own argv holds the raw text; wrapper shells hold a shell-quoted copy, so prefer the shortest
# and undo shell single-quote escaping as a fallback.
best = min(cands, key=len).replace("'\"'\"'", "'")
ok = True
for w in want:
    m = re.search(r"### `/app/work/" + re.escape(w) + r"`\s*\n+```[a-z]*\n(.*?)\n```\n", best, re.S)
    if not m or len(m.group(1)) < 50:
        print(f"MISSING {w}"); ok = False; continue
    code = m.group(1) + "\n"
    if w.endswith(".py"):
        try:
            ast.parse(code)
        except SyntaxError as e:
            print(f"MISSING {w} (extracted text does not parse: {e})"); ok = False; continue
    Path("/app/work", w).write_text(code)
    print(f"extracted {w}: {code.count(chr(10))} lines")
sys.exit(0 if ok else 1)
PYEOF
python3 extract.py experiment.py render_card.py validate.py
If it exits non-zero or prints MISSING, write each missing file from the Appendix exactly as given, one
heredoc per file (quoted delimiter, e.g. cat > experiment.py <<'PYEOF'). If a later step fails, fix only
environment problems (missing package, network retry), never the methodology.
Step 3: Run the experiment
cd /app/work && export OMP_NUM_THREADS=4 OPENBLAS_NUM_THREADS=4 MKL_NUM_THREADS=4 SMASH_CPUS=4 && timeout 240 python experiment.py params.json {{results_dir}}Expected: about a second. Ends with a done: line (gated ΔMCR, NTR ungated → gated, gate per missing class).
The sandbox has 4 CPUs even though nproc may report more; the exports keep numpy/BLAS and process pools from oversubscribing them.
Step 4: Interpret: write narrative.json
Read {{results_dir}}/results.json and card_data.json, and look at every fig_*.png. Then write
{{results_dir}}/narrative.json with keys headline, idea (exactly 3), findings (2–4), try_next (2–3),
caveats (2–4):
- headline (≤ 30 words): the negative-transfer story of this run, with 1–2 numbers copied from
results.json(ntr_ungated_vlm,ntr_ungated_ont,ntr_gated,d_mcr_gated). E.g. "Borrowing without a gate made unseen grades worse in X% of draws; the evidence gate cut that to Y% and still added Z points." - idea: plain language: prevalence-based few-shot sampling leaves rare grades with no examples; borrowing a neighbour's visual correction can help or hurt; KGPT scales the borrowed correction by how consistent and how relevant the evidence is, with no extra labels, validation data or gradients.
- findings: (1) NTR and ΔMCR for the three methods vs the paper's Table 1 (
table); (2) the gate inspector (gate_inspector): which source dominated, and why the farther grade got the smaller gate; mention any class ingate_closed_classes(its gate is 0 because two supported neighbours are equally similar, so the VLM margin above the median is zero; the gate refuses to choose); (3) the β sweep (beta_sweep): at what β ungated transfer starts to hurt, and whether gated transfer at β = 1 sits near the best fixed β; (4) the cost on supported classes (d_scr_gated,d_top1_gated) vs the paper's −1.20 / −0.45. - Be honest where this world differs from MESSIDOR: absolute accuracies, SCR direction, and the gated NTR (the paper's 2% is lower than this world typically gives) are properties of the simulation.
- try_next: 2–3 contrasting runs with exact values, using only the keys
class_names, support_counts, beta, k, temperature, modality_gap, separability, gap_shrink, n_seeds, world_seed. Good contrasts:gap_shrink0 (borrowed correction is exactly right: does the gate now cost recall?); a middle grade with zero support (e.g.support_counts3,1,0,1,0: the gate inspector shows the closed gate);beta0.5 (is a fixed smaller step as safe as the gate?). - caveats: synthetic embedding world (not MESSIDOR or FLAIR); SS-Text+ approximated; the world's
gap_shrinkis the assumption that makes full transfer overshoot (the paper does not identify the cause); seeds vary only the identity of support images, as in the paper.
Step 5: Render the card and summary
cd /app/work && python render_card.py {{results_dir}}/card_data.json {{results_dir}}/narrative.json {{results_dir}}/result_card.htmlWrite {{results_dir}}/summary.md (5–10 lines: classes and support, NTR ungated → gated, gated ΔMCR with CI,
gates per missing class, β-sweep observation, headline).
Writing style for narrative.json
These rules apply to every field and override any longer limits stated earlier in this runbook. Let the paper and the numbers speak; the card is not the place for commentary.
- Length:
headlineone sentence;idea1–3 bullets of at most 30 words;findings1–2 paragraphs of at most 60 words each;caveats1–2 bullets of at most 20 words. Cut anything the tiles, figures or tables already show. - Plain statements of what was measured. Write "Sensitivity gap −0.284 [−0.354, −0.218]; the paper reports +0.088", not an interpretation of what it means for the field.
- Avoid: em-dash asides; "not X, but Y" framings; colon-then-reveal sentences; rhetorical questions; words such as crucially, notably, strikingly, remarkably, collapses, illustrating, underscores, highlights, delve, powerful, key insight, worth noting; exclamation marks; restating the method before the result.
- Use the paper's own terms for its concepts. Quote the paper's numbers exactly.
Code Checks
Jetty runs these checks itself in the sandbox after the agent finishes, so they cannot be skipped or
misreported. validate.py (see Write Validation Report) runs the same checks first so you can fix problems before you stop.
outputs-exist — Result card, numbers, narrative and summary were written
cd {{results_dir}} && for f in result_card.html results.json card_data.json narrative.json summary.md; do test -s "$f" || { echo "missing or empty: $f"; exit 1; }; done; echo "all 5 outputs present"results-valid — Experiment numbers are valid JSON and the experiment stayed within its time budget
python3 - "{{results_dir}}" 240 <<'PY'
import json, sys
from pathlib import Path
R, budget = Path(sys.argv[1]), float(sys.argv[2])
res = json.loads((R / "results.json").read_text())
json.loads((R / "card_data.json").read_text())
rt = float(res.get("runtime_sec", 0))
if rt > budget:
    sys.exit(f"experiment took {rt}s, budget {budget}s")
print(f"results.json and card_data.json parse; experiment {rt}s within {budget:.0f}s")
PY
narrative-complete — The narrative is complete and within the length limits
python3 - "{{results_dir}}" <<'PY'
import json, sys
from pathlib import Path
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
problems = []
if not str(n.get("headline", "")).strip(): problems.append("no headline")
if len(str(n.get("headline", "")).split()) > 45: problems.append("headline over 45 words")
if not 1 <= len(n.get("idea", [])) <= 3: problems.append(f"idea has {len(n.get('idea', []))} bullets, need 1-3")
if not 1 <= len(n.get("findings", [])) <= 2: problems.append(f"{len(n.get('findings', []))} findings, need 1-2")
if any(len(f.split()) > 70 for f in n.get("findings", [])): problems.append("a findings paragraph is over 60 words")
if not 2 <= len(n.get("try_next", [])) <= 3: problems.append(f"{len(n.get('try_next', []))} try_next, need 2-3")
if not 1 <= len(n.get("caveats", [])) <= 2: problems.append(f"{len(n.get('caveats', []))} caveats, need 1-2")
if problems: sys.exit("; ".join(problems))
print("headline, %d idea bullets, %d findings, %d try_next, %d caveats" % (len(n["idea"]), len(n["findings"]), len(n["try_next"]), len(n["caveats"])))
PY
try-next-valid — Every try-next suggestion uses only this runbook's parameters
python3 - "{{results_dir}}" "class_names,support_counts,beta,k,temperature,modality_gap,separability,gap_shrink,n_seeds,world_seed" <<'PY'
import json, sys
from pathlib import Path
allowed = set(sys.argv[2].split(","))
n = json.loads((Path(sys.argv[1]) / "narrative.json").read_text())
bad = sorted({k for t in n.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
empty = [t.get("label", "?") for t in n.get("try_next", []) if not t.get("params")]
if bad or empty: sys.exit(f"unknown parameters: {bad}; suggestions without params: {empty}")
print("all try_next parameters are declared runbook parameters")
PY
headline-grounded — Every number in the headline appears in the run's results
python3 - "{{results_dir}}" <<'PY'
import json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
blob = (R / "results.json").read_text() + (R / "card_data.json").read_text()
vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
head = json.loads((R / "narrative.json").read_text())["headline"]
nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", head)
missing = []
for n in nums:
    s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
    tol = 0.5 * 10 ** (-dec) + 1e-9
    if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
        missing.append(n)
if missing: sys.exit(f"headline numbers not found in results: {missing}")
print(f"{len(nums)} headline number(s) all grounded in results")
PY
card-integrity — The card embeds its figures, shows the headline, and contains no NaN
python3 - "{{results_dir}}" <<'PY'
import html, json, re, sys
from pathlib import Path
R = Path(sys.argv[1])
card = (R / "result_card.html").read_text()
text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
head = json.loads((R / "narrative.json").read_text())["headline"]
problems = []
if card.count("data:image/png;base64") < 1: problems.append("no embedded figures")
if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): problems.append("NaN/Infinity in card text")
if len(card) > 5_000_000: problems.append(f"card is {len(card) // 1024} KB")
plain = html.unescape(re.sub(r"<[^>]+>", "", text))
if re.sub(r"[*`]", "", head)[:40] not in plain: problems.append("headline not on card")
if problems: sys.exit("; ".join(problems))
print(f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures, headline present")
PY
Checklist
- The headline states this run's finding with its numbers, not a description of the method
- Paper numbers are quoted exactly and any disagreement with the paper is stated plainly
- Caveats say what is synthetic, reconstructed or an extension of the paper
- Each try-next suggestion would plausibly give a contrasting result
Write Validation Report
Judge the four Checklist items honestly against your outputs and write them to /app/work/checklist.json as a
list, using the checklist ids Jetty gives you (one entry per item):
[{"id": "<checklist id>", "status": "pass", "message": "one line on why"}]Then write the report and self-check in one command:
cd /app/work && python3 validate.py {{results_dir}} class_names,support_counts,beta,k,temperature,modality_gap,separability,gap_shrink,n_seeds,world_seed 240 checklist.jsonvalidate.py writes {{results_dir}}/validation_report.json in the v2 shape Jetty reads (version: 2, one
step entry per runbook step, one code_check entry per check above, one checklist entry per item). Jetty
replaces the code_check entries with its own independent run of the same checks. Do not write the report by hand.
Iteration (up to 2 rounds)
If validate.py prints any FAIL, fix the named problem (usually a headline number that does not match
results.json, or an unknown try_next key), re-render the card (Step 5) and rerun the command above. Never
rerun the experiment just to change the narrative.
Appendix: code
These files are extracted verbatim in Step 2.
/app/work/experiment.py
"""Gated Knowledge-Guided Prototype Transfer (KGPT) — SMASH 2026 paper #2 (Fazal, Qureshi, Behjat, Kahou).

Re-enacts the paper's realistic one-shot experiment on a synthetic ordinal "VLM embedding world":
some ordinal classes get zero labelled support; SS-Text+-style prototypes leave them text-only; KGPT
transfers visual residuals from supported classes (VLM / ontology / hybrid ranking, softmax weights with
automatic temperature, agreement a, relevance q, gate g = clip(a·q)) before the repulsion step.
Reports Top-1 / ACA / MCR / SCR / H and the negative-transfer rate (NTR) over many support draws.

usage: python experiment.py params.json outdir
"""
import json, sys, time
from pathlib import Path

import numpy as np
import matplotlib
matplotlib.use("Agg")
import matplotlib.pyplot as plt

T0 = time.time()
P = json.loads(Path(sys.argv[1]).read_text())
OUT = Path(sys.argv[2]); OUT.mkdir(parents=True, exist_ok=True)

NAMES = [s.strip() for s in str(P["class_names"]).split(",") if s.strip()]
C = len(NAMES)
COUNTS = np.array([int(float(x)) for x in str(P["support_counts"]).split(",")])
assert len(COUNTS) == C, "support_counts must have one entry per class"
assert (COUNTS > 0).any() and (COUNTS == 0).any(), "need at least one supported and one zero-support class"
BETA = float(P["beta"]); K_NB = int(P["k"]); TEMP = float(P["temperature"])
GAP = float(P["modality_gap"]); SEP = float(P["separability"]); SHRINK = float(P["gap_shrink"])
SEEDS = int(P["n_seeds"]); WSEED = int(P.get("world_seed", 0))
S_SET = [i for i in range(C) if COUNTS[i] > 0]
M_SET = [c for c in range(C) if COUNTS[c] == 0]
EPS = 1e-8

# ------------------------------------------------------------------ the synthetic world (fixed per world_seed)
N_TEST = 1200
LAM = 1.0        # SS-Text-style class-adaptive shrinkage toward the text prototype (Kc = 0 -> text only)
REP = 0.25       # all-class repulsion strength (applied after KGPT, as in the paper)
# world geometry (calibrated once so the default reproduces the paper's qualitative pattern; see RUNBOOK)
W = {"ell": 1.3, "last_step": 1.4, "kappa": 0.3, "gap": 1.0, "omega": 0.3, "sigma": 1.0, "sigma_ord": 0.15,
     "sigma_gap": 0.3, "D": 256}
import os
W.update(json.loads(os.environ.get("KGPT_WORLD", "{}")))
D = int(W.get("D", 256))


def log(m):
    print(f"[{time.time() - T0:6.1f}s] {m}", flush=True)


def unit(x, axis=-1):
    return x / (np.linalg.norm(x, axis=axis, keepdims=True) + 1e-12)


def make_world(rng):
    """Text prototypes: a "true" ordinal semantic part whose cosine similarities follow a Gaussian kernel on grade
    positions (grades 1 apart; the last grade a longer step away, a qualitatively distinct finding), plus a
    text-only part (wording) that no image shares. Image class centres share the ordinal part (scaled by
    kappa x separability) and are offset by a common modality gap. A supported class's residual therefore
    holds a transferable part (the gap) and a class-specific part (undoing *its own* wording), which is
    wrong for any other class: copying it in full is how residual transfer can hurt."""
    Q, _ = np.linalg.qr(rng.standard_normal((D, D)))
    pos = np.arange(C, dtype=float); pos[-1] = pos[-2] + W["last_step"]
    G = np.exp(-(pos[:, None] - pos[None, :]) ** 2 / (2 * W["ell"] ** 2))
    Lc = np.linalg.cholesky(G + 1e-9 * np.eye(C))      # rows of Lc have Gram matrix G
    basis = Q[:, :C]
    sem = Lc @ basis.T                                  # (C, D) unit semantic directions
    gap_dir = Q[:, C]
    wording = Q[:, C + 1:2 * C + 1].T                   # text-only directions, one per class
    t = sem + W["omega"] * wording
    shrink = (1 - SHRINK) ** pos                        # image-text offset shrinks by SHRINK per grade (0 = constant)
    m = W["kappa"] * SEP * sem + W["gap"] * GAP * shrink[:, None] * gap_dir[None, :]
    sub = np.vstack([basis.T, gap_dir])                 # "severity" subspace for structured image noise
    return unit(t), m, sub


def sample_images(rng, world, cls, n):
    """Images = class centre + isotropic noise (total norm ~sigma) + severity-subspace noise, L2-normalised."""
    _, m, sub = world
    x = m[cls] + W["sigma"] * rng.standard_normal((n, D)) / np.sqrt(D)
    x = x + W["sigma_ord"] * rng.standard_normal((n, len(sub) - 1)) @ sub[:-1] / np.sqrt(len(sub) - 1)
    x = x + W["sigma_gap"] * GAP * rng.standard_normal((n, 1)) * sub[-1]   # per-image modality offset (quality, illumination)
    return unit(x)


# ------------------------------------------------------------------ SS-Text+ (approximation) and KGPT
def sstext_prototypes(t, support_x, support_y):
    """Pre-repulsion prototypes: mu_c = (sum of support features + LAM * t_c) / (K_c + LAM).
    For K_c = 0 this is exactly t_c (the property KGPT relies on, paper §2.1)."""
    mu = np.zeros_like(t)
    for c in range(C):
        xs = support_x[support_y == c]
        mu[c] = (xs.sum(0) + LAM * t[c]) / (len(xs) + LAM)
    return mu


def repel_and_normalise(p):
    """All-class repulsion (each prototype pushed away from the mean of the others) + inference normalisation."""
    ph = unit(p)
    out = np.zeros_like(ph)
    for c in range(C):
        others = np.delete(ph, c, 0).mean(0)
        out[c] = ph[c] - REP * others
    return unit(out)


def zscore(v):
    v = np.asarray(v, float)
    return (v - v.mean()) / (v.std() + 1e-12)


def kgpt(t, mu, ranking, gated, beta=BETA, k=K_NB, temp=TEMP):
    """Paper §2.1, Eqs. 1-3. Sources only from originally supported classes (non-recursive)."""
    th = unit(t)
    r = unit(mu) - th                          # residual r_i = mu^_i - t^_i
    p = mu.copy()
    info = {}
    S = np.array(S_SET)
    for cs in M_SET:
        s_vlm = np.array([float(th[cs] @ th[i]) for i in S])
        d = np.array([abs(cs - i) for i in S], float)
        s_ont = -d
        s = {"vlm": s_vlm, "ontology": s_ont, "hybrid": (zscore(s_vlm) + zscore(s_ont)) / 2}[ranking]
        kk = min(k, len(S))
        order = np.lexsort((d, -s))[:kk]       # top-k by score (ties broken by ontology distance)
        sel = s[order]
        T = temp if temp > 0 else max(float(np.std(sel)), 1e-3)   # validation-free auto temperature
        w = np.exp((sel - sel.max()) / T); w = w / w.sum()          # Eq. 1
        rr = r[S[order]]
        rbar = (w[:, None] * rr).sum(0)                             # Eq. 2
        a = float(np.linalg.norm(rbar) / ((w * np.linalg.norm(rr, axis=1)).sum() + EPS))
        q_vlm = float(np.clip(s_vlm.max() - np.median(s_vlm), 0, 1))  # NN margin above candidate-row median
        q_ont = float(1 / max(d.min(), 1))
        q = {"vlm": q_vlm, "ontology": q_ont, "hybrid": float(np.sqrt(q_vlm * q_ont))}[ranking]
        g = float(np.clip(a * q, 0, 1)) if gated else 1.0
        b_eff = beta * g
        v = th[cs] + b_eff * rbar
        p[cs] = np.linalg.norm(t[cs]) * v / np.linalg.norm(v)      # Eq. 3
        info[NAMES[cs]] = {"sources": [NAMES[i] for i in S[order]], "weights": w.tolist(),
                           "top_source": NAMES[S[order][int(np.argmax(w))]], "a": a, "q_vlm": q_vlm,
                           "q_ont": q_ont, "q": q, "gate": g if gated else None, "beta_eff": b_eff,
                           "d_min": float(d.min())}
    return p, info


def evaluate(p, X, y):
    pr = repel_and_normalise(p)
    pred = np.argmax(X @ pr.T, 1)
    rec = np.array([np.mean(pred[y == c] == c) for c in range(C)])
    mcr, scr = rec[M_SET].mean(), rec[S_SET].mean()
    return {"top1": float(np.mean(pred == y)), "aca": float(rec.mean()), "mcr": float(mcr), "scr": float(scr),
            "h": float(2 * mcr * scr / (mcr + scr + 1e-12)), "recall": rec.tolist()}


METHODS = {"SS-Text+": None, "KGPT-VLM": ("vlm", False), "KGPT-Ont": ("ontology", False),
           "KGPT-Gated": ("hybrid", True)}


def boot_ci(v, rng, B=2000):
    v = np.asarray(v)
    bs = v[rng.integers(0, len(v), (B, len(v)))].mean(1)
    return [float(np.percentile(bs, 2.5)), float(np.percentile(bs, 97.5))]


def main():
    wrng = np.random.default_rng(1000 + WSEED)
    world = make_world(wrng); t, m = world[0], world[1]
    # test prevalence: MESSIDOR-like (no DR dominant); generalised for any C
    prev = np.r_[0.46, np.full(C - 1, 0.54 / (C - 1))]
    if C == 5:
        prev = np.array([0.46, 0.13, 0.20, 0.11, 0.10])
    n_c = np.maximum((prev * N_TEST).round().astype(int), 30)
    y_te = np.repeat(np.arange(C), n_c)
    X_te = np.vstack([sample_images(wrng, world, c, n) for c, n in enumerate(n_c)])
    pool = {c: sample_images(wrng, world, c, 400) for c in range(C)}
    log(f"world: {C} classes, D={D}, test n={len(y_te)}, supported {[NAMES[i] for i in S_SET]}, "
        f"zero-support {[NAMES[c] for c in M_SET]}")

    per_seed = {k: [] for k in METHODS}
    infos = []
    for seed in range(SEEDS):
        rng = np.random.default_rng(seed)
        idx = {c: rng.choice(400, COUNTS[c], replace=False) for c in range(C)}
        sx = np.vstack([pool[c][idx[c]] for c in range(C) if COUNTS[c] > 0])
        sy = np.concatenate([np.full(COUNTS[c], c) for c in range(C) if COUNTS[c] > 0])
        mu = sstext_prototypes(t, sx, sy)
        for name, cfg in METHODS.items():
            if cfg is None:
                p, info = mu, None
            else:
                p, info = kgpt(t, mu, *cfg)
            per_seed[name].append(evaluate(p, X_te, y_te))
            if name == "KGPT-Gated":
                infos.append(info)
    log(f"{SEEDS} support draws x {len(METHODS)} methods evaluated")

    rng = np.random.default_rng(0)
    base = per_seed["SS-Text+"]
    table = {}
    for name in METHODS:
        rows = per_seed[name]
        e = {k: 100 * float(np.mean([r[k] for r in rows])) for k in ("top1", "aca", "mcr", "scr", "h")}
        e["recall"] = (100 * np.mean([r["recall"] for r in rows], 0)).tolist()
        if name != "SS-Text+":
            for k in ("top1", "aca", "mcr", "scr", "h"):
                dv = [100 * (r[k] - b[k]) for r, b in zip(rows, base)]
                e[f"d_{k}"] = float(np.mean(dv)); e[f"d_{k}_ci"] = boot_ci(dv, rng)
            dm = np.array([100 * (r["mcr"] - b["mcr"]) for r, b in zip(rows, base)])
            e["ntr"] = float(100 * np.mean(dm < -1e-9)); e["ntr_severe"] = float(100 * np.mean(dm < -5))
            e["n_improved"] = int(np.sum(dm > 1e-9)); e["n_unchanged"] = int(np.sum(np.abs(dm) <= 1e-9))
            e["d_mcr_per_seed"] = dm.tolist()
        table[name] = e

    gate = {}
    for cname in infos[0]:
        gs = [inf[cname] for inf in infos]
        gate[cname] = {"gate_mean": float(np.mean([g["gate"] for g in gs])), "gate_sd": float(np.std([g["gate"] for g in gs])),
                       "a_mean": float(np.mean([g["a"] for g in gs])), "q_vlm": float(np.mean([g["q_vlm"] for g in gs])),
                       "q_ont": gs[0]["q_ont"], "q_hybrid": float(np.mean([g["q"] for g in gs])), "d_min": gs[0]["d_min"],
                       "top_source_counts": {s: sum(g["top_source"] == s for g in gs) for s in set(g["top_source"] for g in gs)}}

    # extension 1: beta sweep, gate on vs off (same hybrid ranking) -> is the gate just a step size?
    betas = [0.0, 0.1, 0.2, 0.3, 0.45, 0.6, 0.8, 1.0, 1.25, 1.5, 2.0]
    sweep = {"beta": betas, "ungated_d_mcr": [], "ungated_ntr": [], "gated_d_mcr": [], "gated_ntr": [],
             "ungated_d_aca": [], "gated_d_aca": []}
    for b in betas:
        for gated in (False, True):
            dm, da = [], []
            for seed in range(SEEDS):
                rng2 = np.random.default_rng(seed)
                idx = {c: rng2.choice(400, COUNTS[c], replace=False) for c in range(C)}
                sx = np.vstack([pool[c][idx[c]] for c in range(C) if COUNTS[c] > 0])
                sy = np.concatenate([np.full(COUNTS[c], c) for c in range(C) if COUNTS[c] > 0])
                mu = sstext_prototypes(t, sx, sy)
                r = evaluate(kgpt(t, mu, "hybrid", gated, beta=b)[0], X_te, y_te)
                dm.append(100 * (r["mcr"] - base[seed]["mcr"])); da.append(100 * (r["aca"] - base[seed]["aca"]))
            key = "gated" if gated else "ungated"
            sweep[f"{key}_d_mcr"].append(float(np.mean(dm))); sweep[f"{key}_d_aca"].append(float(np.mean(da)))
            sweep[f"{key}_ntr"].append(float(100 * np.mean(np.array(dm) < -1e-9)))
    log("beta sweep done")

    # paper sanity check: the paper's own relevances reproduce its gates through g = clip(a * sqrt(q_vlm * q_ont))
    paper_check = {}
    for cname, qv, dmin, g in [("Severe DR", 0.381, 1, 0.582), ("Proliferative DR", 0.102, 2, 0.214)]:
        qh = float(np.sqrt(qv * (1 / dmin)))
        paper_check[cname] = {"q_vlm": qv, "q_ont": 1 / dmin, "q_hybrid": qh, "gate_paper": g, "implied_a": g / qh}

    g_t = table["KGPT-Gated"]; best_ung = min(table["KGPT-VLM"]["ntr"], table["KGPT-Ont"]["ntr"])
    res = {"params": P, "classes": NAMES, "support_counts": COUNTS.tolist(), "supported": [NAMES[i] for i in S_SET],
           "zero_support": [NAMES[c] for c in M_SET], "test_n_per_class": n_c.tolist(), "table": table,
           "gate_inspector": gate, "paper_gate_check": paper_check, "beta_sweep": sweep,
           "ntr_ungated_vlm": table["KGPT-VLM"]["ntr"], "ntr_ungated_ont": table["KGPT-Ont"]["ntr"],
           "ntr_gated": g_t["ntr"], "d_mcr_gated": g_t["d_mcr"], "d_aca_gated": g_t["d_aca"],
           "d_scr_gated": g_t["d_scr"], "d_h_gated": g_t["d_h"], "d_top1_gated": g_t["d_top1"],
           "ntr_reduction_points": float(best_ung - g_t["ntr"]),
           "gate_closed_classes": [k for k, v in gate.items() if v["gate_mean"] < 0.01],
           "world": {"D": D, "geometry": W, "repulsion": REP, "lambda": LAM, "modality_gap": GAP, "separability": SEP}}
    figures(res)
    card(res)
    res["runtime_sec"] = round(time.time() - T0, 1)
    (OUT / "results.json").write_text(json.dumps(res, indent=2))
    log(f"done: dMCR gated {g_t['d_mcr']:+.2f} pts; NTR VLM {table['KGPT-VLM']['ntr']:.0f}% / Ont "
        f"{table['KGPT-Ont']['ntr']:.0f}% -> gated {g_t['ntr']:.0f}%; gates "
        + ", ".join(f"{k} {v['gate_mean']:.3f}" for k, v in gate.items()))


INK, ACC, BLUE, MUTED, GOOD = "#1f2a44", "#d9480f", "#1971c2", "#868e96", "#2b8a3e"


def figures(res):
    plt.rcParams.update({"font.size": 10, "axes.spines.top": False, "axes.spines.right": False})
    tab = res["table"]
    # Fig 1: per-seed paired change in MCR — negative transfer is the story
    fig, ax = plt.subplots(figsize=(6.4, 3.4))
    meths = ["KGPT-VLM", "KGPT-Ont", "KGPT-Gated"]
    cols = [BLUE, "#7048e8", GOOD]
    jit = np.random.default_rng(1)
    for i, (mname, col) in enumerate(zip(meths, cols)):
        dm = np.array(tab[mname]["d_mcr_per_seed"])
        xs = i + jit.uniform(-0.18, 0.18, len(dm))
        ax.scatter(xs[dm >= -1e-9], dm[dm >= -1e-9], s=16, color=col, alpha=0.75, lw=0)
        ax.scatter(xs[dm < -1e-9], dm[dm < -1e-9], s=18, color=ACC, alpha=0.9, lw=0)
        ax.plot([i - 0.28, i + 0.28], [dm.mean()] * 2, color=INK, lw=2)
        ax.annotate(f"NTR {tab[mname]['ntr']:.0f}%\nmean {tab[mname]['d_mcr']:+.1f}", (i, 1.0), xycoords=("data", "axes fraction"),
                    ha="center", va="top", fontsize=8.5, color=INK)
    ax.axhline(0, color=MUTED, lw=1, ls="--")
    ax.axhline(-5, color=ACC, lw=0.8, ls=":")
    ax.set_xticks(range(3)); ax.set_xticklabels(["ungated, VLM rank", "ungated, ontology rank", "gated, hybrid rank"])
    lo, hi = ax.get_ylim(); ax.set_ylim(lo, hi + (hi - lo) * 0.28)
    ax.set_ylabel("Δ missing-class recall vs SS-Text+\n(points, one dot per support draw)", fontsize=9)
    fig.tight_layout(); fig.savefig(OUT / "fig_negative_transfer.png", dpi=160); plt.close(fig)

    # Fig 2: beta sweep — the gate as an evidence-scaled step size
    sw = res["beta_sweep"]
    fig, axs = plt.subplots(1, 2, figsize=(6.4, 2.9))
    axs[0].plot(sw["beta"], sw["ungated_d_mcr"], "o-", color=BLUE, ms=4, label="ungated (g = 1)")
    axs[0].plot(sw["beta"], sw["gated_d_mcr"], "o-", color=GOOD, ms=4, label="gated (β·g)")
    axs[0].axhline(0, color=MUTED, lw=1, ls="--"); axs[0].axvline(BETA, color=INK, lw=0.8, ls=":")
    axs[0].set_xlabel("transfer strength β"); axs[0].set_ylabel("mean Δ MCR (points)"); axs[0].legend(frameon=False, fontsize=8)
    axs[1].plot(sw["beta"], sw["ungated_ntr"], "o-", color=BLUE, ms=4)
    axs[1].plot(sw["beta"], sw["gated_ntr"], "o-", color=GOOD, ms=4)
    axs[1].axvline(BETA, color=INK, lw=0.8, ls=":")
    axs[1].set_xlabel("transfer strength β"); axs[1].set_ylabel("negative-transfer rate (%)"); axs[1].set_ylim(-3, 103)
    fig.tight_layout(); fig.savefig(OUT / "fig_beta_sweep.png", dpi=160); plt.close(fig)

    # Fig 3: gate inspector
    gi = res["gate_inspector"]
    names = list(gi)
    fig, ax = plt.subplots(figsize=(6.4, 0.9 + 0.75 * len(names)))
    comps = [("agreement a", "a_mean", MUTED), ("relevance q (hybrid)", "q_hybrid", BLUE), ("gate g = clip(a·q)", "gate_mean", GOOD)]
    hgt = 0.24
    for j, (lab, key, col) in enumerate(comps):
        vals = [gi[n][key] for n in names]
        ys = np.arange(len(names)) + (j - 1) * hgt
        ax.barh(ys, vals, height=hgt * 0.92, color=col, label=lab)
        for yv, v in zip(ys, vals):
            ax.text(v + 0.01, yv, f"{v:.3f}", va="center", fontsize=8)
    pc = res["paper_gate_check"]
    if C == 5 and len(names) == 2:
        for i, (n, pk) in enumerate(zip(names, ["Severe DR", "Proliferative DR"])):
            ax.plot([pc[pk]["gate_paper"]] * 2, [i + hgt * 0.5, i + hgt * 1.5], color=ACC, lw=2.2)
        ax.plot([], [], color=ACC, lw=2.2, label="paper's gate (0.582 / 0.214)")
    ax.set_yticks(range(len(names)))
    ax.set_yticklabels([f"{n}\n(d_min={gi[n]['d_min']:.0f}, q_vlm={gi[n]['q_vlm']:.2f})" for n in names], fontsize=8.5)
    ax.set_xlim(0, 1.1); ax.invert_yaxis(); ax.set_xlabel("value (mean over support draws)")
    ax.legend(frameon=False, fontsize=7.5, ncol=2, loc="upper center", bbox_to_anchor=(0.45, -0.18 - 0.5 / (0.9 + 0.75 * len(names))))
    fig.tight_layout(); fig.savefig(OUT / "fig_gate_inspector.png", dpi=160, bbox_inches="tight"); plt.close(fig)

    # Fig 4: per-class recall, SS-Text+ vs ungated vs gated
    fig, ax = plt.subplots(figsize=(6.4, 3.0))
    wdt = 0.26
    for j, (mname, col) in enumerate([("SS-Text+", MUTED), ("KGPT-VLM", BLUE), ("KGPT-Gated", GOOD)]):
        rec = tab[mname]["recall"]
        xs = np.arange(C) + (j - 1) * wdt
        ax.bar(xs, rec, width=wdt * 0.95, color=col, label={"SS-Text+": "SS-Text+ (text-only for zero-support)",
                                                           "KGPT-VLM": "ungated KGPT-VLM", "KGPT-Gated": "gated KGPT"}[mname])
    for c in M_SET:
        ax.axvspan(c - 0.45, c + 0.45, color=ACC, alpha=0.07, lw=0)
    ax.set_xticks(range(C)); ax.set_xticklabels([f"{n}\n({k} shot{'s' if k != 1 else ''})" for n, k in zip(NAMES, COUNTS)], fontsize=8.5)
    ax.set_ylabel("recall (%)"); ax.set_ylim(0, 112)
    ax.legend(frameon=False, fontsize=7.5, ncol=3, loc="upper center", bbox_to_anchor=(0.5, 1.13))
    fig.tight_layout(); fig.savefig(OUT / "fig_per_class_recall.png", dpi=160); plt.close(fig)


def card(res):
    tab = res["table"]; g = tab["KGPT-Gated"]
    gi = res["gate_inspector"]
    gate_str = " · ".join(f"{k} {v['gate_mean']:.3f}" for k, v in gi.items())
    tiles = [
        {"label": "Negative-transfer rate", "value": f"{min(res['ntr_ungated_vlm'], res['ntr_ungated_ont']):.0f}–"
                                                     f"{max(res['ntr_ungated_vlm'], res['ntr_ungated_ont']):.0f}% → {res['ntr_gated']:.0f}%",
         "sub": f"share of {SEEDS} support draws where missing-class recall fell; ungated (VLM / ontology) → gated", "tone": "accent"},
        {"label": "Missing-class recall (gated)", "value": f"{g['d_mcr']:+.2f} pts",
         "sub": f"95% CI [{g['d_mcr_ci'][0]:+.2f}, {g['d_mcr_ci'][1]:+.2f}] vs SS-Text+ ({tab['SS-Text+']['mcr']:.1f}% → {g['mcr']:.1f}%)",
         "tone": "good" if g["d_mcr"] > 0 else "warn"},
        {"label": "Supported-class recall (gated)", "value": f"{g['d_scr']:+.2f} pts",
         "sub": f"ΔSCR (paper: −1.20); Δtop-1 {g['d_top1']:+.2f}, ΔACA {g['d_aca']:+.2f}, ΔH {g['d_h']:+.2f}", "tone": "neutral"},
        {"label": "Evidence gate", "value": " / ".join(f"{v['gate_mean']:.2f}" for v in gi.values()),
         "sub": gate_str + " (paper: 0.582 severe, 0.214 proliferative)", "tone": "neutral"},
    ]
    inputs = {"classes": ", ".join(f"{n} ({k})" for n, k in zip(NAMES, COUNTS)), "zero-support": ", ".join(res["zero_support"]),
              "β": BETA, "k": K_NB, "temperature": "auto" if TEMP <= 0 else TEMP, "modality gap": GAP,
              "separability": SEP, "gap shrink / grade": SHRINK, "support draws": SEEDS, "data": "synthetic ordinal embedding world"}
    fmt = lambda e: f"{e['top1']:.1f} / {e['aca']:.1f} / {e['mcr']:.1f} / {e['scr']:.1f} / {e['h']:.1f}"
    compare = [
        {"metric": "SS-Text+ Top-1 / ACA / MCR / SCR / H", "paper": "57.45 / 54.64 / 54.90 / 54.46 / 52.87",
         "yours": fmt(tab["SS-Text+"]), "note": "absolute levels depend on the synthetic world"},
        {"metric": "Ungated NTR (VLM / Ont), severe NTR", "paper": "46% / 48%; severe 38% / 34%",
         "yours": f"{tab['KGPT-VLM']['ntr']:.0f}% / {tab['KGPT-Ont']['ntr']:.0f}%; severe {tab['KGPT-VLM']['ntr_severe']:.0f}% / {tab['KGPT-Ont']['ntr_severe']:.0f}%",
         "note": "NTR = share of draws with ΔMCR < 0; severe = ΔMCR < −5"},
        {"metric": "Ungated ΔMCR (VLM / Ont)", "paper": "−2.16 [−4.73, 0.32] / −2.43 [−4.68, −0.21]",
         "yours": f"{tab['KGPT-VLM']['d_mcr']:+.2f} [{tab['KGPT-VLM']['d_mcr_ci'][0]:+.2f}, {tab['KGPT-VLM']['d_mcr_ci'][1]:+.2f}] / "
                  f"{tab['KGPT-Ont']['d_mcr']:+.2f} [{tab['KGPT-Ont']['d_mcr_ci'][0]:+.2f}, {tab['KGPT-Ont']['d_mcr_ci'][1]:+.2f}]", "note": ""},
        {"metric": "Gated ΔMCR / ΔACA / ΔH", "paper": "+5.23 [3.84, 6.69] / +1.37 [0.78, 1.99] / +1.83 [1.06, 2.64]",
         "yours": f"{g['d_mcr']:+.2f} [{g['d_mcr_ci'][0]:+.2f}, {g['d_mcr_ci'][1]:+.2f}] / {g['d_aca']:+.2f} / {g['d_h']:+.2f}", "note": ""},
        {"metric": "Gated ΔSCR / ΔTop-1", "paper": "−1.20 [−1.52, −0.88] / −0.45 [−0.71, −0.19]",
         "yours": f"{g['d_scr']:+.2f} / {g['d_top1']:+.2f}", "note": "the price of transfer"},
        {"metric": "Gated NTR; draws improved / unchanged", "paper": "2%; 36 improved, 13 unchanged of 50",
         "yours": f"{g['ntr']:.0f}%; {g['n_improved']} improved, {g['n_unchanged']} unchanged of {SEEDS}", "note": ""},
        {"metric": "Mean gate (severe / proliferative)", "paper": "0.582±0.010 / 0.214±0.003",
         "yours": " / ".join(f"{v['gate_mean']:.3f}±{v['gate_sd']:.3f}" for v in gi.values()),
         "note": "paper relevances 0.381 / 0.102 imply agreement a ≈ 0.94–0.95"},
    ]
    figs = [{"path": "fig_negative_transfer.png", "title": "How often does borrowing knowledge make the missing classes worse?",
             "caption": "Each dot is one random support draw (same support for all methods). Orange dots: missing-class recall fell "
                        "relative to SS-Text+ (negative transfer). Black bar = mean. Dotted line = −5 points (severe negative transfer)."},
            {"path": "fig_beta_sweep.png", "title": "Is the gate just a smaller step size?",
             "caption": "Same hybrid neighbours, transfer strength β varied. Ungated uses the full β; gated uses β·g with g from the "
                        "evidence (agreement × relevance). Dotted line = your β. Extension, not in the paper."},
            {"path": "fig_gate_inspector.png", "title": "Gate inspector: why each zero-support class gets the update it gets",
             "caption": "Agreement a = how much the selected residuals point the same way; relevance q = √(VLM margin × 1/ontology distance). "
                        "Orange ticks: the paper's MESSIDOR gates."},
            {"path": "fig_per_class_recall.png", "title": "Who pays, who gains? Recall per class",
             "caption": "Mean recall over support draws. Shaded = zero-support classes. Paper (MESSIDOR), severe / proliferative recall: "
                        "gated 46.53 / 73.71 vs KGPT-VLM 37.47 / 68.00."}]
    Path(OUT / "card_data.json").write_text(json.dumps({
        "paper": {"num": 2, "title": "Gated Knowledge-Guided Prototype Transfer for Zero-Support Medical Vision Language Model",
                  "authors": "Sumaiya Fazal, Rizwan Qureshi, Laleh Behjat, Samira Ebrahimi Kahou", "url": "https://drive.google.com/file/d/1TNzjU8LBvL9_Vo73FUBv9Oouxrt2rDfI/view?usp=sharing",
                  "affiliation": "FAST-NUCES · MGH/Harvard · University of Calgary · Mila"},
        "inputs": inputs, "tiles": tiles, "figures": figs, "compare": compare,
        "runbook": {"name": "smash-02-gated-kgpt", "url": P.get("runbook_url", "")}}, indent=2))


if __name__ == "__main__":
    main()
/app/work/render_card.py
"""Render a SMASH 2026 paper-playground result card (one self-contained HTML file).

usage: python render_card.py card_data.json narrative.json out.html

card_data.json  (written by the experiment script — numbers only)
  paper:   {num, title, authors, affiliation, url?}
  inputs:  {label: value}                         the participant's run settings
  tiles:   [{label, value, sub, tone}]            tone: accent|good|warn|neutral
  figures: [{path, title, caption}]               PNGs, embedded as base64
  compare: [{metric, paper, yours, note}]         paper-vs-your-run table (optional)
  runbook: {name, url}                            fork link (optional)
narrative.json  (written by the agent — words only)
  headline:  one sentence, the finding of THIS run
  idea:      [1-3 bullets] the paper's contribution in plain language
  abstract:  (optional) a verbatim abstract excerpt, shown instead of idea
  findings:  [2-4 short paragraphs] what this run shows, tied to the numbers
  try_next:  [{label, why, params}]               2-3 follow-up runs with exact parameter values
  caveats:   [bullets]
"""
import base64, html, json, sys
from pathlib import Path

data = json.loads(Path(sys.argv[1]).read_text())
narr = json.loads(Path(sys.argv[2]).read_text())
base = Path(sys.argv[1]).parent
e = lambda s: html.escape(str(s))


def md_inline(s):
    """Escape, then allow **bold**, *italic* and `code` only."""
    import re
    s = e(s)
    s = re.sub(r"\*\*(.+?)\*\*", r"<strong>\1</strong>", s)
    s = re.sub(r"(?<![\w*])\*(?!\s)(.+?)(?<!\s)\*(?![\w*])", r"<em>\1</em>", s)
    return re.sub(r"`(.+?)`", r"<code>\1</code>", s)


p = data["paper"]
tiles = "".join(
    f'<div class="tile {e(t.get("tone", "neutral"))}"><div class="tl">{e(t["label"])}</div>'
    f'<div class="tv">{e(t["value"])}</div><div class="ts">{md_inline(t.get("sub", ""))}</div></div>'
    for t in data.get("tiles", []))
# Columns that fill every row: 4 tiles as 2x2, never 3 + 1 orphan.
n_tiles = len(data.get("tiles", []))
tile_cols = 2 if n_tiles == 4 else min(max(n_tiles, 1), 3)
inputs = "".join(f'<span class="chip"><b>{e(k)}</b> {e(v)}</span>' for k, v in data.get("inputs", {}).items())
figs = ""
for f in data.get("figures", []):
    fp = Path(f["path"]); fp = fp if fp.is_absolute() else base / fp
    if fp.exists():
        b64 = base64.b64encode(fp.read_bytes()).decode()
        figs += (f'<figure><figcaption class="ft">{e(f.get("title", ""))}</figcaption>'
                 f'<img alt="{e(f.get("title", ""))}" src="data:image/png;base64,{b64}">'
                 f'<figcaption>{md_inline(f.get("caption", ""))}</figcaption></figure>')
compare = ""
if data.get("compare"):
    rows = "".join(f'<tr><td>{md_inline(r["metric"])}</td><td>{md_inline(r["paper"])}</td>'
                   f'<td class="y">{md_inline(r["yours"])}</td><td class="n">{md_inline(r.get("note", ""))}</td></tr>'
                   for r in data["compare"])
    compare = (f'<section><h2>Paper vs. your run</h2><div class="tw"><table><thead><tr><th>Metric</th>'
               f'<th>Paper</th><th>Your run</th><th></th></tr></thead><tbody>{rows}</tbody></table></div></section>')
idea = "".join(f"<li>{md_inline(b)}</li>" for b in narr.get("idea", []))
abstract = narr.get("abstract", "")
findings = "".join(f"<p>{md_inline(x)}</p>" for x in narr.get("findings", []))
tries = "".join(
    f'<li><strong>{md_inline(t["label"])}</strong> — {md_inline(t.get("why", ""))}'
    f'<pre>{e(json.dumps(t.get("params", {}), ensure_ascii=False))}</pre></li>' for t in narr.get("try_next", []))
cav = "".join(f"<li>{md_inline(c)}</li>" for c in narr.get("caveats", []))
rb = data.get("runbook", {})
fork = (f'<a class="fork" href="{e(rb["url"])}">Fork this runbook on Jetty →</a>' if rb.get("url") else "")

page = f"""<!doctype html><html lang="en"><head><meta charset="utf-8">
<meta name="viewport" content="width=device-width,initial-scale=1">
<title>SMASH 2026 · #{e(p['num'])} · Result card</title>
<style>
:root{{--bg:#f6f4ef;--card:#fff;--ink:#1f2a44;--muted:#5c677d;--line:#e3dfd5;--accent:#d9480f;--good:#2b8a3e;--warn:#e67700;--chip:#efece4}}
@media (prefers-color-scheme:dark){{:root{{--bg:#11151f;--card:#1a2030;--ink:#e8ebf2;--muted:#9aa4b8;--line:#2c3447;--accent:#ff8a4c;--good:#69db7c;--warn:#ffc078;--chip:#232b3d}}
figure img{{background:#fff;border-radius:6px}}}}
*{{box-sizing:border-box}}body{{margin:0;background:var(--bg);color:var(--ink);font:15px/1.55 ui-sans-serif,system-ui,-apple-system,"Segoe UI",Roboto,sans-serif}}
main{{max-width:860px;margin:0 auto;padding:28px 16px 48px}}
.kicker{{font:600 12px/1 ui-monospace,SFMono-Regular,Menlo,monospace;letter-spacing:.08em;text-transform:uppercase;color:var(--accent)}}
h1{{font-size:clamp(22px,4vw,30px);line-height:1.2;margin:10px 0 6px}}.authors{{color:var(--muted);margin:0 0 18px}}.authors a{{color:var(--accent);text-underline-offset:3px}}
.headline{{background:var(--card);border:1px solid var(--line);border-left:5px solid var(--accent);border-radius:10px;padding:16px 18px;font-size:18px;font-weight:600;margin:0 0 18px}}
.chips{{display:flex;flex-wrap:wrap;gap:6px;margin:0 0 18px}}.chip{{background:var(--chip);border-radius:999px;padding:4px 10px;font-size:12.5px}}.chip b{{font-weight:600;color:var(--muted);margin-right:4px}}
.tiles{{display:grid;grid-template-columns:repeat(var(--cols),minmax(0,1fr));gap:10px;margin:0 0 22px}}
@media (max-width:560px){{.tiles{{grid-template-columns:1fr}}}}
.tile{{background:var(--card);border:1px solid var(--line);border-radius:10px;padding:12px 14px}}.tl{{font-size:12px;color:var(--muted);text-transform:uppercase;letter-spacing:.04em}}
.tv{{font-size:26px;font-weight:700;margin:2px 0;font-variant-numeric:tabular-nums}}.ts{{font-size:12.5px;color:var(--muted)}}
.tile.accent .tv{{color:var(--accent)}}.tile.good .tv{{color:var(--good)}}.tile.warn .tv{{color:var(--warn)}}
section{{background:var(--card);border:1px solid var(--line);border-radius:12px;padding:18px 20px;margin:0 0 16px}}
h2{{font-size:16px;margin:0 0 10px}}ul{{padding-left:20px;margin:0}}li{{margin:4px 0}}p{{margin:0 0 10px}}
figure{{margin:0 0 18px}}figure img{{width:100%;height:auto;display:block}}figcaption{{font-size:13px;color:var(--muted);margin-top:6px}}.ft{{font-weight:600;color:var(--ink);font-size:14px;margin:0 0 6px}}
.tw{{overflow-x:auto}}table{{border-collapse:collapse;width:100%;font-size:13.5px;font-variant-numeric:tabular-nums}}th,td{{text-align:left;padding:7px 8px;border-bottom:1px solid var(--line);vertical-align:top}}th{{color:var(--muted);font-weight:600}}td.y{{font-weight:600}}td.n{{color:var(--muted);font-size:12.5px}}
pre{{background:var(--chip);border-radius:6px;padding:6px 8px;font-size:12px;white-space:pre-wrap;word-break:break-word;margin:4px 0 8px}}code{{background:var(--chip);border-radius:4px;padding:1px 4px;font-size:.92em}}
.fork{{display:inline-block;background:var(--ink);color:var(--bg);text-decoration:none;font-weight:600;border-radius:8px;padding:10px 14px;margin-top:6px}}
footer{{color:var(--muted);font-size:12.5px;margin-top:22px}}
.abs{{margin:0;padding-left:14px;border-left:3px solid var(--accent);color:var(--ink)}}
</style></head><body><main>
<div class="kicker">SMASH 2026 · Paper #{e(p['num'])} · Result card</div>
<h1>{e(p['title'])}</h1><p class="authors">{e(p['authors'])}{(' · ' + e(p['affiliation'])) if p.get('affiliation') else ''}{(f' · <a href="{e(p["url"])}">Read the paper</a>') if p.get('url') else ''}</p>
<div class="headline">{md_inline(narr['headline'])}</div>
<div class="chips">{inputs}</div>
<div class="tiles" style="--cols:{tile_cols}">{tiles}</div>
{f'<section><h2>From the abstract</h2><blockquote class="abs">{e(abstract)}</blockquote></section>' if abstract else f'<section><h2>The idea</h2><ul>{idea}</ul></section>'}
{f'<section><h2>What this run shows</h2>{findings}</section>' if findings else ''}
<section><h2>Evidence</h2>{figs}</section>
{compare}
<section><h2>Try next</h2><ul>{tries}</ul>{fork}</section>
<section><h2>Read this before sharing</h2><ul>{cav}</ul></section>
<footer>Generated by a Jetty runbook built from the authors' SMASH 2026 paper. Numbers on this card come from code run in a sandbox; the words were written by an AI agent reading those numbers. This is an interactive companion, not the authors' own results unless labelled “Paper”.</footer>
</main></body></html>"""
Path(sys.argv[3]).write_text(page)
print(f"wrote {sys.argv[3]} ({len(page) // 1024} KB)")
/app/work/validate.py
"""Self-check a SMASH paper-playground run and write validation_report.json (evals v2 shape).

Runs the same checks as the runbook's `## Code Checks` (which Jetty re-runs independently after the agent
exits and substitutes for these entries), adds one `step` entry per runbook step and the agent's checklist
judgements, and prints PASS/FAIL lines.

usage: python validate.py <results_dir> <param,param,...> <budget_sec> [checklist.json]
"""
import html, json, re, sys
from pathlib import Path

R = Path(sys.argv[1])
allowed = set(sys.argv[2].split(","))
budget = float(sys.argv[3])
checklist_path = Path(sys.argv[4]) if len(sys.argv) > 4 else None


def load(name):
    try:
        return json.loads((R / name).read_text())
    except Exception:
        return None


res, cdata, narr = load("results.json"), load("card_data.json"), load("narrative.json")
card = (R / "result_card.html").read_text() if (R / "result_card.html").exists() else ""


def c_outputs_exist():
    missing = [f for f in ["result_card.html", "results.json", "card_data.json", "narrative.json", "summary.md"]
               if not (R / f).exists() or (R / f).stat().st_size == 0]
    return not missing, f"missing or empty: {missing}" if missing else "all 5 outputs present"


def c_results_valid():
    if res is None or cdata is None:
        return False, "results.json or card_data.json does not parse"
    rt = float(res.get("runtime_sec", 0))
    return rt <= budget, f"experiment {rt}s (budget {budget:.0f}s)"


def c_narrative_complete():
    if narr is None:
        return False, "narrative.json does not parse"
    p = []
    if not str(narr.get("headline", "")).strip(): p.append("no headline")
    if len(str(narr.get("headline", "")).split()) > 45: p.append("headline over 45 words")
    if not 1 <= len(narr.get("idea", [])) <= 3: p.append(f"idea has {len(narr.get('idea', []))} bullets, need 1-3")
    if not 1 <= len(narr.get("findings", [])) <= 2: p.append(f"{len(narr.get('findings', []))} findings, need 1-2")
    if any(len(f.split()) > 70 for f in narr.get("findings", [])): p.append("a findings paragraph is over 60 words")
    if not 2 <= len(narr.get("try_next", [])) <= 3: p.append(f"{len(narr.get('try_next', []))} try_next, need 2-3")
    if not 1 <= len(narr.get("caveats", [])) <= 2: p.append(f"{len(narr.get('caveats', []))} caveats, need 1-2")
    return not p, "; ".join(p) or "complete and within the length limits"


def c_try_next_valid():
    if narr is None:
        return False, "narrative.json does not parse"
    bad = sorted({k for t in narr.get("try_next", []) for k in (t.get("params") or {}) if k not in allowed})
    empty = [t.get("label", "?") for t in narr.get("try_next", []) if not t.get("params")]
    ok = not bad and not empty
    return ok, "all try_next parameters are declared" if ok else f"unknown parameters: {bad}; without params: {empty}"


def c_headline_grounded():
    if narr is None or res is None:
        return False, "missing narrative or results"
    blob = json.dumps(res) + json.dumps(cdata or {})
    vals = [float(x) for x in re.findall(r"-?\d+(?:\.\d+)?(?:[eE]-?\d+)?", blob)]
    nums = re.findall(r"(?<![\w.−-])[−-]?\d[\d,]*(?:\.\d+)?(?![\w-])", narr.get("headline", ""))
    missing = []
    for n in nums:
        s = n.replace("−", "-").replace(",", ""); v = float(s); dec = len(s.split(".")[1]) if "." in s else 0
        tol = 0.5 * 10 ** (-dec) + 1e-9
        if not any(abs(abs(x) - abs(v)) <= tol or abs(abs(x * 100) - abs(v)) <= max(tol, 0.5) for x in vals):
            missing.append(n)
    return not missing, f"not found in results: {missing}" if missing else f"{len(nums)} headline number(s) grounded"


def c_card_integrity():
    if not card or narr is None:
        return False, "no card or narrative"
    text = re.sub(r"data:image/[a-z]+;base64,[A-Za-z0-9+/=]+", "", card)
    plain = html.unescape(re.sub(r"<[^>]+>", "", text))
    p = []
    if card.count("data:image/png;base64") < 1: p.append("no embedded figures")
    if re.search(r"\bNaN\b|\bnan%|\bInfinity\b", text): p.append("NaN/Infinity in card text")
    if len(card) > 5_000_000: p.append(f"card is {len(card) // 1024} KB")
    if re.sub(r"[*`]", "", narr.get("headline", ""))[:40] not in plain: p.append("headline not on card")
    return not p, "; ".join(p) or f"card {len(card) // 1024} KB, {card.count('data:image/png;base64')} figures"


CODE_CHECKS = [  # ids and names match the runbook's ## Code Checks headings
    ("outputs-exist", "Result card, numbers, narrative and summary were written", c_outputs_exist),
    ("results-valid", "Experiment numbers are valid JSON and the experiment stayed within its time budget", c_results_valid),
    ("narrative-complete", "The narrative is complete and within the length limits", c_narrative_complete),
    ("try-next-valid", "Every try-next suggestion uses only this runbook's parameters", c_try_next_valid),
    ("headline-grounded", "Every number in the headline appears in the run's results", c_headline_grounded),
    ("card-integrity", "The card embeds its figures, shows the headline, and contains no NaN", c_card_integrity),
]
STEPS = [  # (id, name, evidence that the step happened)
    ("setup", "Set up the sandbox and parameters", Path("/app/work/params.json").exists() or res is not None),
    ("get-code", "Extract the tested code", Path("/app/work/experiment.py").exists() or res is not None),
    ("experiment", "Run the experiment", res is not None),
    ("interpret", "Write the narrative", narr is not None),
    ("render", "Render the result card and summary", bool(card) and (R / "summary.md").exists()),
]

checks = [{"kind": "step", "id": i, "name": n, "status": "pass" if ok else "fail"} for i, n, ok in STEPS]
for cid, name, fn in CODE_CHECKS:
    try:
        ok, msg = fn()
    except Exception as e:  # a check that crashes is an error, never a silent pass
        ok, msg = None, f"{type(e).__name__}: {e}"
    status = "pass" if ok else ("error" if ok is None else "fail")
    checks.append({"kind": "code_check", "id": cid, "name": name, "status": status, "message": str(msg)[:1000]})
    print(f"{'PASS' if ok else 'FAIL'} {cid}: {msg}")

if checklist_path and checklist_path.exists():
    for item in json.loads(checklist_path.read_text()):
        st = item.get("status", "skipped")
        st = st if st in ("pass", "fail", "skipped", "error") else "skipped"
        checks.append({"kind": "checklist", "id": str(item["id"]), "name": str(item.get("name") or item["id"]),
                       "status": st, "message": str(item.get("message", ""))[:1000]})
        print(f"{'PASS' if st == 'pass' else 'FAIL'} checklist {item['id']}: {item.get('message', '')}")
else:
    print("NOTE no checklist.json given; checklist items will be recorded as not reported")

gating = [c for c in checks if c["kind"] != "step"]
verdict = "fail" if any(c["status"] in ("fail", "error") for c in gating) else ("pass" if gating else "unknown")
(R / "validation_report.json").write_text(json.dumps({"version": 2, "verdict": verdict, "checks": checks}, indent=2))
print(json.dumps({"verdict": verdict, "passed": sum(c["status"] == "pass" for c in gating), "gating_checks": len(gating)}))